- The router's provider aliases are now one table, `crewai.llm.PROVIDER_ALIASES`,
and `llm_overlay` compares model names through it: `google/x` and
`gemini/x` are one model whether the llm is built in the block or was
built before it (a prebuilt instance records `gemini`). An exact key still
wins, and an aggregator's route is still compared whole.
- When the declared model's SDK is missing, a caller's explicit
`is_litellm=True` is kept for the mapped model instead of dropping to a
native route.
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
Two review findings on the model-for-model overlay:
- `overlay_model_for_model` took the text after the first slash as another
name for the model, so an aggregator's route (`openrouter/openai/gpt-4o`)
matched a `model:openai/gpt-4o` or `model:gpt-4o` key meant for the
native model. A prefix is now stripped only when it is a native provider's
own and what remains has no slash; an instance on an aggregator is compared
as `<provider>/<its model id>`.
- With a role key and a model key both active, the model key mapped the
declared llm first and the role's model was built like that mapped
instance, losing the caller's key and endpoint. The overlay now remembers
what the caller declared for every llm it built, and a role key is built
from that declaration.
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
`test_openai_completion_module_is_imported` deletes the module from
sys.modules and lets `LLM(...)` import it again, which binds the new module
on `crewai.llms.providers.openai` as well. monkeypatch restored only the
sys.modules entry, so every later test on that worker saw two module
objects for one name: `patch("crewai.llms.providers.openai.completion.X")`
patched the attribute's module while `from ... import X` read sys.modules'.
On Python 3.10 that made tests/llms/azure/test_azure_responses.py fail
whenever it shared a worker with test_openai.py and test_crew_loader.py,
which the new tests' even split now did. The attribute is restored too.
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
`cli_usage:eval_models` carried the `--models` strings as typed, and those
can identify a customer: a fine-tune id, an Azure deployment name, a
self-hosted model or host. A model is now sent by name only when it is an
exact entry of crewAI's model catalog (`LLM_CONTEXT_WINDOW_SIZES`), else as
`<provider>/other`, and a provider crewAI does not route as `other/other`.
An `ft:` id is never sent.
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
`_same_route_provider` now follows `_same_provider`'s rule case for case: a
LiteLLM-routed `LLM(...)` is on the same provider as a native route when its
provider names that native class, so its key and endpoint follow a model
key to another model of the same provider. Another provider still gets none.
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
When the comparison's answer carries `eval_config` and the project has no
eval.jsonc, it is written through `write_eval_config` and the same one line
Mode 1 prints says so. An existing file is never overwritten.
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
Nothing is built on the declared model, so a missing SDK for it is no
reason to fail the mapped build; its credentials cannot be matched to the
new provider, so none are carried.
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
Every create (git or ZIP) and every push (redeploy by name or uuid, or a
ZIP update) carries `[tool.crewai].project_id` when the project has one, so
AMP knows which project a deployment runs and `crewai eval --models` can find
it. The id is read, never minted: a deploy does not rewrite pyproject.toml.
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
`crewai eval --models "a,b"` (and `--deployment UUID` when AMP cannot tell
the deployment from the project id) asks AMP for a models evaluation: the
project id, the models from one comma-separated list (stripped, repeats
dropped, provider/model required, 1-5) and the project's eval.jsonc. It
needs the login, prints and opens the report link, says where the
comparison is while it runs, then prints one row per model (goal, tasks,
agents, tools, cost, time; the deployed one marked, the best per column
starred) and the top three suggestions. Exit 0 when it finished, 1 when it
failed or could not start. Everything from the wire is printed as Text.
The comparison is counted as `cli_usage:eval_models` once AMP accepts it.
Mode 1 now sends the project id with `create_evaluation` too, so every
evaluation is filed under the project it is about.
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
The span `crewai eval --models` records carries whether the caller was
logged in, the models compared (provider/model names) and how many, in both
telemetry classes. Nothing about the run, its output or the organization.
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
A key `model:<provider/model>` maps every LLM built from that model string
inside the block, and `model:*` every LLM built from any model string. That
reaches what a role cannot: a flow step's own `LLM(...).call()`. The key is
read in `LLM.__new__` (and so `create_llm` and an agent's `llm="..."`), and
on an agent's declared llm built outside the block; a role key still wins for
that agent. The caller's settings follow the mapped model by the rule a
declared llm's do. `MODEL_KEY_PREFIX` is public so another package can
feature-detect the form.
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
Since 1.15.22 every crew and flow kickoff owns an execution uuid, so the
legacy TraceBatchManager handlers never finalize a batch and the
`tracing:ephemeral_sent` / `tracing:authenticated_sent` Feature Usage
events stopped. Emit them from GrantSpanExporter.record_export, the point
both upload tiers reach once every span has arrived.
Co-authored-by: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
* feat(llms): centralize context window definitions
* refactor(llm): use shared context window resolver
* refactor(llms): share native context window lookup
* test(llms): cover context window parity
* fix(llms): preserve regional Bedrock context window
* chore(llms): refresh provider context window catalogs
* fix(llms): restore affected model context windows
* fix(llms): add active Azure and Anthropic context windows
Record catalog limits for current Azure OpenAI and Claude model IDs so lookups match the providers' active context windows.
* fix(llms): sync Gemini and Bedrock context windows
Drop retired catalog IDs and record the active Gemini and Bedrock text-model limits from the current provider docs.
* fix(llms): add missing OpenAI context windows
Record active OpenAI IDs that do not match an existing prefix, including gpt-5.6-cyber so it keeps its 400k window.
* fix(llms): keep Gemini thinking snapshot window in sync
Restore the retired thinking snapshot so native Gemini and LiteLLM resolve the same 1M context window.
* test(llms): drop retired Gemini thinking snapshot from parity
The model is no longer in the Gemini catalog, so native and LiteLLM no longer need to agree on its context window.
* test(llms): expect Azure GPT-4 and GPT-4o to share a 128k window
Azure GPT-4 is no longer smaller than GPT-4o, so the comparison asserted equal usable windows.
* fix(llms): address context-window review findings
Keep provider catalogs from overwriting each other, restore Gemma and legacy Bedrock Claude windows, and match the global Kimi inference id.
* fix(llms): drop unused context-window re-exports from LLM
Import the usage ratio from context_window in tests so llm.py no longer re-exports unused constants.
* fix(cli): `crewai eval` exits 1 unless the gate passed, and says to log in when nothing was traced unattended
The exit code is what a CI job reads, and it said only whether the evaluation
finished: a run whose goal gate FAILED exited 0, so a pipeline gating on
`crewai eval` waved it through. It is the gate's now — 0 only for PASSED; a
failed gate, one without a verdict, and an evaluation that stopped are 1. The
command's help says so.
With no terminal and no login, an anonymous run's trace stays on the machine
even with tracing on (nobody is there to approve the upload). `crewai eval` then
told the user to turn tracing on, which they had — the same loop again. When
tracing is on and nobody is logged in, it now says what traces an unattended
run: `crewai login`.
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
* fix(cli): an unreadable login is the reason given when nothing was traced unattended
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
* fix(cli): print the unattended reason as text, never markup
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
---------
Co-authored-by: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
* fix(tracing): turning tracing on is the answer; stop asking again
Two things a user who ran `crewai eval` sees today.
`crewai eval` offers to turn tracing on and run the crew. The run finishes —
and the ephemeral buffer asks "Share this execution trace with CrewAI?", which
is the same question again. Turning tracing on IS consent: `tracing_asked_for()`
is true when `CREWAI_TRACING_ENABLED` says so or when `tracing=True` was passed
in this context, and the buffer takes it as the answer. First-time
auto-collection still asks, because nobody asked for that one.
And the offer named the mechanism rather than the effect — "Turn tracing on
(CREWAI_TRACING_ENABLED=true stays in .env) and run the crew now?", then
"Tracing is on for this project (CREWAI_TRACING_ENABLED=true in .env)." The
variable is how it works, not what the user is agreeing to; both lines now say
what happens and leave the plumbing to the .env file it is written in.
491 telemetry tests and 62 eval-CLI tests green.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(tracing): the TUI's modal is a prompt too, and say where traces go
Two follow-ups from running it.
The terminal UI installs its own consent callback, so turning tracing on still
bought a modal at the end of the run — the callback is consulted before the
default prompt, and the check only guarded the prompt. A host's callback stays
authoritative, because an embedder may answer no for reasons of its own; what
changed is that the TUI's callback, which exists to ASK, now answers for itself
when tracing was asked for.
And having taken the variable out of the offer, the offer should say what saying
yes means: "Turn tracing on and run the crew now? The run's trace is sent to
CrewAI AMP", and afterwards "Tracing is on for this project — its runs are
traced to CrewAI AMP."
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(tui): an Evaluate button beside View Traces and Deploy
A run finishes in the terminal UI and the next question is usually "was that
any good?" — which `crewai eval` answers, from the command line, about the run
that just happened. The button is there now, with `e` bound to it.
It behaves like Deploy rather than like View Traces: it leaves the UI and then
runs the command, because `crewai eval` talks — it prints the link to follow,
waits for the verdict and prints that — and none of it belongs inside a
full-screen app. It calls `eval_crew()` itself rather than reimplementing any
of it, so the button and the command can never say different things; a clean
SystemExit is the command deciding, and a failure is reported without failing
the run that already succeeded.
Declarative flows get it too — same button, same tail.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(telemetry): count `crewai eval`, not only the button that runs it
The TUI's buttons each record a `cli_usage:` feature span, so the new Evaluate
button was counted — but the command it runs was not, and most people will type
`crewai eval` rather than press a button. Every evaluation now records
`cli_usage:eval`; the button keeps its own `cli_usage:evaluate`, so the
difference between the two is how many were started from the TUI.
It counts the command and nothing about the run: no id, no project, no verdict.
And it is wrapped like every other telemetry call here — a missing tracer or a
refused span never stops an evaluation.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(telemetry): say which run was evaluated, and by whom
`project_id` already rides every span. What only this command knows is which
run is being graded, whether the caller was logged in, and — when they are —
which organization they are logged in to. A feature span can carry attributes
now, and `cli_usage:eval` carries those three.
What it does not carry is anything about the work: no inputs, no output, no
verdict, no criteria. The execution id is the join key; what was found lives in
AMP, where the evaluation itself is.
An anonymous caller reports `authenticated=false` and an empty organization, and
is not asked for one.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* Address the review: a terminal, a thread, and the right run
Three findings worth acting on, one already fixed, and ruff.
**The security review is right.** `prompt_user_for_trace_viewing` fails closed
where no one can answer, so an anonymous run in CI has never uploaded. Treating
the switch as consent everywhere would have changed that: a project `.env`
copied into CI carries the variable, not the person. `tracing_asked_for()` now
answers only where a prompt could have been shown — the double-ask this PR is
for happens in a terminal, and nothing else moves.
**The ContextVar never crosses the worker.** `set_tracing_enabled` runs in the
crew's validator, on the thread the crew was BUILT on, and a flow never sets it
at all — so `tracing=True` without the env var still opened the modal. The TUI
reads the declaration off the object as well: the same yes, wherever written.
**The button now names the run it watched.** `_chain_eval()` called `crewai eval`
with no id, which looks up the last recorded run — a PREVIOUS run when this one
was not traced, and an offer to run the crew again when there is no record at
all. The TUI remembers what was recorded before the run, hands the new id to the
command, and says "this run was not traced" rather than grading someone else's.
**Already fixed**: telemetry is recorded after `get_or_create_project_id()`, not
before — that moved when the span gained its attributes.
492 telemetry tests, 187 CLI tests. Ruff format and check clean.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* Close all three doors the prompt closes, not just the terminal
The security review named three places `prompt_user_for_trace_viewing` fails
closed — no terminal, a suite under test, and a host that suppressed tracing
messages — and the first pass only honoured the terminal. A run under test, or
inside a host that asked for silence, could still have uploaded on the strength
of a variable.
The three conditions are one function now, `_prompt_can_be_shown()`, used by the
prompt itself and by `tracing_asked_for`, so the rule and the prompt it answers
cannot drift apart. Where the question could not have been put to anybody, there
is nothing to answer and nothing leaves the machine.
The terminal UI decides for itself, and says why: it silences crewAI's console
to keep it out of its own layout, which is a reason a PROMPT cannot be shown,
not a reason to ask a second time — it has a screen and somebody in front of it.
494 telemetry tests, 88 TUI tests. Ruff clean.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* Tests: a real session for the consent rule, and a laid-out screen for a click
The rule that a declared CREWAI_TRACING_ENABLED needs no modal only holds
where a prompt could have been shown, and a test suite is one of the places
it could not — so the three cases about a real session say a person is here.
The consent click waited for the screen, which is not the same as waiting for
its buttons to have a region; it now waits for the layout it clicks on.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* A run started for an evaluation closes itself, even in a child process
A project's crew and flow are run through `uv run …`, so the app lives in
another process and the ContextVar saying "an evaluation is waiting" never
reaches it: the screen stayed open and `crewai eval` waited behind it, which
is the trap the handshake was meant to remove. The environment is the one
thing that crosses into that process, so the command sets a variable there and
clears it after; the id travels back the way it already did, through the
project's last-run record. A run that FAILED leaves too — the command behind
the screen has its own way of saying there is nothing to grade, and it cannot
say it while somebody has to quit a screen first.
And the spans a run exports reach AMP a moment after the run ends, sometimes
later than that, so a command that just watched the run would ask for a trace
still in flight and be told, correctly and uselessly, that there is nothing
there. A run we know is fresh now waits up to two minutes and says it is
waiting; an id somebody typed fails at once, as it always has.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* The evaluation happens in the app, on the screen the reader is already on
Closing the app the moment the run ended and leaving somebody in a bare
terminal, waiting some seconds for a link to appear and a browser to open, is
worse than the screen it replaced. So the evaluation runs where the run does:
`Evaluating this run` under the run's own line, the report link beside it, the
browser opened from there, and `Goal gate PASSED · goal 5/5 · …` when it comes
back. Nothing closes; the reader leaves when they are done reading, and the
link is printed once more on the way out so it outlives the screen.
The Evaluate button does the same thing now instead of quitting the app and
chaining into the command, so there is one implementation of one experience —
`_chain_eval` and `_want_eval` are gone. Pressing it again opens the report it
already made rather than paying for a second evaluation.
Underneath, `crewai eval`'s two steps became callable as values: they raise
`EvaluationStoppedError` with the sentence to show instead of printing and
exiting, and `evaluate_run()` is the app's one door — the url as soon as AMP
gives it, every unfinished answer while it waits. The command keeps the
terminal wording it had; when it ran the crew itself, it now has nothing left
to say and steps aside for the app it opened.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* The button says which report it opens
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* The button works while it waits: it spins, and it stays pressable
A dimmed label that never moves reads as a screen that has stopped. The
Evaluate button now carries the same spinner the run's own line does, the
clock goes back up to eight frames a second while the evaluation runs, and the
button is no longer disabled — the report page is where the progress is, so
pressing it while it waits is the useful thing to do.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* View Traces opens the traces
The button never had a link. crewAI grants one for every exported run and
prints it after a run — but never under a TUI, where its console is kept out
of the layout — so the app had nothing to open and said so, which read as a
feature that had stopped working.
The link is now recorded beside the rest of what crewAI writes when a run's
spans reach AMP, and the button reads it off that record, matched to THIS
app's execution rather than to whatever ran last in the project. When there is
no link the notice says which of the two reasons it is: a run nobody traced,
or a traced run AMP granted no viewer for — only one of those is the reader's
to fix.
Verified against a real anonymous run: pressing `t` opens
app.crewai.com/crewai_plus/ephemeral_traces/<id> and shows it.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* The review's five: a trust boundary, a fallback, a retry, an exit and a count
**A project's `.env` cannot lend itself the login.** `evaluate_run()` built its
AMP client after the project's `.env` had been loaded with override, so a
`CREWAI_PLUS_URL` a project put there landed in the set of origins trusted with
the saved `crewai login` bearer. The command reads that variable BEFORE the
`.env` — a shell export is this machine speaking — but inside the app there is
no such "before", so the variable is left out of the set entirely. The request
still follows it; the credential does not.
**A run no app evaluated is still evaluated.** The command returned as soon as
a trace existed, assuming the app had graded it — but a conversational session
never ends the way a crew does and a flow with human feedback takes the
terminal instead, so `crewai eval` could exit 0 having graded nothing. The app
now leaves a marker naming the run it started evaluating, and the command
grades anything that marker does not name.
**An evaluation that stopped can be tried again.** The button re-enabled itself
after a failure but the action still treated any existing evaluation as
finished, so a 502 could only be escaped by re-running the crew.
**A login that exits is shown on screen.** `saved_login()` fails by exiting,
which is not an `Exception` and so slipped past the worker's hands: the button
could sit on "Evaluating…" forever with the reason gone with the exit.
**An evaluation the app runs is counted.** `cli_usage:eval` is the count of
evaluations that begin, and the ones that begin in the app were missing from
it.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* A stop is a sentence, and the app's own word settles what it graded
**"1" is not a reason.** A credential that exists but cannot be read stopped
the evaluation by printing its sentence and exiting — under the app the print
lands beneath the layout and the exit carries only a code, so the screen said
`1`. `saved_login()` now raises the stop like everything else that stops an
evaluation, the command catches it where it builds the client and prints it as
before, and the app shows it. The test that claimed to cover this raised a
`SystemExit` carrying a sentence, which is not what `_fail` raises; it now
breaks the credential store and reads what reaches the screen. The worker
still catches an exit, and says that the reason did not survive rather than
echoing its code.
**The record is the project's last finish, not this run.** Another run
finishing in the same project replaces it while the app is open, so "is the
marker about the id in the record" could send the command off to evaluate a
different execution. The marker is now the app's own word about the run it
watched — the id it evaluated, or null when it looked and found nothing to
grade — and the command trusts it over the record, matching on time rather
than on an id that may already have been overwritten. No marker still means no
app got here, which is the conversational session and the flow that takes the
terminal, and the command grades those itself.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* A project can say what good means, and `crewai eval` carries it
An evaluation grades a run against the crew's own `expected_output`s — which
is the prompt that produced the output, so it catches a crew that ignored its
own contract and nothing else. What discriminates lives in criteria somebody
writes, and there was nowhere to write them.
Now there is. After the first evaluation the criteria it used are written to
`eval.jsonc` in the project — once, never over a file that exists, because the
one thing worse than no criteria is criteria that vanish whenever somebody
evaluates — and the line that says so points at what to do with it. From then
on the file travels with every evaluation, as it was written, comments and
all: what a criterion means is the grader's to read, not this command's.
Both doors do it, since most evaluations now happen inside the run app: the
app writes the file and names it in the line that outlives its screen, and
`crewai eval` in a terminal says it there.
The file is bounded at the same 64KB AMP holds the field to, so one that would
be refused is never uploaded and the run is graded anyway.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* The review's asks: anonymous eval stats, a handshake a project cannot forge
Usage stats are anonymous, so the `crewai eval` count says whether the caller
was logged in and nothing else — no execution id, no organization (the product
decision on this PR). Which runs were evaluated, and by whom, is AMP's record.
A feature span now keeps only the keys its own feature lists, in both
telemetry classes; everything else — the dimensions every span carries
included — is dropped.
The run app's "an evaluation is waiting" handshake was an environment variable
any project's `.env` could set, which would start an evaluation with the
machine's login on a plain `crewai run`. Its value is now a random token that
counts only while the command's file of that name exists in the user's crewAI
data directory; a `.env` cannot create a file.
And three smaller ones: when no app evaluated the run, the command grades the
project's record only if it was written after this run began; the "Wrote
eval.jsonc" line after the app closes now appears (the key it read was never
set); an oversized eval.jsonc is said once, through the caller's note, rather
than printed under the TUI on every retry.
uv.lock is back to main's: the change was re-resolution drift, nothing this PR
needs.
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
* A report link is a web address, and an anonymous request names no organization
Two from the security review of 52fa5f3ae.
The report url comes from whichever AMP answered — which a project's `.env`
may choose — and is printed as a link and opened without a click. It is now
checked where it arrives, before anything shows or opens it: HTTPS, or plain
HTTP to this machine, no credentials in it, no control characters. Anything
else costs the link and nothing more. The host is not pinned: the report is
served by the evaluation service, not by AMP.
A request sent without the login — nobody logged in, or an AMP this machine is
not logged in to — no longer carries the saved organization id. AMP reads it
only beside a credential, so it said nothing to AMP and told an AMP the login
does not go to which organization was asking. Dropped, as anonymous trace
grants already drop it.
Co-Authored-By: Claude Opus 5.5 (1M context) <noreply@anthropic.com>
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(deps): pin instructor <1.16 to keep OpenAI Mode.TOOLS registered
instructor 1.16.0 removed the OpenAI Mode.TOOLS handler in favor of
Mode.RESPONSES_TOOLS. `InternalInstructor` calls `instructor.from_provider`,
which still defaults to Mode.TOOLS internally, so any native-OpenAI kickoff
that hits a structured-output path (guardrails, output_pydantic, LLM
guardrails) fails immediately with `ModeError: Mode.TOOLS is not registered
for provider Provider.OPENAI`.
Cap the range while we teach `_create_instructor_client` to negotiate a
supported mode against `mode_registry`.
Refs COR-861 (Docusign, deployment 134108).
Co-Authored-By: Claude Opus 4.7 (1M context) <noreply@anthropic.com>
* fix: avoid redundant cache saves in tests workflow
Co-authored-by: vinibrsl <5093045+vinibrsl@users.noreply.github.com>
* docs: explain instructor compatibility pin
Co-authored-by: vinibrsl <5093045+vinibrsl@users.noreply.github.com>
---------
Co-authored-by: Daniel Minella <dminella@Mac.home>
Co-authored-by: Claude Opus 4.7 (1M context) <noreply@anthropic.com>
Co-authored-by: copilot-swe-agent[bot] <198982749+Copilot@users.noreply.github.com>
Nothing about the command changes. It is still `crewai eval`, still listed in
`--help`, still takes `--run`, still prints the same lines. Only the module
moved, from `crewai_cli/eval_crew.py` to `crewai_cli/experimental/eval_crew.py`,
with its tests alongside.
The package says what the command's location could not: its output and its
options may change between releases without the deprecation cycle a settled
command gets. That is honest about where it stands — most of what it depends
on lives outside this repository, in an AMP endpoint and the evaluator behind
it, and both are new enough that the report's shape is still moving. The
command is already built to absorb some of that, printing whatever the
evaluation graded rather than a list of its own, but the promise it makes to a
user should match.
`crewai/experimental/` has the same role on the library side, so this is the
convention the repository already has rather than a new one. The CLI had no
experimental package before; it does now, and `crewai eval` is its first
tenant.
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
`crewai eval` printed a fixed tuple of area names. The areas belong to the
evaluation, not to the client, so a fixed list does two wrong things the
moment the evaluator's vocabulary moves ahead of an installed CLI: it drops
every area it has not heard of, and it invents "not measured" for ones that no
longer exist. A user would see one real grade and three phantom blanks, with
no sign that anything had been dropped.
It now prints the areas it was sent, in the order they arrived. The verdict is
still validated exactly as before — a grade is an int in 1..5 or null — so a
malformed payload is still a protocol error rather than something printed.
This lands before the evaluator's own change so that an installed CLI keeps
working through the rollout rather than after it.
* feat(cli): crewai eval evaluates the last traced run through AMP
`crewai eval` reads `.crewai/last_run.json` — the record crewAI writes
when a traced run's spans reach Wharf — and asks AMP to evaluate that
run: POST /crewai_plus/api/v1/tracing/evaluations with the execution id,
sending the saved `crewai login` when there is one and nothing otherwise.
AMP answers with an evaluation id and a URL; the command prints the URL,
opens it, waits for the verdict and prints it (goal gate and the four
grades), exit 1 only when the evaluation itself failed. `--run
EXECUTION_ID` evaluates another run.
With no traced run recorded it offers to turn tracing on for the project
(`CREWAI_TRACING_ENABLED=true` in .env, set_key so nothing else in the
file moves) and run the crew now with `crewai run`; without a terminal, or
declined, it prints the three steps instead. A run that leaves no record
behind is explained, never guessed at.
AMP's refusals are printed in its own words: a run that needs an account
(401 account_required), a refused credential (then `crewai login`), a run
AMP does not hold (404), rate limiting (429 with Retry-After), and any
other status with AMP's message. The two AMP calls live on the CLI's
PlusAPI subclass, so no crewai-core release is needed.
Who may evaluate what is AMP's decision, not the command's: an anonymous
run once without an account, then it needs one; a run traced while logged
in for that organization's members; a deployment execution for members
who may see its traces.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(cli): crewai eval — guard the project, survive AMP blips, name the right subject, read the whole record
Review findings, each reproduced before the fix:
- The run-it-now offer wrote CREWAI_TRACING_ENABLED into ./.env before
checking the directory is a crewAI project, then run_crew() died on a
missing pyproject.toml with a traceback. Now: no pyproject.toml → one
sentence, exit 1, nothing written.
- httpx errors (AMP unreachable, a timeout) surfaced as tracebacks. Now
the start says "Could not reach AMP to start the evaluation: …"; while
waiting, an unreachable AMP or a 5xx is retried up to POLL_RETRIES
consecutive times, then reported with the URL — the evaluation keeps
running server-side either way.
- The POST now carries a 120 s timeout (AMP reads the run's spans inside
it), the poll 30 s.
- A 200 whose body has no known status (a non-dict, no status, a status
outside queued/running/done/failed) polled forever. Now it stops with
the status it saw and the URL.
- A 404 without a JSON message read "AMP holds no run <evaluation id>"
while polling. _refused takes "run <id>" / "evaluation <id>" and says
"AMP answered 404 for <subject>" — AMP's own message still wins.
- The record's amp_base_url was ignored; the CLI now evaluates the run at
the AMP it was traced to. --run keeps the configured AMP.
- The post-run explanation names the third cause: a crewai older than the
version that records the last run.
Tests for each, plus the previously untested paths: Ctrl-C exits 130, a
2xx without an id, a refusal mid-poll, DMN opens no browser, --run skips
the offer. 51 passed in lib/cli/tests (eval + plus_api).
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(cli): crewai eval — the credential goes only to the configured AMP; an explicit yes before running the crew; a done answer needs a well-formed verdict
Review findings (CodeRabbit, the PR gate):
- The record's amp_base_url was handed to PlusAPI beside the saved login,
so a modified .crewai/last_run.json could send the token to any origin.
The client is now built from the configured AMP only (CREWAI_PLUS_URL,
the saved settings, app.crewai.com); the project's .env is loaded first,
as `crewai run` loads it, so the configured AMP is the one the run was
traced to. A record naming another address gets a one-line note and no
credential.
- The offer to turn tracing on and run the crew defaults to no and says
the .env change stays; Enter no longer spends a crew run.
- A `done` answer whose verdict is missing or malformed (no gate, grades
not an object, a grade not an int or null) is a protocol error, exit 1,
instead of an INCONCLUSIVE line with exit 0 or an AttributeError.
Tests for each: a foreign origin in the record with a saved token, the
.env-loaded same-AMP case, seven malformed verdicts, the prompt's text and
default. 59 passed (eval + plus_api); ruff and mypy clean.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(cli): crewai eval — Enter accepts the offer to run the crew (y/n, Y default; the prompt names both effects)
João's call (2026-09-20): the confirm is y/n with Y as the default. The
prompt still says tracing stays on in .env and that the crew runs now.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
---------
Co-authored-by: Claude Fable 5.1 <noreply@anthropic.com>
* feat(tracing): record the last traced run for crewai eval instead of printing it
After a traced run, crewAI printed a panel with the execution id and a
viewer link. The id is internal, and the panel exposed it for no purpose a
user has. Nothing is printed now. Instead, once the run's spans have
reached Wharf, crewAI writes `.crewai/last_run.json` in the project: the
execution id, when the run started and ended, whether it was traced
anonymously or under an account, and the AMP base url. `crewai eval` reads
it back, so the user evaluates their last run without pasting anything.
GrantSpanExporter.record_export replaces show_trace_summary at the two
finish points (an authenticated run's shutdown, an anonymous run's share).
Only a run whose every export succeeded is recorded — a partial export
would name a run the grader could not read whole. Recording is silent in
the TUI and under message suppression too, off under the test suite, and
inert inside a deployment, where the platform binds the execution before
crewAI's own tracing starts. The record is written atomically and a write
failure never fails the run.
The crew, flow and json_crew scaffolds now ignore `.crewai/` like the
declarative flow scaffold already did.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(tracing): never record a truncated ephemeral run; resolve the record path inside the guard; pin the window and the once
- An ephemeral buffer that dropped spans at its cap still uploaded the rest
and recorded the run. The grader could not read that run whole, so it is
no longer recorded (the upload still happens). Test added.
- last_run_path() ran before the try in record_last_run; a cwd that
vanished mid-run would have raised out of a function documented never to
raise. It is inside now, with the same debug log and None.
- Tests: the "recorded once" check counted an unchanged mtime, which proves
nothing on a coarse filesystem — it now counts calls to record_last_run;
the first-start/last-end fold across export batches had no value test —
batches now arrive out of order and the ISO window is asserted.
- Docs: the conversational-flows comment said "one trace link" for output
that no longer exists; tracing.mdx now names .crewai/last_run.json, what
it holds, who reads it, and when it is not written. en, ar, ko, pt-BR.
85 passed (test_session_trace_export + test_last_run); ruff and mypy clean.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(tracing): a temporary file of its own per writer; the docs name deployments
- record_last_run wrote every record through one `.tmp` name, so two crews
finishing together in one project could replace each other's temporary
file and one record was lost. Each write now goes through
tempfile.mkstemp in the same directory, then os.replace; a failed write
removes its own temporary file. Tests: two writers use two names and
leave only last_run.json; a failed replace leaves nothing behind.
- tracing.mdx (en, ar, ko, pt-BR): nothing is recorded inside a
deployment, where the platform owns the trace.
87 passed (test_last_run + test_session_trace_export); ruff and mypy clean.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(tracing): the run that finished last stays recorded, whichever writer comes last
Two crews finishing together in one project: the older run's writer could
reach the file after the newer one and leave the older run as "the last".
record_last_run now compares finished_at (recorded_at when absent) with
the record already there and keeps the later-finished run; the same run
recorded again (a refreshed grant) and a record without a comparable time
never block the run just finished. No lock file: the file is a convenience
pointer and the compare closes the ordering, leaving a microsecond window
between read and replace that two runs finishing in the same instant
could hit — either is then a fair "last run".
Test: the older writer replaces after the newer one; the newer stays.
88 passed.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(tracing): a same-millisecond tie keeps the record already there; nothing is recorded inside a deployment
- The times in the record are stored to the millisecond; two runs finishing
in the same millisecond compared equal and the later writer won, which
could leave the older run recorded. A tie now keeps what is there. No
finer order is worth a field in the file.
- recording_enabled() is false when the platform's integration token is
present: a deployment normally never reaches this code (the host binds
the trace before crewAI would start its own), but a container that did
not would have written a file the platform never reads, against what the
docs promise. Test added.
89 passed; ruff and mypy clean.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(tracing): only a run that provably finished later holds the record
My previous commit compared `finished_at` and fell back to `recorded_at`,
which broke two existing tests on CI: two records written in the same
millisecond with no completion time compared equal, so the second write was
dropped and the older run stayed. Locally the two writes happened to land in
different milliseconds, so the suite passed — a timing-dependent bug, not a
CI quirk.
The rule is now narrow: a write stands unless the record already there is a
DIFFERENT run with a later `finished_at`. No completion time on either side,
the same run recorded again, or a tie to the millisecond all leave the write
to stand, so "the last run recorded" stays what a reader gets. The case the
rule exists for is unchanged: the older-finished writer arriving last does
not replace the newer one.
485 passed in lib/crewai/tests/telemetry (test_last_run run five times for
timing); ruff and mypy clean.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(tracing): serialise the write across processes; drop the platform-token guard, which was not a deployment test
- Reading the record, deciding and replacing it are now one step, held
under a lock file beside the record, so a writer can no longer decide
against a record another process has already replaced. Where the platform
has no flock the write goes ahead unserialised: the record is a
convenience pointer for `crewai eval`, never worth failing a run over.
The regression drives three writers at once and fails without the lock.
- The deployment guard I added yesterday read
CREWAI_PLATFORM_INTEGRATION_TOKEN, which is not a deployment marker:
`crewai create crew` writes that token into a project's own .env for
platform tools, and crew_base loads it, so the guard would have stopped
recording for every developer who uses them. It is also unnecessary — a
deployment kicks off with tracing off, so crewAI never builds the
exporter and never reaches this module. Guard removed, with a test that
a project carrying that token is still recorded.
- The module docstring claimed the platform "binds the execution before
crewAI would start its own tracing". It does not; it sets tracing off at
kickoff. Docstring and the four tracing docs now say the real reason.
487 passed in lib/crewai/tests/telemetry; ruff and mypy clean.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(tracing): a refused lock still records the run; the platform-token test exercises the real guard
Two Cursor findings on the locking commit.
- If flock itself failed — some network mounts refuse it — the OSError
escaped _exclusive, the outer handler deleted the temporary file and
record_last_run returned None, so the run was not recorded at all.
A refused lock is now logged and the write goes ahead unserialised,
matching what already happened when the lock file could not be opened
or flock does not exist. Unserialised beats not recorded.
- test_a_project_using_platform_tools_is_still_recorded used the `project`
fixture, which stubs recording_enabled — the very thing under test — so
the regression it guards could have come back green. It now stubs only
project_dir and asserts the real guard.
13 in test_last_run, 489 across lib/crewai/tests/telemetry.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
---------
Co-authored-by: Claude Fable 5.1 <noreply@anthropic.com>
* feat(tracing): record the task's declared output format, the agent's prompt and answer, and the tool cache flag on their spans
A reader of a run's OTel spans could see a task's raw output but not the
format it declared, nor whether a Pydantic object or a JSON dict actually
came out of it; could see an agent's goal, backstory and model but not the
prompt it was handed or the answer it gave; and could see a tool's result
but not whether the tool ran or the cache answered.
execute task: crewai.task.output_format (json / pydantic / raw; from the
declaration on start and failure, from the TaskOutput on completion),
crewai.task.output_pydantic_produced, crewai.task.output_json_produced.
execute agent: gen_ai.input.messages carries the task prompt and
gen_ai.output.messages the answer, the spec shape the task span already
uses for its own text, under the existing per-attribute byte cap with the
.truncated / .original_size_bytes markers when cut.
call tool: crewai.tool.from_cache.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* test(tracing): the agent's prompt and answer leave under the two standard message keys and no other
Pins the review decision on #7597: the text travels as
gen_ai.input.messages / gen_ai.output.messages — the keys the call llm
span already exports its messages under — so a rule an exporter or a
redaction processor applies to LLM content by key name applies to the
agent span unchanged. A copy under a crewai.agent.* key would fail this.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
---------
Co-authored-by: Claude Fable 5.1 <noreply@anthropic.com>
* fix(llm_overlay): a role and a key that differ only by surrounding whitespace match
A role that comes from a YAML file often ends in a newline — `role: >`
folds to "Researcher\n" — and a caller writes the key for the clean text,
"Researcher". The two never matched, so the agent kept its declared llm
without a word: the overlay looked active and did nothing.
`llm_overlay(mapping)` now sets a copy of the mapping with the whitespace
around each key dropped, and `overlay_model_for(role)` strips the role
before looking it up; an empty or None role matches nothing. Matching is
otherwise unchanged: exact text, no case folding. The mapping the caller
passed is not touched. The three readers (Agent at construction and after
interpolation, LiteAgent at construction) already go through
overlay_model_for, so they pick this up with no change of their own.
Tests: a key "Researcher" matches "Researcher\n" and " Researcher "; a
key written with a trailing newline matches a clean role; case and inner
whitespace still miss, as do "" and None; the caller's mapping is not
mutated; a YAML-folded template role matches after interpolation.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(llm_overlay): two keys that are one role with different models are refused
Review on #7572 (CodeRabbit, iris-clawd): after stripping, "Researcher" and " Researcher " are one key, and the
later entry silently won — the model an agent ran on depended on dictionary order. `_stripped` now refuses a
mapping that names one role twice with different models (ValueError naming the role and both models) and keeps a
harmless duplicate that names the same model once. A test pins both.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
---------
Co-authored-by: Claude Fable 5.1 <noreply@anthropic.com>
* feat(llm): re-resolve llm_overlay after input interpolation rewrites an agent's role
llm_overlay (#7500) resolves an agent's model at construction, by its role text.
A CrewBase crew declares roles as templates in YAML — "Researcher for {repo}" —
that Crew._interpolate_inputs rewrites at kickoff, after construction. An overlay
keyed by the interpolated role, which is the text every trace records, never
matched: on a production flow a plan routed 3 of 5 agents and left the two
templated ones on their declared model.
Agent.interpolate_inputs now looks the overlay up again when the rewrite changed
the role: a key sets llm to the mapped model (create_llm, as construction does),
carrying the streaming flag Crew.kickoff(stream=True) set on the instance it
replaces; a miss, no active overlay, or an unchanged role leaves llm exactly as
it is — construction's resolution and instance stand, nothing reverts. The
executor binds agent.llm per task, after interpolation, so the task runs on the
new model (pinned through prepare_kickoff). Not followed by the swap, documented:
a task's string guardrail LLM, an auto-created Memory LLM, the crew_creation span.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(llm): read llm_overlay once per agent — a re-validation must not replace an llm the agent already runs on
Found while battle-testing the previous commit with real calls: the event bus registers
an agent in its RuntimeState the first time it emits, and RuntimeState(root=[agent])
re-runs Agent.post_init_setup on the same object. Inside a block that maps the agent's
role, the construction-time overlay read (#7500) then replaced the llm the agent was
already running on and dropped the state set on it (stream=True). An agent built outside
the block picked the mapped model up on its second standalone kickoff inside one, against
#7500's own contract; Crew.replay inside a block did the same.
A private flag marks the construction-time read as done; a re-validation keeps the llm the
agent has — the one construction resolved, or the one interpolate_inputs set when the
role changed. Copies (kickoff_for_each) are new instances and read the overlay as before.
Zero-cost tests through RuntimeState; docstrings corrected (a crew Memory built at kickoff
does follow the swap; a stream must be iterated inside the block).
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
---------
Co-authored-by: Claude Fable 5.1 <noreply@anthropic.com>
Apply the same contextlib.closing pattern accepted in #7493 to the nine
remaining library-side sqlite3.connect sites: SQLiteFlowPersistence
(init_db, save_state, load_state, save_pending_feedback,
load_pending_feedback, clear_pending_feedback) and SqliteProvider
(checkpoint, prune, from_checkpoint). The connection context manager
only commits or rolls back, so the connections survived in a reference
cycle and kept flow_states.db / checkpoint databases locked on Windows.
Also close the read-back connections in test_checkpoint.py, which made
its TemporaryDirectory cleanup fail on Windows for the same reason.
Add lifecycle and failure-path regression tests.
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
For response_model calls the messages are flattened into one prompt for
InternalInstructor with an f-string, so a multimodal content list reached the
model as its Python repr. AGENTS.md's "Message Content" section says never to
str() the content; use message_content_text() instead.
* Support private app connections
App selectors only accepted UUID connection identifiers, so apps=["github@private"] failed validation.
Accept connection aliases and route them through Clipper like UUID identifiers. This supports private connections and future platform aliases without client releases.
* chore: update tool specifications
---------
Co-authored-by: github-actions[bot] <41898282+github-actions[bot]@users.noreply.github.com>
* feat(cli): record why a deployment create failed
`crewai deploy create` counts every attempt (`Create Crew Deployment`) and every
success (`Crew Deployment Created`), but the gap between them carried no cause:
among clients able to emit the success span, the CLI succeeds 96.7% of the time
and the run TUI 36.4%, and nothing said why. A third span, `Crew Deployment
Failed`, now fires for every failure after the attempt is counted, with a closed
vocabulary `reason` (api_4xx, api_5xx, invalid_response, network_error,
zip_error, user_declined, unexpected), the HTTP `status_code` when the API
answered, and the existing `source`. Never the error message.
The request path is factored into `_request_crew_creation`; every exception is
classified, reported and re-raised unchanged, so CLI and TUI behaviour is the
same as before. HTTP failures are classified before `_validate_response`, which
still prints and exits as it did.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(cli): classify deploy create failures by status and by stage
Review fixes on the failure span. Check the HTTP class before the body so a
gateway's HTML page counts as api_4xx / api_5xx with its code. Treat a 2xx
whose body is not a JSON object carrying uuid and status as invalid_response
and exit cleanly, instead of emitting a success span and crashing in the
display step. Recognise archive failures by a dedicated ArchiveError
(a ValueError) raised from create_project_zip, so the git helpers' own
ValueErrors no longer read as zip_error; a failed ZIP write is wrapped and
its partial file removed.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(cli): treat staging and temp-file failures as archive errors
`create_project_zip` only wrapped the ZIP write, so an `OSError` while
staging files or creating the temporary archive escaped as a bare
`OSError` and the deploy command recorded it as `unexpected` instead of
`zip_error`. The archive boundary now covers staging, temp-file creation
and the write; the staging directory is removed on every path, and no
partial archive is left behind.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* feat(cli): tell a non-JSON 2xx apart from a non-creation 2xx
A proxy's 200 HTML page and a JSON body missing the creation fields were
both recorded as `invalid_response`. They are different failures, one in
the network path and one in the API contract, so the deploy failure span
now records `invalid_json` for the first and `invalid_creation_response`
for the second. Requested in review.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
---------
Co-authored-by: Claude Fable 5.1 <noreply@anthropic.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* feat(tracing): collect human feedback and pause events in the trace
The trace listener subscribed to method and conversation events but not to
the review-gate events or the pause events, so a `@human_feedback` gate
reached the trace only as method_execution_started/finished. A trace could
not say that a run stopped for review, what the reviewer was shown, or what
they answered.
Subscribe to HumanFeedbackRequestedEvent, HumanFeedbackReceivedEvent,
MethodExecutionPausedEvent and FlowPausedEvent through `_handle_action_event`,
as the conversation events are, with the event's own type as the trace type.
Each is a whole-event payload via the default serialization path; no change
to `_build_event_data` or `complex_events`.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(tracing): register the gate and pause handlers through _on, keeping the execution-uuid gate
The four new handlers, and the conversation handler this branch had switched by
mistake, registered with event_bus.on and so ran while a kickoff owned an execution
uuid — the case where the OTEL session records these events and the legacy collector
must stay idle. Restored to self._on like every other handler; a test binds an
execution uuid and asserts none of the five are collected into a legacy batch.
Docstrings on the handlers (review bot coverage note).
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* test(tracing): under a tracing kickoff the session records the gate and pause events and the legacy batch stays empty
Two real flows under an in-memory tracing session (the lifecycle tests' pattern): a
@human_feedback gate answered at the console records human_feedback_requested and
human_feedback_received as spans; an async provider that parks the flow records
method_execution_paused and flow_paused. In both the legacy collector, gated by _on,
collects none of the four. Review bot: the uuid-gated test alone would have passed
with the session registrations missing.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
---------
Co-authored-by: Claude Fable 5.1 <noreply@anthropic.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* fix(memory): close sqlite connections in kickoff task outputs storage
`with sqlite3.connect(...) as conn` only commits or rolls back; it never
closes the connection, which then survives in a reference cycle until a
cyclic GC pass. Every Crew kept an open handle on
latest_kickoff_task_outputs.db, so on Windows the file stayed locked and
any later delete, rename or temp-dir cleanup failed with PermissionError
(WinError 32). Wrap each connection in contextlib.closing, keeping the
existing commit/rollback semantics, and add regression tests.
* test(memory): cover rollback and close on a failed write
---------
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
`_execute_single_native_tool_call` reads the tools handler's cache and
skips the tool body on a hit, but emitted its ToolUsageFinishedEvent
without `from_cache`, so the bus — and every trace built from it — saw a
replayed native function call as a live one. The text-protocol path
(ToolUsage.on_tool_use_finished) already carried the flag. One kwarg.
Co-authored-by: Claude Fable 5.1 <noreply@anthropic.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
A per-run caller sometimes needs specific agents on a different model
without editing the code that builds them. `crewai.llm_overlay` adds a
process-context `role -> model` overlay:
with llm_overlay({"Researcher": "openai/gpt-4o"}):
crew.kickoff()
The overlay is read in the only two places an agent resolves its model from
its role: `Agent.post_init_setup` and `LiteAgent.setup_llm`. When the role is
a key, `create_llm` receives the mapped model instead of the declared `llm`;
otherwise, and outside the block, nothing changes. `create_llm` itself stays
role-blind.
The overlay is a ContextVar, so it follows the calling context and is always
reset on exit. It does not cross plain threads; callers threading agents must
propagate the context with `contextvars.copy_context().run(...)`. The module
docstring says so and a test pins the behaviour.
Co-authored-by: Claude Fable 5.1 <noreply@anthropic.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* fix(files): return None instead of bare raise in get_uploader
get_uploader is documented to return None for an unsupported provider, and
every caller branches on `if uploader is None`. Two fallthrough paths ran a
bare `raise` with no active exception, so an unknown provider and a Bedrock
provider without a configured S3 bucket raised
"RuntimeError: No active exception to reraise" instead of returning None.
Return None in both paths and widen the return types to `... | None`. The
Bedrock "not configured" guard now treats a falsy bucket_name (None or "") as
unconfigured, not only an absent one. The except ImportError re-raises are
unaffected.
Fixes#7282
* fix(files): raise ValueError from get_uploader for unknown/unconfigured providers
Per review, raise a ValueError with a concrete reason instead of returning
None. Returning None let the resolver silently fall back to inline and hid the
misconfiguration from the user, so the docstring no longer promises None and
the return types drop `| None`. The Bedrock guard also treats a falsy
bucket_name (None or "") as unconfigured. The ImportError re-raises are
unchanged.
cleanup skips providers it cannot build an uploader for, so it routes
get_uploader through a local helper that treats the ValueError as
"unavailable" and continues the pass.
* refactor(files): surface get_uploader errors through the resolver
Follow-up to review. get_uploader now raises ValueError, so _get_uploader no
longer promises FileUploader | None: it returns the uploader and lets the error
propagate through resolve() to the caller instead of swallowing it and falling
back to inline. Drop the now-dead `if uploader is None` checks at the two
upload call sites.
Also make the unknown-provider ValueError list the supported providers, and add
a happy-path test that a configured provider returns its uploader.
* fix(files): surface uploader lookup errors in async batch resolution
aresolve_files gathers with return_exceptions=True, which was silently dropping
files when _get_uploader raised (a missing provider SDK, or an unknown or
unconfigured provider). A batch shares one provider, so such a lookup failure
applies to every file: re-raise ValueError and ImportError to surface it,
matching the sync resolve_files path. Genuine per-file upload errors are still
logged and skipped.
* fix(files): only re-raise uploader config errors in async batch resolution
The earlier fix re-raised any ValueError or ImportError from
asyncio.gather(return_exceptions=True), so one unrelated per-file error
(for example a stream that raises ValueError when read) aborted the whole
batch instead of the intended log-and-skip.
_get_uploader now translates the lookup failure into a dedicated
UploaderConfigurationError, and aresolve_files re-raises only that, since
it applies to every file for the provider. Ordinary per-file failures stay
best-effort. Adds regression tests for the wrap, a provider-setup error
surfacing from the batch, and an unrelated per-file error skipped while
the rest resolve.
* style(files): apply ruff import sort and formatting to resolver tests
---------
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
`agent_execution_started` and `agent_execution_completed` are in
`complex_events`, so `_build_event_data` hand-builds their payloads. Those
payloads shipped only agent_role/goal/backstory and dropped two required bus
fields: `AgentExecutionStartedEvent.task_prompt` and
`AgentExecutionCompletedEvent.output`. A trace therefore said which agent ran
but not what it was asked or what it answered.
Add `task_prompt` to the started payload and `output` to the completed one,
whole and untruncated. No new event types, no TraceEvent change.
Co-authored-by: Claude Fable 5.1 <noreply@anthropic.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* fix(flow): support non-primitive types in SQLiteFlowPersistence (#7358)
* test(flow): add docstrings to test classes and step methods
* fix(flow): serialize Decimal and Path as strings in SQLite persistence
* fix(flow): dump BaseModel with mode=python to allow fallback serialization on Any fields
* fix(flow): prioritize model_dump mode=json with fallback to mode=python
* ci: re-trigger test suite
---------
Co-authored-by: Rohit Kanithi <rohitkanithi@users.noreply.github.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* feat: scaffold project with assistant instruction files
- Updated project creation to include `CLAUDE.md` and `GEMINI.md` that import `AGENTS.md`, ensuring consistent guidance across coding assistants.
- Implemented utility functions to copy assistant instruction files during project setup.
- Enhanced documentation in `AGENTS.md` to emphasize the importance of keeping telemetry enabled for optimal performance.
- Added tests to verify the correct scaffolding of assistant instruction files and their contents.
* fix(cli): neutral observability guidance in scaffolded AGENTS.md
- State the observability rule as the user's decision, never a fix for
console warnings, speed, or a "clean" configuration
- Rewrite the AMP section as built-in capabilities: no "free",
"proactively", "sales pitch", or scripted pitches
- Turn the research mandate into a list of sources to consult when
version details matter
- Retarget the scaffold tests to the new wording
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(cli): scaffold assistant files for JSON crews and harden telemetry tests
- create_json_crew, the default `crewai create crew` path, now copies
AGENTS.md, CLAUDE.md and GEMINI.md; AGENTS.md documents the JSON layout
- span helper no longer depends on OTEL_SDK_DISABLED being popped by an
earlier test; thread-scope test stops its worker before leaving the mock
- single import style in the shutdown test
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
---------
Co-authored-by: Claude Fable 5.1 <noreply@anthropic.com>
JsonProvider writes checkpoints with encoding="utf-8" and the runtime
serialises non-ASCII text verbatim, but the checkpoint CLI still opened
them with the platform default encoding. On Windows (cp1252) `crewai
checkpoint info` raised UnicodeDecodeError and `list` showed a 0-byte
entry for any checkpoint containing non-ASCII text. Open the files as
UTF-8 and add regression tests for the three readers.
* fix(cli): overwrite stale poetry.lock backup on windows
os.rename raises FileExistsError on Windows when poetry-old.lock already
exists from a previous run, so a second `crewai update` crashed there
while POSIX silently replaced the file. Use os.replace, which overwrites
on every platform, and add a regression test.
* test(cli): add docstrings to update_crew tests
---------
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
`Memory.read_only` was enforced only on `remember()` and `remember_many()`.
Two other paths still mutated the backing store:
- `update()` re-embedded the supplied content and wrote the record back.
- `recall()` refreshed `last_accessed` through `touch_records()`, so simply
reading a read-only memory left a persistent trace.
Both now respect the flag, so a read-only Memory leaves stored records
unchanged. `update()` returns the existing record untouched rather than
raising, matching the silent no-op behaviour of `remember()`. Explicit
deletion through `forget()`/`reset()` is deliberately unaffected.
Claude-Session: https://claude.ai/code/session_01HkDjVYVzHFEj5re9B8JH9p
Co-authored-by: Claude Opus 5 <noreply@anthropic.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* fix(llms): send reasoning_effort to every openai reasoning model
The completions path gated the parameter behind
is_o1_model = "o1" in model.lower(), a literal substring test. gpt-5, o3 and
o4-mini contain no "o1", so an explicitly configured effort was dropped and the
model thought at the server default. The request still succeeded, so nothing
surfaced -- one measured extraction ran 6.2s with the setting applied against
149.7s with it dropped.
The gate could not be widened: is_o1_model also drives
supports_function_calling, supports_stop_words and the system->user message
rewrite, so marking gpt-5 as an o1 model would report that it cannot call
tools. The parameter is forwarded unconditionally instead, matching the
responses path, and a model that genuinely does not support it says so in a 400
that is retried once without the key.
Also adds "minimal" to LLM.reasoning_effort, which gpt-5 accepts and the
Literal omitted, so the cheapest setting was unreachable on the typed surface.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* refactor(llms): gate reasoning_effort on model shape, not every model
Forwarding to every model made a non-reasoning model pay a rejected request
and a retry on every call. `_supports_reasoning_effort` matches on shape
instead -- the o-series, and GPT generation 5 onwards -- so gpt-4o and gpt-4.1
never send the parameter at all.
Matched by shape rather than by a list of names so a new member of an existing
family works without a release here; gpt-6 and o5 already classify correctly.
The unsupported-parameter retry stays as a safety net for the case the shape
match is wrong for a future family, where it costs nothing when the match is
right.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(llms): honour reasoning_effort on compatible servers and fine-tunes
Review follow-ups. A fine-tune (ft:<base>:...) is judged by its base model.
On an OpenAI-compatible server -- anything whose effective base URL is not
api.openai.com, whether set explicitly, via env, or by a provider subclass --
the model name is the server's namespace and says nothing about support, so an
explicit setting is sent as configured; a 400 naming the parameter, in whatever
words the server uses, is recovered by retrying without it, unless it reads as
a complaint about the value. A model that rejected the parameter is remembered
per (endpoint, model) for the process so the rejected call is paid once, and
the drop is logged as a warning since a configured setting is not being
applied. The Literal also gains "xhigh", the remaining value the SDK accepts.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(llms): recover reasoning_effort only on evidence the parameter is unknown
Two review follow-ups. The endpoint check now uses the same base URL precedence
as the client itself, so a `client_params` override selects the server. And a
rejection is recovered only when the message says the field is not one the
server knows -- OpenAI's two shapes plus the common compatible-server wordings
("unknown field", "Extra inputs are not permitted") -- rather than any 400 that
lacks a value-sounding word. A pydantic enum complaint such as "Input should be
'low', 'medium' or 'high'" names the parameter but is about its value, and
surfaces instead of being dropped.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(llms): remember a reasoning_effort rejection only after the retry succeeds
Two review points on the reasoning_effort fallback. The rejection was recorded
before the retry ran, so a retry that died for an unrelated reason (a dropped
connection, say) silently stopped sending the configured effort for the rest of
the process even though a call without it had never succeeded; the (endpoint,
model) is now remembered only once the retry returns. And _effective_base_url
accepted only a str override in client_params while the SDK, and
_get_client_params, accept httpx.URL too, so a compatible deployment configured
with a URL object was detected as OpenAI and its rejection keyed under the wrong
endpoint; both forms are normalised to the string the client calls.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* fix(cli): reject non-serializable literal_eval results in TUI JSON formatting
_try_parse_structured() accepted any dict/list coming out of
ast.literal_eval(), including values json.dumps() cannot encode such as
[Ellipsis] from a literal [...]. _format_json_in_text() then raised
TypeError: Object of type ellipsis is not JSON serializable, which
propagated through _tick and cancelled the whole crew run.
Validate the parsed object with json.dumps() inside
_try_parse_structured() so only JSON-serializable dict/list values are
returned; anything else falls back to the original text. Fixes#7434.
* fix(cli): contain RecursionError in the TUI JSON formatting boundary
A streamed structure nested deeper than the JSON backend can walk could
raise RecursionError out of _try_parse_structured (from json.loads) or
out of the render-path dumps, escaping _tick and losing the TUI update.
Catch RecursionError when loading, and validate literal_eval results
with the exact kwargs the render path uses, so any structure the render
cannot encode is rejected at the boundary and the raw text renders
instead.
---------
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
mypy does not narrow on `platform.system()`, so Windows-based contributors
get 8 spurious attr-defined/unused-ignore errors from the termios and
resource imports. Switch to `sys.platform` comparisons, which mypy
understands natively, and drop the now-unneeded type-ignore comments.
Fixes#7400
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* fix(agents): request the forced final answer as a user turn
When an agent reaches max_iter, handle_max_iterations_exceeded appended
the "give your best final answer" instruction as an assistant message and
relied on assistant prefill to make the model continue it. Current Claude
models (Opus 5, Sonnet 5, Fable 5.x, the 4.6+ family) reject a request
that ends on an assistant turn with a 400, after the whole iteration
budget has already been spent.
The instruction is now appended as a user turn, which every provider
accepts. The handler's formatted_answer parameter is dropped: every
caller had already appended that text as the last assistant message, so
prefixing it again only duplicated history.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
* fix(agents): stop the lite agent loop after the forced final answer
LiteAgent._invoke_loop fell through after handle_max_iterations_exceeded
and issued a regular LLM call on the same history, discarding the forced
answer. Break out of the loop the way CrewAgentExecutor already does, and
assert a single LLM call in the test.
Co-Authored-By: Claude Fable 5.1 <noreply@anthropic.com>
---------
Co-authored-by: Claude Fable 5.1 <noreply@anthropic.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* fix(agents): keep null in the task output schema embedded in the prompt
build_task_prompt_with_schema embeds the task output schema into the prompt
via generate_model_description, whose strip_null_types defaults to True.
Combined with ensure_all_properties_required, an Optional[str] = None field
reaches the model as a required, non-nullable string, contradicting the
provider-side response schema generated from the same model.
That sanitizer targets OpenAI strict function-calling schemas. This call site
produces prompt prose, where those constraints do not apply.
Pass strip_null_types=False, matching the existing call for tool schemas in
utilities/agent_utils.py.
Fixes#6774
* test(agents): cover the output_json branch of the prompt schema
build_task_prompt_with_schema embeds a schema on both the output_json and
the output_pydantic branch, and this PR changes both. The regression test
only built a Task with output_pydantic, so the output_json branch shipped
unpinned.
Parameterize over both output attributes. Checked on this branch with the
fix reverted: both cases fail on the missing anyOf, and both pass with it.
Also compare the anyOf members as a set, so member order is not part of the
test contract.
---------
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* feat(embeddings): add openrouter provider type definitions
* feat(embeddings): implement OpenRouterProvider
* feat(embeddings): export openrouter provider package symbols
* feat(embeddings): register openrouter in allowed embedding providers
* feat(embeddings): register openrouter provider and overloads in factory
* feat(tools): add openrouter embedding service support
* test(embeddings): add comprehensive openrouter provider and factory tests
* test(embeddings): add openrouter build test in embedding factory
* test(embeddings): add openrouter model key alias and env tests
* test(tools): add openrouter tests for embedding service
* docs: add openrouter embedder configuration example
* docs(ar): sync openrouter embedder translation
* docs(ko): sync openrouter embedder translation
* docs(pt-BR): sync openrouter embedder translation
* feat(embeddings): allow model alias and None fields in OpenRouterProviderConfig
* fix(tools): resolve EMBEDDINGS_OPENROUTER_API_KEY before OPENROUTER_API_KEY
* test(tools): add regression tests for openrouter env var precedence and fallback
* feat(embeddings): drop organization_id and resolve api_key via OPENROUTER_API_KEY only
* fix(tools): use OPENROUTER_API_KEY in embedding service and update tests
* docs: switch openrouter knowledge example to model_name and document OPENROUTER_API_KEY
* fix(tools): default openrouter model to namespaced openai/text-embedding-3-small
---------
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* fix(openai): surface gateway errors reported inside an HTTP 200
OpenAI-compatible gateways commit `200 OK` as soon as the upstream provider
accepts a request, so a later provider failure arrives in the body as an
`error` object with no `choices`. That reached the SDK's parse helper and
surfaced as `TypeError: 'NoneType' object is not iterable`, naming neither the
provider, the status, nor the fact that a timeout happened.
The four non-streaming paths now inspect the raw body before parsing and raise
the exception the upstream code maps to, so a masked 504 is catchable exactly
like an honest one. Streaming already had this guard inside the SDK.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* test(openai): teach the tool-cache fake about with_raw_response
The provider now reads the raw body before parsing, so a client double that
only implements `create` no longer satisfies it. Same shape as the fixes to the
reasoning-effort retry and Snowflake doubles.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* test(tracing): reset the TraceCollectionListener singleton between tests
TraceCollectionListener caches a TraceBatchManager on the class and
`_initialized` short-circuits `__init__`, so batch state survives for the whole
xdist worker. `test_nested_agent_executor_flow_does_not_finalize_parent_batch`
left `trace_batch_id="debug-trace-batch"` behind, which moved every later trace
POST from /tracing/ephemeral/batches to /tracing/batches/<id>/events. The
recorded cassette then stopped matching, the agent retried, and the second call
found the cassette consumed -- surfacing as ConnectionError in an unrelated
test hundreds of tests later.
Reproduced deterministically by running the leaking test followed by
tests/tracing/test_trace_enable_disable.py::test_trace_calls_when_enabled_via_env;
fails on a68b5e903 too, so this predates the gateway fix it was blocking.
An autouse fixture now clears the cached instance after each test. Two canaries
pin the invariant and fail without the fixture.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* test(tracing): drop the unwritable _listeners_setup canary
Both review bots flagged that the canary read `_listeners_setup` off the class,
where it is always False, so it could never fail. Correct, and the suggested fix
does not work either: `BaseEventListener.__init__` calls `setup_listeners`
(base_event_listener.py:16), which sets the flag on the instance
(trace_listener.py:229), so reading it back through `TraceCollectionListener()`
is always True. Neither read observes a leak, so the canary is deleted rather
than replaced, with the reasoning recorded so it is not re-added.
The same finding showed the fixture was resetting two class attributes that are
never assigned at class level. Only dropping `_instance` is load-bearing, so the
fixture is now one line.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* docs(tracing): correct why the _listeners_setup canary is unwritable
setup_listeners returns early when tracing is off and no override applies
(trace_listener.py:213-220), assigning the flag at :229 only when it actually
registers. Construction therefore does not always set it, as the previous note
claimed: with tracing disabled the flag never even reaches the instance dict.
The instance read reports ambient tracing state rather than isolation, which is
a better reason not to assert on it than the one recorded before.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(tests): clear trace batch state in place instead of dropping the singleton
Dropping `TraceCollectionListener._instance` made the next construction re-run
`setup_listeners`, re-registering its handlers on the event bus. That broke
tests/telemetry/test_task_failure_instrumentation.py, which requires exactly one
handler per event: the re-registered `on_task_failed` made two. Verified against
a53ecc17f, where the same sequence passes -- the regression was mine.
The leak that needed fixing was batch state, not registration, so the fixture
now clears the manager's batch fields in place. Handler cleanup already belongs
to `cleanup_event_handlers`, and `first_time_handler` keeps its reference to the
same manager object.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(tests): clear tracing context vars so the listener can re-register
Bugbot flagged that keeping the singleton leaves `_listeners_setup` set, so after
`cleanup_event_handlers` wipes the bus `setup_listeners` returns early
(trace_listener.py:208) and tracing silently registers nothing for the rest of
the worker. Confirmed: after a tracing-enabled run, re-running setup restores 0
of 119 handler entries.
Dropping the singleton fixes that but previously broke
test_task_failure_instrumentation. The real cause was a third leak: the
`_tracing_enabled` context var stayed set, so the replacement listener still
believed tracing was on and re-registered `on_task_failed` next to telemetry's.
Clearing the context vars is what makes replacing the listener safe, so the
fixture now does both, and a canary pins it (fails with `assert True is False`
without the drop).
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
Push was choosing ZIP vs git from a local origin remote, so adding origin later rebuilt the last ZIP with no files. Prefer AMP zip_deployment from status, and fall back to the old origin heuristic when that field is missing.
`oxylabs` was pinned to exactly 2.0.0, so consumers could not take 3.0.0, out
since March. 3.x keeps the `RealtimeClient` surface these tools use, and all
four tools plus their failure paths were verified against the live API on both
2.0.0 and 3.0.0.
The lockfile keeps oxylabs at 2.0.0, so this permits the upgrade rather than
forcing it.
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(oxylabs): report scrape failures instead of raising IndexError
The oxylabs SDK logs HTTP errors and returns an empty response rather than
raising, so the unchecked `response.results[0]` in every Oxylabs tool turned a
rejected request into `IndexError: list index out of range`. Invalid credentials
-- the most likely first-run mistake -- gave no indication of the cause. A
result carrying a non-2xx `status_code` had the same problem one level down: the
job ran, the page did not come back, and the tool returned its empty content as
though the scrape had succeeded, handing the agent "[]".
Both are now reported as a `ToolFailure` naming what went wrong, so the agent
gets something it can act on and the framework records the call as failed:
401 Unauthorized
400 Bad Request - Parameter `parsing_instructions` can be used just with
`parse` parameter set to `true`.
Because the SDK keeps the cause only in its own log, the failing call is run
with a handler attached to the `oxylabs` logger and the status, the API's
explanation and timeouts are read back off it. `code` and `retryable` are set
from the status, so 429 and 5xx are marked worth retrying. Nothing about the
caller's logging configuration is changed; an application that has silenced the
SDK still gets the generic failure.
Content that is neither a string nor a dict is also serialized properly:
`parsing_instructions` commonly yields a list, and the previous `str()`
fallback produced a Python repr with single quotes instead of JSON.
The client construction and response handling these four tools duplicated
verbatim now live in a shared `OxylabsBaseTool`, following the existing
`SerpApiBaseTool` pattern, so the handling above exists in one place. The
generated tool specs change only by the new `locale` field, confirming the
tools' public surface is otherwise untouched.
Also add the `locale` option to the Google Search config, which the docs
already documented but the config model silently dropped, and correct two
copy-paste errors in the docs across all four locales.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(oxylabs): keep concurrent scrape diagnoses apart
The error capture attached a fresh handler to the shared `oxylabs` logger for
each scrape, so two scrapes in flight at once each saw both errors. `_diagnose`
reads the first HTTP status it finds, so a timeout could be reported as the
other request's 400 -- `retryable=False` on a failure that was worth retrying.
One handler now serves every scrape and routes each record to the capture of
the call that caused it via a `ContextVar`, which isolates threads and asyncio
tasks alike. Serializing the captures would have fixed the cross-talk too, but
at the cost of running every scrape one at a time. The handler stays attached
once installed: it is inert outside a capture, and detaching it would race with
concurrent scrapes.
The regression test forces the interleaving -- one capture is held open while
the other call logs -- and fails against the previous implementation.
Also drive `config` through the public constructor in the tests instead of
assigning `__dict__["config"]`, so they would catch `__init__` dropping a
supplied config.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
get_search_url interpolated ${query} inside an f-string, producing
URLs like https://www.bing.com/search?q=$test. The URL is passed
straight to the SERP request, so every search carried the malformed
query string.
Fixes#7325
The Args block for ConsoleFormatter.handle_llm_stream_chunk listed
'chunk' and 'crew_tree' parameters that no longer exist on the method.
The signature was refactored to (accumulated_text, call_type) but the
docstring was not updated. Callers in event_listener.py pass only the
two real params.
Refs #7312.
* docs(streaming): fix streaming output docstring examples
CrewStreamingOutput's example called crew.kickoff() without setting
stream=True on the Crew, so the snippet returned a CrewOutput and did
not stream anything.
FlowStreamingOutput's example called flow.kickoff_streaming() and
flow.kickoff_streaming_async(); neither method exists. Flow-level
streaming is exposed through Flow.kickoff with stream=True and
returns a StreamSession, not a FlowStreamingOutput.
Refs #7285
* docs(streaming): clarify Flow.kickoff does not take stream param
Flow.kickoff() has no stream parameter; the runtime returns a
StreamSession when self.stream is True. Reword the FlowStreamingOutput
note so callers know to configure the Flow with stream=True before
calling kickoff().
Addresses CodeRabbit review on #7286.
* docs(streaming): restore FlowStreamingOutput example
Add back an Example block showing valid usage of FlowStreamingOutput.
The class is only ever constructed directly with a chunk-producing
iterator (see lib/crewai/tests/test_streaming.py), so the example
mirrors that pattern instead of the original snippet that referenced
non-existent Flow.kickoff_streaming methods.
Addresses review feedback on #7286.
* docs(streaming): swap FlowStreamingOutput example for public Flow streaming path
Replace the test-only FlowStreamingOutput(sync_iterator=...) example
with the actual public flow-streaming path: Flow.stream=True followed
by kickoff() / kickoff_async(), which return StreamSession /
AsyncStreamSession. The example is labeled explicitly to make clear
that Flow.kickoff() does not return a FlowStreamingOutput, and points
readers at the streaming-flow-execution guide.
Addresses review feedback on #7286.
---------
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* fix(schema): support list-form "type" arrays in JSON schema conversion
_json_schema_to_pydantic_type already handles anyOf/oneOf for nullable
unions -- the form Pydantic's own schema generation produces for
Optional[T] fields -- but had no handling for the other, equally valid
JSON Schema way of expressing the same thing: a list-form type array,
e.g. {"type": ["string", "null"]}. This is what .NET/System.Text.Json
-based schema generators produce instead, so any MCP tool schema from
a non-Python server using this form crashed create_model_from_schema
outright with "Unsupported JSON schema type: ['string', 'null']" --
taking down the entire MCPServerAdapter connection, not just the one
affected tool.
Confirmed against a real self-hosted MCP server (Equibles,
github.com/daniel3303/Equibles): several of its tools (e.g.
ListCompanyDocuments's startDate/endDate filters) use exactly this
pattern, and MCPServerAdapter couldn't connect to it at all as a
result -- reproduced identically on both Windows and macOS.
Fix mirrors the existing anyOf/oneOf handling: treat each entry in a
list-form type the same way an anyOf member is handled, building a
Union of the corresponding Python types. A single-element list
collapses to that one type via typing.Union's own behavior, and
"null" entries resolve to None (matching how the type == "null"
branch already behaves), producing the same Optional[T] shape as the
anyOf case would.
Co-Authored-By: Claude Sonnet 5 <noreply@anthropic.com>
* fix(schema): preserve union members when applying FORMAT_TYPE_MAP
CodeRabbit flagged this reviewing #7058: the format override in
_json_schema_to_pydantic_field replaced the whole resolved type with
FORMAT_TYPE_MAP[format_], even when that type was a Union built from a
list-form `type` (or anyOf/oneOf) rather than a plain `str`. For a
schema like {"type": ["string", "null"], "format": "date-time"}, this
collapsed Union[str, None] down to plain datetime, silently dropping
the null option -- masked for non-required fields by the
Optional-rewrap at the end of the same function, but not for a
required-but-nullable field (a valid, if unusual, JSON Schema shape).
The same override also drops any non-string members of a multi-type
array (e.g. ["string", "integer", "null"]) regardless of required
status, since nothing rewraps those.
Narrow the override to the `str` member specifically: replace `type_`
outright when it's already plain `str`, or substitute only the `str`
element inside a Union via get_origin/get_args, leaving null and
other type-array members untouched.
Added two tests covering the previously-broken cases: a required
nullable formatted field, and a multi-type array (string/integer/null)
with a format.
Co-Authored-By: Claude Sonnet 5 <noreply@anthropic.com>
---------
Co-authored-by: Claude Sonnet 5 <noreply@anthropic.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
gpt-4o-mini's official context window is 128,000 tokens (OpenAI
announcement and API docs; litellm's model database agrees), but the
shared LLM_CONTEXT_WINDOW_SIZES table and the OpenAI/Azure provider-local
tables listed 200000 - apparently copied from the neighboring o3-mini /
o4-mini entries. With CONTEXT_WINDOW_USAGE_RATIO = 0.85, crews resolved
the usable window to 170000 instead of 108800, letting history grow past
the model's real 128k limit and failing with API 400s on long runs.
Fixes#7293
Organization names are not unique, so the documented `@org/name` form can
resolve to the wrong organization and fail to find the skill. Document the
`@org-uuid/name` form instead, and add a note pointing at `crewai org list`
for the UUID.
Applies to the agent-side registry refs too: they resolve through the same
`/skills/:org/:name` endpoint and the same `~/.crewai/skills/{org}/{name}/`
cache path, so leaving them as `@acme` would contradict the install command.
Co-authored-by: Claude Opus 5 <noreply@anthropic.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* fix(bedrock): preserve streaming tool call arguments at contentBlockStop
Streaming Converse handlers accumulate tool input as JSON string deltas in
accumulated_tool_input but never fold it back into current_tool_use["input"],
so function_args reads an empty {} at contentBlockStop. Parse the accumulated
input into the tool-use block (with a {} fallback) in both the sync and async
streaming handlers. This is the streaming counterpart of the non-streaming fix
in #5415 (issue #4972).
Co-Authored-By: Claude Opus 4.8 (1M context) <noreply@anthropic.com>
* fix(bedrock): coerce non-dict streaming tool input to empty dict
json.loads on the accumulated tool input can return a valid-but-non-object
JSON value (e.g. a string or list), which would fail at fn(**function_args)
with a TypeError. Enforce a dict shape before use in both the sync and async
streaming handlers, and add a regression test for the non-dict case.
Addresses CodeRabbit review feedback on #6150.
---------
Co-authored-by: Claude Opus 4.8 (1M context) <noreply@anthropic.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
LegacyClient filtered the server response with exact app and action
names. The platform returns canonical app names and provider action
names, so valid aliases produced no tools.
* fix(tools): read octet-stream URLs by sniffing the body
URLReadTool resolved content type from the Content-Type header and then
the URL path extension. Presigned object-store links carry neither: they
pin every object to application/octet-stream and use a content hash for a
path, so a SharePoint download landing in R2 was refused outright.
Sniff the already-fetched body as a third source, consulted only after the
header and both URL extensions come back with nothing. The sniff can turn
a refusal into a read but never a read into a different read, so no URL
that works today changes behavior.
Fails closed: a zip is DOCX only when word/document.xml is in its central
directory, so an .xlsx keeps its honest refusal instead of surfacing a
misleading "failed to read DOCX"; text requires a strict, whole-body UTF-8
decode with no NUL byte; an empty body identifies nothing.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(tools): extract text from XLSX URLs
The reported presigned SharePoint link is a spreadsheet, so sniffing the
body identified it as OOXML but still had nowhere to send it: URLReadTool
had no XLSX extractor, and the file would have been refused even with a
correct spreadsheetml Content-Type.
Read workbooks with openpyxl, already a core crewai dependency, so this
adds no new one. Sheets are emitted as CSV under a "Sheet <name>:" heading,
mirroring the PDF extractor's per-page shape. read_only streams the sheets
instead of building the whole object graph and data_only takes cached
values, both of which matter for a workbook arriving from an untrusted URL.
Cells are written through csv rather than joined, so a comma, quote or
newline inside a cell cannot corrupt the grid, and trailing phantom rows
are trimmed because Excel reports sheet dimensions generously.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(tools): bound xlsx expansion and refuse ambiguous ooxml packages
Bot review found two real defects in the XLSX extractor, both reproduced.
openpyxl pads every row up to a sheet's declared dimension, so a single
stray cell far down the sheet turned a 4.8 KB upload into 100,000 rows and
200,000 cells. Trimming only trailing blanks did not help, because the
stray cell sits at the end and keeps the last row non-empty. Blank rows are
now skipped as they stream, and a cell budget caps what any one workbook
can hand an agent -- announced in the output rather than silently applied.
A zip carrying both word/document.xml and xl/workbook.xml was classified as
DOCX. Two identities is not a positive identification, so it is refused.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(tools): keep whitespace-only xlsx cell values
Bot review, verified: openpyxl's row padding arrives as None, so testing
cells for exactly-empty drops it just as well as .strip() did while leaving
a row whose cells the author really did fill with spaces. And rstrip() on
the rendered grid removed a trailing space from the final cell along with
the line terminator; only the terminator should go.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(tools): bound xlsx scan work, not just emitted cells
The cell budget only counted cells that reached the output, and blank rows
skip before that point. A sheet can declare Excel's maximum dimension while
holding two real cells; openpyxl then pads every row out to 16,384 columns
and yields one row per gap. Measured: a 4,848-byte workbook drove 1.64
billion cell normalizations in 15.2 seconds with the budget never touched.
Charge a separate scan budget per row, before the row is normalized and
before the blank check, so the work a hostile sheet can demand is bounded
whether or not any of it is emitted. The regression test asserts the read
completes in under 5 seconds and is mutation-verified: dropping the per-row
charge takes it back to 26 seconds.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(deps): clear the six pip-audit advisories
gitpython 3.1.58 has PYSEC-2026-3785 through -3788, fixed in 3.1.59; the
lock now takes 3.1.61. Its exclude-newer-package cutoff is dropped rather
than bumped -- the global 3-day cutoff has long since passed 2026-08-05, so
that per-package pin was only holding the fix back.
snowflake-sqlalchemy 1.10.0 has GHSA-8g6f-qw9x-4q6q (SQL injection and
local file disclosure), fixed in 1.11.0.
unstructured 0.18.32 has GHSA-4mvj-m6j5-pmf7, a full-read SSRF via the url=
argument of partition(). The patched 0.24.0 requires Python >=3.11 while
crewai-tools supports 3.10, so the floor carries a marker and 3.10 stays on
the old line. 0.24+ also requires beautifulsoup4>=4.14.3, so the bs4 pin
widens from ~=4.13.4 to >=4.13.4,<5 -- a widening, so no existing install
breaks. uv resolves bs4 4.13.5 on 3.10 and 4.15.0 on 3.11+.
pip-audit locally: "No known vulnerabilities found, 5 ignored", with no new
--ignore-vuln entries. Only crewai-tools[xml] grows, gaining spacy and
openai-whisper transitively through unstructured's extras.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(tools): narrow bs4 find_all results without a cast
Widening the beautifulsoup4 pin let uv resolve 4.15.0 on Python 3.11+ while
3.10 stays on 4.13.5, because the old unstructured line holds it back there.
4.15 types find_all precisely, so cast(Tag, link) became redundant and mypy
failed the 3.11-3.13 type-checker jobs while 3.10 passed.
isinstance narrowing is correct under both versions and is what AGENTS.md
asks for anyway. Verified by running mypy against 4.15.0 and again against
4.13.5: browser_toolkit is clean under both, leaving only the pre-existing
errors in crewai/rag/embeddings/providers/ibm.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(deps): declare security floors in crewai-tools, not only as overrides
Bot review caught a regression I introduced. override-dependencies replace
the whole requirement including its marker, so gating the unstructured
override on python_version >= '3.11' dropped the dependency outright on
3.10: the lock held only 0.24.1, never the 0.18 line the comment claimed.
crewai-tools[xml] would have installed no unstructured at all there.
Move the floors into lib/crewai-tools/pyproject.toml, where a marker split
means what it says -- >=0.24.0 on 3.11+, >=0.17.2 below -- and drop the
root override for unstructured entirely. The lock now carries both 0.18.32
and 0.24.1 under complementary markers.
Same reasoning applies to the other two, per the nltk precedent already in
that file: a uv override only shapes this workspace's lock, so consumers
installing crewai-tools[snowflake] or [github] were still getting the
vulnerable floors. Declared there now as well.
Also documents the tool as a fit for presigned and share links from S3, R2,
Google Drive, OneDrive and SharePoint -- the case this PR fixes -- while
saying plainly that it reads a URL and does not authenticate.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* chore: update tool specifications
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
Co-authored-by: github-actions[bot] <41898282+github-actions[bot]@users.noreply.github.com>
* fix: append trailing user turn in native Gemini provider
GeminiCompletion._format_messages_for_gemini maps assistant messages
to Gemini's 'model' role but never guards against the resulting
contents list ending on a model turn. CrewAI's own agent loop (max
iterations, guardrail retries) can produce exactly that history, and
Gemini's generateContent API rejects it with 400 'Requests ending
with a model turn are not supported'.
Mirrors the existing Mistral/Ollama guard in
LLM._format_messages_for_provider, which never applies to Gemini
since gemini/google model strings resolve to this native provider
instead of the LiteLLM fallback path.
Fixes#6972
* fix: append trailing user turn for Gemini on the LiteLLM fallback path
LLM._format_messages_for_provider already guards Mistral/Ollama
against a trailing assistant turn, but Gemini models routed through
the LiteLLM fallback (no google-genai installed, or a model name not
recognized as native) had no equivalent guard. litellm's own
Vertex/Gemini transformation doesn't handle this either, so the
request reaches Gemini's generateContent API unguarded and 400s.
Complements the native-provider fix in GeminiCompletion, covering
both dispatch paths.
* fix: don't append text turn after unresolved Gemini function call
Address CodeRabbit review on #6973: appending a plain 'Please
continue.' user turn after a trailing model turn that contains an
unresolved function_call violates Gemini's function-calling protocol
-- it requires a matching functionResponse, not free text. Raise a
targeted error instead so the caller notices rather than silently
sending a malformed follow-up.
Also strengthens the native-provider formatting tests to assert exact
role sequence and text content (not just the last role), per review,
and adds a regression test for the unresolved-function-call case.
* fix: guard None parts when checking Gemini history for unresolved function call
contents[-1].parts is typed list[Part] | None; iterating it directly
failed mypy (union-attr) on 3.10-3.13. Narrow to [] before the any()
check and document the ValueError in the docstring.
---------
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* fix(llms): normalize scheme and port in Ollama base URL
OLLAMA_HOST follows Ollama's own convention and may be a bare host
("0.0.0.0") or a host:port pair ("127.0.0.1:11434") rather than a full
URL. _normalize_ollama_base_url only appended "/v1", so those values
produced invalid base URLs such as "0.0.0.0/v1", and every request
failed with the misleading error "Failed to connect to OpenAI API:
Connection error." - confusing, since no OpenAI model was requested.
Fill in the missing parts the way Ollama's own client does: prepend
http:// when no scheme is present, append the default port 11434 when
none is present and the scheme is http (https implies 443), then append
the /v1 suffix the OpenAI-compatible endpoint requires.
Six of nine realistic OLLAMA_HOST forms were affected, including
127.0.0.1:11434, which is Ollama's documented default.
Co-Authored-By: Claude Opus 5 <noreply@anthropic.com>
* fix(llms): strip only the parsed path when normalizing Ollama base URL
Stripping trailing slashes from the whole URL before parsing corrupted
inputs that carry a query or fragment. "http://ollama/?tenant=acme" kept
a "/" path and produced a doubled "//v1", and a query or fragment ending
in "/" silently lost that character.
Parse first, then rstrip only parts.path. Adds regression tests for a
root path alongside a query and for a query value ending in "/".
Reported by CodeRabbit on #7206.
Co-Authored-By: Claude Opus 5 <noreply@anthropic.com>
---------
Co-authored-by: Claude Opus 5 <noreply@anthropic.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* chore(ci): ignore unpatched nltk GHSA-8mgp-746c-j5xp
No patched PyPI release exists beyond 3.10.3. nltk is transitive via
crewai-tools[xml] -> unstructured; CrewAI does not call the vulnerable
model-artifact APIs.
Co-authored-by: Vidit Ostwal <Vidit-Ostwal@users.noreply.github.com>
* chore(ci): note dropping nltk GHSA ignore on the next bump
Leave an explicit TODO beside the ignore so GHSA-8mgp-746c-j5xp is
removed when nltk moves past the unpatched 3.10.3 floor.
---------
Co-authored-by: Cursor Agent <cursoragent@cursor.com>
Co-authored-by: Vidit Ostwal <Vidit-Ostwal@users.noreply.github.com>
* fix: bump pypdf to 6.16.2 for GHSA-jp53-mhqp-8xcg
pypdf 6.15.0 fails pip-audit on three moderate DoS advisories; 6.16.1+ patches them.
* chore: keep existing uv.lock environment markers
A full uv lock refresh rewrote unrelated dependency markers; restore them so the pypdf bump stays isolated.
* chore: drop unused pypdf exclude-newer-package in crewai-files
~=6.16.1 plus the global 3-day cutoff already admits 6.16.2.
* chore: drop pypdf from exclude-newer-package
6.16.2 is already older than the global 3-day cutoff; the version floor is enough.
* Add Clipper integrations client
Implement the internal Clipper discovery and execution contract with
deployment authentication and normalized results. Keep
CrewAIPlatformTools on LegacyClient until the new path is ready for
selection.
* Allow Clipper requests without deployment instances
Local and self-hosted CrewAI executions can have a valid integration
token without a deployment instance UUID. Send the deployment header
when it is available and allow Clipper to attribute other executions to
the organization.
* fixup! Allow Clipper requests without deployment instances
* fixup! Add Clipper integrations client
* fix(telemetry): accept 1/yes/on on disable flags
CREWAI_DISABLE_TELEMETRY=1 was ignored because the gate only matched true, so telemetry stayed on with no warning.
* fix(telemetry): warn once on unrecognized disable values
Stop repeating the same invalid-flag warning on every telemetry check, and drop the undocumented CREWAI_DISABLE_TRACKING alias from docs.
---------
Co-authored-by: Lorenze Jay <63378463+lorenzejay@users.noreply.github.com>
* fix(flow): resolve @human_feedback emit LLM from the project model
Omitting llm= no longer hardcodes OpenAI. Collapse and learn resolve through create_llm so MODEL / MODEL_NAME / OPENAI_MODEL_NAME win, then DEFAULT_LLM_MODEL.
* fix(flow): fail closed when human-feedback collapse cannot classify
Stop routing to emit[0] when the collapse LLM cannot be called or its response does not match an outcome. Empty skip still uses default_outcome.
* refactor(flow): extract human-feedback collapse matching helpers
Move match/require outcome helpers out of _collapse_to_outcome so the classify path stays flat.
* refactor(flow): catch only LLM call failures in collapse
Keep HumanFeedbackCollapseError from matching outside the call try so it is raised once and does not trigger a second prompt.
* fix(flow): treat non-object JSON as raw collapse text
Avoid AttributeError when the collapse LLM returns JSON that is not an object.
* feat(flows): add now() to the CEL expression environment
CEL expressions in flow definitions had no way to produce the current
date: the environment was built bare, so date-dependent flows failed at
runtime. Register a now() function that returns the current UTC time as
a CEL timestamp. The value is frozen once per kickoff so every
expression in a run sees the same instant, even across midnight.
Standard CEL covers formatting from there: string(now()),
now().getFullYear(), now() - duration('24h').
* chore(flows): drop redundant comment on _cel_now
* refactor(flows): derive CEL env and functions from one registry
A function now lives in one _CelFunctionSpec entry: its annotation for
compile and its implementation factory for evaluate, so the two cannot
drift. Run-scoped values move into _CelRunContext; adding one is a
field, not a new parameter through every helper signature.
* chore(flows): drop _CelRunContext docstring
* fix(flows): freeze a fresh cel now() on human-feedback resume
resume_async never passes through kickoff_async, so a flow restored
with from_pending() had no frozen instant and now() fell back to live
wall-clock per expression. Freeze a fresh instant at resume instead of
persisting the kickoff one: a flow can pause on feedback for days, and
expressions after resume must see today.
* Decouple platform tools from the integrations API
Define normalized selector and tool data so platform tool creation does
not depend on the legacy API response shape. This contract makes the
legacy client easier to replace later.
- Move action discovery and response normalization into LegacyClient.
- Pass ToolInfo from discovery through tool creation and execution.
- Replace the builder flow with direct factory orchestration.
- Preserve app, action, and connection data in immutable models.
- Build sanitized tool names from the full tool identity.
- Preserve legacy request, SSL, and failure behavior with contract tests.
* fixup! Decouple platform tools from the integrations API
* fixup! Decouple platform tools from the integrations API
* fixup! Decouple platform tools from the integrations API
* fixup! Decouple platform tools from the integrations API
* fix(llms): let current claude models use native structured outputs
NATIVE_STRUCTURED_OUTPUT_MODELS only listed 4.5-era prefixes, so Opus 5,
Sonnet 5, Fable 5 and Opus 4.8 fell through to the forced-tool-call
fallback. That path also overwrites params["tools"], so a call combining
tools with a response_model silently lost the caller's tools.
_infer_provider_from_model documented a pattern-matching fallback it never
performed, so a Claude release newer than the constants list resolved to
"openai". Bedrock ('.' in model) and Azure (every OpenAI prefix) are left
out of that fallback because they would capture gpt-* models.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(llms): route bedrock-namespaced anthropic ids to bedrock
"anthropic.claude-*" is Bedrock's namespace, not the Anthropic API, and it
satisfies the anthropic prefix pattern. Settle it before the pattern loop so
an unlisted Bedrock id picks BedrockCompletion. The region-prefixed form
("us.anthropic.claude-*") was resolving to openai, so this repairs that too.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(deps): raise snowflake-connector-python floor for CVE-2026-15925
GHSA-5cc2-282f-jjq2 (CRITICAL): the connector does not verify TLS hostnames,
so a network attacker can impersonate the Snowflake endpoint. Fixed in 4.7.1.
crewai-tools[snowflake] declares "snowflake-connector-python>=3.12.4", which
the lock had resolved to 4.6.0. Following the existing convention, the security
floor goes in [tool.uv] override-dependencies rather than the source
declaration, matching how cryptography is handled.
Relocking also refreshes numpy/humanfriendly/nvidia environment markers, which
re-resolution under the relative exclude-newer window produces regardless of
this change.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* Add injectable client for CrewAI platform tools
Define an integrations client contract for action discovery and
execution. Keep the existing platform API as the default client to
preserve current behavior.
Allow callers to provide a custom client through CrewaiPlatformTools.
* Fix platform action tool failure tests
* Remove redundant protocol placeholders
* ci: require an open issue for first-time contributor PRs
Gate anyone who is not a returning contributor, and allow the PR only when a closing keyword points at an open issue in this repo.
* ci: accept any open issue mention for first-timer PRs
Drop the closing-keyword regex so #123, owner/repo#N, or an issue URL is enough when that issue is open.
* ci: ignore foreign owner/repo#N in first-timer issue gate
Bare #123 no longer matches the suffix of other/repo#123, so an open local issue cannot keep that PR open.
* docs: update channels guide to current copilotkit channels api
* docs: translate channels and frontend overview guides to ar, ko, pt-BR
---------
Co-authored-by: Lorenze Jay <63378463+lorenzejay@users.noreply.github.com>
Stores application, action, and connection values in an internal
selector. Validates the selector with clearer error messages. Keeps
existing application syntax and legacy API requests unchanged.
* fix: let a hook deny reach the caller as a deny
A hook that raised `HookAborted` on `pre_model_call` never reached the code
making the call: the LLM layer caught it and returned `False`, which providers
translated into `ValueError("LLM call blocked by before_llm_call hook")`,
dropping the reason and the source and making a policy decision
indistinguishable from a provider outage. Every internal model call then
absorbed that error through the `except Exception` that keeps a provider hiccup
from failing a run, so memory analysis fell back to defaults and the converter
and reasoning handler retried the call that was just denied. The abort now
propagates out of the LLM layer while the boolean convention keeps its
documented `ValueError` via `LegacyHookBlocked`, and the fail-open handlers
around internal model calls re-raise it instead of degrading.
* fix: dispatch model call hooks on the paths that skipped them
A model call was only checked when the executor loop drove it: the
`from_agent is not None` short-circuit in `base_llm` silenced the hooks
for agent planning and step observation, no provider `acall` dispatched
them at all, and `InternalInstructor` bypassed `llm.call` entirely. This
replaces that short-circuit with an explicit
`model_call_hooks_already_dispatched` window so the enclosing caller
claims the dispatch, adds the pre-call dispatch to every provider's
`acall`, and runs the hooks around the Instructor client call. A denial
now emits a denied event instead of being logged and reported as a
provider failure.
* fix: report a boolean-convention deny as a deny, not an outage
A `before_llm_call` hook that blocks by returning `False` reached the five
native providers as a plain `ValueError`, which fell through to their generic
`except Exception` and was logged and emitted as `OpenAI API call failed: ...`
— the same deny raised as `HookAborted` was already labelled correctly, so the
two dialects disagreed on whether a policy decision was a provider outage. The
LLM layer now converts it into `LLMCallBlockedError`, still a `ValueError` so
the fail-open handlers around internal model calls keep absorbing it, but its
own type so a provider can report the decision it is. Since a block is raised
rather than returned, the thirteen callers that turned the return flag into a
raise by hand drop that line, and `_prepare_llm_call` raises the same type.
* fix: keep a denied plan from letting the agent run unplanned
`AgentExecutor.generate_plan` wraps `handle_agent_reasoning()` in a bare
`except Exception`, so guarding the reasoning handler alone still left the
deny absorbed one frame up: the executor logged "Error during planning" and
the agent proceeded with no plan. It now re-raises `HookAborted` like the
other planning boundaries, and the accompanying test also covers the
boolean convention still degrading at a fail-open site.
* fix: stop a denied knowledge query from running the task without knowledge
`handle_knowledge_retrieval` and its async twin wrap the query rewrite in
their own `except Exception`, so guarding `_get_knowledge_search_query`
alone still let `execute_task` continue on the unaugmented prompt after a
deny. Both now emit the terminal `KnowledgeSearchQueryFailedEvent` and
re-raise `HookAborted`, matching the second-frame guard already added to
`AgentExecutor.generate_plan`. Also documents the abort contract on
`PlannerObserver.observe`.
* fix: stop nine callers from re-swallowing a model call deny
CodeRabbit caught the replan path re-swallowing a deny, so an AST sweep of
every caller of a guarded function found the same defeat in nine places:
classic and replan planning, memory recall and memory save on both `Agent`
and `LiteAgent`, the base executor's save, and `LLMGuardrail.__call__`,
which turned a refused call into validation feedback. Each now re-raises
`HookAborted` after emitting whatever terminal event it owes, while every
other failure keeps degrading as before — the knowledge guards move to that
same idiom instead of duplicating their emit.
* fix: pair a denied guardrail with the event it started
Re-raising from `LLMGuardrail` left `process_guardrail` between its started
and completed events, so a denied validation read as one still in flight
rather than a policy decision. It now emits `LLMGuardrailCompletedEvent`
with the deny reason before the abort leaves, matching what every other
guarded site in this change already does.
* fix: stop retrying a task after a hook denied its model call
`Agent.execute_task` funnels every exception into `_handle_execution_error`,
which re-runs the whole task up to `max_retry_limit` times, so a policy deny
read as a transient blip: a crew whose first model call was denied retried and
returned a normal answer. `HookAborted` now joins `_passthrough_exceptions`,
the tuple already reserved for deliberate stops. The new boundary tests drive
the public entry points instead of the frame that makes the call, and count
model calls so a deny that gets retried fails the assertion — ten of the twelve
fail against `main`.
* fix: stop a denied plan step from being reported as a failed step
Making model call hooks reachable on agent-bearing calls put a deny inside
`StepExecutor.execute`, whose broad `except Exception` turned it into
`StepResult(success=False)` and let the plan carry on; `HookAborted` now
joins `ToolExecutionFailedError` in the passthrough handlers there, and
`execute_todos_parallel` re-raises a deny that `return_exceptions=True`
would otherwise record as one failed todo. `_emit_call_denied_event` also
renders the source through the now-public `source_name`, so a hook that
names itself with a callable reads as its name instead of a repr.
---------
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* feat(events): record how a crew run ended, for every user
Crew was the one level with no ungated terminal record. `Crew Execution` and
`end_crew` are both behind `share_crew`, which defaults False, so for
essentially every run there is no end-of-crew span at all - not one with fields
missing. Task outcomes ship ungated, flow outcomes ship ungated; crew being the
exception looks like an accident of history rather than a decision.
Adds `Crew Completed` carrying `outcome` and an explicit `duration_ms`, keyed by
crew_key/crew_id so it joins the existing ungated `Crew Created`. Modelled
directly on `flow_completed_span`, including its reasoning: a separate span
rather than holding `Crew Execution` open, because that span is emitted and
closed at start, so holding it would drop every run that is killed or crashes.
`on_crew_failed` called no telemetry at all before this, so a failed crew
produced nothing. It deliberately does not call `end_crew`, which writes onto
the gated execution span a failed run may never have opened.
Deliberately NOT included, each for a reason:
- Tokens. `crew.token_usage` sums per-agent LLM counters, and two agents sharing
one LLM object share one counter, so the total double-counts today. Putting it
on a span would propagate a known-wrong number into a metric. The dedup keys on
`id(llm._token_usage)`, not `id(llm)` - `Agent.copy()` shallow-copies the LLM -
and it changes the value of public `Crew.calculate_usage_metrics`, so it earns
its own change.
- Models. Already on the ungated `Crew Created` span at 99.86% coverage; this
joins to them by crew_id rather than duplicating.
- Tool counts. The ungated `Tool Usage` span covers only the ReAct path, the
plan/step path double-emits, and nested crews share one RuntimeState - the
count needs a design decision on cache hits before it is worth emitting.
- error_type. Needs 4.1's exception-class field factored out of task_events so
both events share it, rather than duplicated hours after that merged.
Tests use the exporter pattern this suite already uses rather than mocking
`EventListener._telemetry`: EventListener is a singleton, so swapping that leaks
a MagicMock into every later test. The listener tests assert on the stamp
lifecycle instead. Verified order-independent over five randomized runs.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* test(telemetry): docstring the crew-completed helpers
Eight of the thirteen functions in this file carried a docstring and five
did not, which is an inconsistency inside the file this PR adds rather
than anything inherited. Documents the two fixtures, the span lookup, the
event-bus runner and the two test methods that were missing one.
No behaviour change: 9 passed, and re-run under random ordering on two
seeds to confirm order-independence.
Deliberately not addressed: the reviewer's 52.17% docstring-coverage
figure is dominated by event_listener.py, where 84 functions - nearly
every pre-existing on_* handler - carry no docstring. That is the file's
convention, and documenting them here would be an unrelated refactor.
The public API this PR adds, Telemetry.crew_completed_span, is documented.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(events): report machine size as a coarse band, not a core count
`runtime_context` says where a process runs but carries no capacity axis, and
its largest bucket is a catch-all: a gunicorn worker on a VM and
`python main.py > out.log` on a MacBook both report `non_interactive`. Docker
Desktop on a laptop reports `container` via /.dockerenv, and a Remote-SSH shell
on a server reports `vscode_terminal`. So "server or laptop" is not answerable
from it today.
Adds `cpu_band` to the common span attributes, so it rides every span the way
`runtime_context` does rather than sitting on `Crew Created` alone - which would
answer nothing for Flow-only, CLI-only or standalone-agent runs.
Six bands, powers of two, top one open-ended: 1-2, 3-4, 5-8, 9-16, 17-32, 33+.
Open-ended because the exact count is the fingerprint - the observed fleet
maximum is 512, and a span reporting 512 identifies one machine. The vocabulary
is closed and asserted, like KNOWN_CODING_AGENTS and KNOWN_RUNTIME_CONTEXTS.
The share_crew-gated exact `cpus` attribute and the four platform* attributes
are untouched. That gating was a deliberate 2024 classification of machine
fingerprint as shareable content (44e38b1d5), and this does not reverse it: a
band is a range, the gated attribute remains the precise value.
Documents a trap in the docstring rather than leaving it to be rediscovered:
os.cpu_count() reports HOST cores, not the cgroup quota, so a 1-vCPU pod on a
96-core node lands in 33+. Right for "what kind of machine", wrong for "what did
this run get" - os.process_cpu_count() gives the latter but needs 3.13, above
this package's floor.
Docs updated in en/ar/ko/pt-BR, in the default-on Execution Environment row,
stating explicitly that the band is a range and the exact count stays opt-in.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* docs(telemetry): say where the cpu band comes from
The Execution Environment row ended "Detection reads only whether known
environment variables are set, never their values". True for the assistant
and runtime-context fields, and wrong for the band this PR adds:
detect_cpu_band() reads os.cpu_count() (runtime_env.py:306) and touches no
environment variable. In a privacy disclosure table that is the kind of
inaccuracy worth a line.
Names the source explicitly and scopes the env-var sentence to the two
fields it actually describes. All four locales at parity.
pt-BR also takes the reviewer's wording fix: "um de uma lista fixa" ->
"um valor de uma lista fixa", and the missing comma before o `project_id`.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
Move the canonical API into crewai.flow while preserving experimental imports and declarative references through compatibility aliases.
Co-authored-by: Cursor <cursoragent@cursor.com>
* fix(agents): preserve tool results when final answer is empty
Updated the StepExecutor to ensure that if the final answer from a tool call is empty, the last valid tool result is returned instead. This change enhances the reliability of the output in scenarios where the final answer may not provide useful information. Added tests to verify that both text and native steps correctly preserve tool results under these conditions.
* raise on empty string path
`Create Crew Deployment` fires before the API call that creates the
deployment, so it counts creation ATTEMPTS and cannot carry the uuid - the
call that creates the deployment is the call that returns it. Live effect:
`create_deployment` reads 76,015 events with 0 carrying a uuid (0.000%), so
deployments cannot be joined to anything.
Moving the existing span after the response would fix the uuid and silently
redefine the metric, turning attempts into successes; the deployment churn
figures are built on attempts. So this adds a second span rather than moving
the first.
`Crew Deployment Created` fires after `_validate_response`, which raises
SystemExit on failure - a failed create therefore still counts as an attempt
and reports no creation. Both creation paths, git remote and zip upload,
converge on that line and both return the uuid.
Emits no `deploy:created` feature count: the attempt span already does, and a
second emit would double the deployment count that origin-independent
aggregation depends on.
Tests cover the emitter (uuid carried, distinct span name, no second feature
count, absent-vs-empty uuid) and the call site across both creation paths plus
the failure path.
The warehouse consumer must be widened BEFORE this merges or it delivers
nothing: `mv_span_fanout_forward` filters on a hard-coded 13-name allowlist,
and `mv_fanout_deployment_spans`'s `multiIf` ends in a catch-all `remove_crew`
arm that would mislabel the new span. Runbook prepared separately.
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(llms): map default Claude Sonnet 4.6 to its 1M context window
Native AnthropicCompletion fell back to 200k for claude-sonnet-4-6, so the default instance understated the documented limit.
* fix(llms): align Anthropic context windows with active Claude models
Retired Claude 3/2/Instant IDs no longer have dedicated entries; the map now covers the current Claude API lineup and their documented 1M vs 200k windows.
* fix(llms): map Claude Mythos 5 to its documented 1M context window
Native AnthropicCompletion fell back to 200k for claude-mythos-5 even though Anthropic lists a 1M-token window.
* fix(llms): raise Anthropic default max_tokens so large tool calls survive
* fix(llms): default Anthropic to sonnet-4-6 and drop retired models
---------
Co-authored-by: Lorenze Jay <63378463+lorenzejay@users.noreply.github.com>
* fix(flows): persist custom conversational replies after fallback append
Custom @listen routes that only return a public string were appended after kickoff, so @persist snapshots missed the assistant turn. Snapshot again from the same persist path once the fallback writes state.messages.
* test(flows): cover @persist restore of custom conversational replies
Add regression coverage for custom @listen returns across fresh Flow instances, no double-append on built-in converse, and a single user/assistant message-added event.
* docs: note that public listen returns persist as assistant replies
* fix(agents): render message content parts as text, not a Python repr
A message whose `content` is a multimodal parts list collapsed to
`str(content)` wherever a message had to become a string, so the model
saw `[{'type': 'text', 'text': 'hello'}]` in Current Task, and memory
stored and searched that same repr.
Four sites flattened it that way: the turn promoted into the executor
prompt, the memory recall query, what `_save_kickoff_to_memory` writes,
and `_message_content_text` (token estimation and oversized-message
splitting).
The extraction already existed, inline in `_format_messages_for_summary`
-- text blocks joined, or `[multimodal content]` when a list carries
none. This lifts it to `_content_parts_text` and routes all five callers
through it, so summary, prompt, memory and token counting agree.
`_message_content_text` becomes `message_content_text`: it now has a
caller outside its module, and `agent/core.py` imports only public names
from `agent_utils`. It is not re-exported from any `__init__`, so no
public import path changes.
`test_list_content_uses_str` pinned the repr, so it is intentionally
rewritten to pin the text. Every other existing caller is unchanged:
30 failures on main, 30 on this branch, identical names.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VwxiogL9mQg9q8cx4qLfYJ
* fix(agents): skip a content part whose text is not a string
`_content_parts_text` joined `block["text"]` straight into a string, and
content blocks are `dict[str, Any]` arriving from a model, so a `text`
key holding an int, dict or None raised `TypeError`. That was contained
to summarization before; routing the prompt, memory and token-estimation
paths through the same helper widened it to `Agent.kickoff`, where the
old `str()` had merely produced an ugly string.
Such a block carries no usable text, so it is skipped. A list left with
nothing usable still falls back to `[multimodal content]`.
Writes the convention down in AGENTS.md rather than leaving it in a
review thread: never `str()` a message's content, use
`message_content_text`. Four sites had independently reached for
`str()`, which is what this whole change is undoing.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VwxiogL9mQg9q8cx4qLfYJ
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(mcp): add shared error classifier for HTTP auth failures
When an MCP server refuses a streamable-HTTP connection, the HTTP status is
observed by the client but often buried inside anyio teardown. Add typed
connection exceptions and helpers to recover the status from exception groups,
CancelledError context chains, and httpx errors so later call sites can report
authentication failures instead of guessing.
Groundwork only; no call sites wired yet.
* feat(mcp): raise typed errors from HTTPTransport.connect on HTTP status
When streamable-HTTP connect fails with an httpx HTTPStatusError, classify
the status via the shared MCP exception helpers and raise MCPAuthenticationError
for 401/403 or MCPHTTPError for other refused statuses instead of a generic
ConnectionError that hides the credential problem.
* refactor(mcp): centralize raise_connection_failure and simplify connect
Move connection failure classification into exceptions.py so transports and
clients share one helper. Flatten HTTPTransport.connect to a single except
path that cleans up once and raises, avoiding the outer handler re-classifying
errors the inner handler already typed.
* fix(mcp): classify auth failures in MCPClient.connect before reporting cancelled
When a streamable-HTTP server refuses the connection, the awaiting coroutine
often sees only CancelledError while the HTTP status surfaces during transport
unwind. Inspect cleanup for the status before emitting error_type=cancelled,
and fix HTTPTransport.disconnect so it raises typed errors instead of
suppressing exception groups that carry the refusal.
* fix(mcp): replace speculative tool resolver errors with classifier
Use raise_connection_failure for native MCP discovery instead of hedged
cancel-scope wording, preserve typed MCPConnectionError from setup, and
detect event-loop presence explicitly so ConnectionError is not mistaken
for a missing running loop. Update HTTPS discovery to classify HTTP status
codes via find_http_status.
* refactor(mcp): collapse native tool resolver failure handlers
CancelledError is not an Exception subclass, so handle it alongside
Exception in one except clause and delegate to a shared helper.
* refactor(mcp): call raise_connection_failure directly in tool resolver
* fix(mcp): classify tool execution auth failures in events
Add tool_execution_error_type so call_tool_result emits authentication
instead of server_error for MCPAuthenticationError and HTTP 401/403.
Preserve typed MCPConnectionError in _retry_operation instead of flattening
them into a generic ConnectionError first.
* feat(mcp): add status_code to MCPConnectionFailedEvent
Surface the HTTP status observed during connection failures on the event
payload and in verbose console output, so executions and checkpoints record
401/403 alongside error_type=authentication instead of only the message text.
* fix(mcp): handle cancellation and exception groups in auth paths
Ensure discovery cleanup runs on CancelledError, classify mixed
BaseExceptionGroups during HTTP connect, and fix ExceptionGroup imports
on Python 3.10 with regression tests.
* fix(mcp): preserve auth errors from discovery disconnect cleanup
Re-raise MCPConnectionError from disconnect during cancellation cleanup
instead of logging and swallowing it, with a regression test.
* fix(mcp): unwind transport context to recover auth on cancel
Always exit pending streamable-HTTP contexts before classifying failures,
handle CancelledError during client cleanup, propagate typed HTTPS discovery
errors, and add regression tests for the teardown recovery path.
* fix(mcp): classify auth from groups and timeout teardown
Handle BaseExceptionGroup in HTTPS discovery and recover HTTP 401 from
streamable-HTTP context exit after connect timeouts, with regression tests.
* refactor(mcp): consolidate client connection failure reporting
Extract _report_connection_failure and delegate _http_failure and
_connection_failure to it without changing connect error behavior.
* refactor(mcp): drop redundant client failure helper wrappers
Call _report_connection_failure directly from connect() instead of
_http_failure and _connection_failure delegators.
* fix(mcp): propagate CancelledError after HTTP transport teardown
Re-raise cancellation from disconnect when no HTTP auth status is
recovered during context unwind, with a regression test.
* fix(mcp): preserve typed errors from MCPClient.disconnect
Re-raise MCPConnectionError and CancelledError from exit-stack teardown
instead of wrapping auth failures in RuntimeError, with a regression test.
* fix: skip interception hooks on crewai-internal flows
The `AgentExecutor` and the memory encoding/recall flows are `Flow`
subclasses CrewAI runs for its own bookkeeping, and they were dispatching
interception points as if their methods were the caller's steps — a hook
saw machinery no user wrote, and a policy could deny a run over it.
`Flow._skip_interception` now suppresses every point on a flow marked
`is_crewai_internal`, except the execution boundary on machinery that is
itself the run the caller asked for. A standalone `Agent.kickoff()` keeps
its boundary and stays blockable, while the same executor bound to a crew
or nested in a caller's flow stays silent, so boundaries only ever fire
at the root.
* docs: note that the resume match id feeds the boundary check
`from_pending` seeds `_flow_match_id` from `instance.flow_id` for the usage
listener's filter, and `resume_async` forces `current_flow_id` to it for the
duration of the resume. `AgentExecutor._owns_execution_boundary` compares the
two, so seeding the original persisted id instead would make a resumed
standalone agent disown a boundary its kickoff already opened.
* fix(telemetry): record task failures as failures, not as successes
close_span() sets StatusCode.OK unconditionally, and TaskFailedEvent was routed
to Telemetry.task_ended, which calls it. Every failed task was therefore
exported as OK, which is why error_count downstream is not merely low but
exactly zero: 240.0M task executions across 13 months in
crew_task_executions_daily_target, error_count = 0 in every one of them.
The same line had a second defect. The span was only ended when
source.agent.crew was present, so a task failing without one was popped from the
span map and then never closed - never ended, never exported, invisible rather
than mislabelled. task_failed takes no crew (it reads nothing off one), so that
condition disappears rather than being widened.
Only the exception class name is recorded, never the message, which routinely
contains prompts, model output, file paths and credentials.
close_span_with_error drops any value failing str.isidentifier(), so a message
cannot be recorded even if one is passed by mistake.
This is the task half of closed PR #6781, re-cut onto main as that PR asked for.
The crew half is deliberately left out: crew_execution_span() returns None unless
share_crew=True, so crew._execution_span is None for nearly every user and a
crew-failure handler would exit immediately for the default population.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
* fix(telemetry): take the exception class for error_type, not a free-form string
cursor and CodeRabbit both flagged the sanitization, and they were right: the
package already had a stronger convention and this change had not used it.
Telemetry._safe_error_type takes the exception *class*, and its docstring says
why in as many words - "a single-word message such as 'secret_token' is itself a
valid identifier", so filtering a string with isidentifier() is not enough. The
ported code predates that helper and reinvented the weaker check.
TaskFailedEvent.error_type is now type[BaseException] | None, so pydantic itself
rejects a message before any of our code runs, and task_failed routes it through
_safe_error_type. The identifier check in close_span_with_error stays as the
second gate on the derived name, which is the role _safe_error_type's docstring
already describes.
Also adds producer-level tests, which CodeRabbit correctly identified as missing:
every earlier test constructed TaskFailedEvent directly, so a regression in the
two emit sites this change touches in task.py would have passed the whole suite.
The sync and async producers are driven through Task._execute_core and
Task._aexecute_core with a distinctive exception class, and each patches a
different agent method (execute_task vs aexecute_task), which is why they can
regress independently. Verified by dropping error_type from both producers: all
three new tests fail, and pass again when restored.
Removes an unused `import os` left behind when the fixture was rewritten.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
* test(telemetry): capture producer failures at the emit boundary, not via the bus
The producer tests subscribed a handler to crewai_event_bus and asserted on what
it received. That passed this file in isolation and every randomized local run,
then failed in CI inside a 621-test shard with zero events captured:
FAILED tests/telemetry/test_task_failure_instrumentation.py::
test_sync_producer_puts_the_exception_class_on_the_event
assert 0 == 1 + where 0 = len([])
task_failed is an "ending" event, and with an empty scope stack - there is no
real kickoff in these tests - dispatch is conditional on event-context state that
other tests in the same worker process can leave behind. Subscribing made the
assertion depend on the bus choosing to dispatch, which is not what these tests
are about: they are about what the producer in task.py constructs.
Patching crewai_event_bus.emit records the event unconditionally at the point the
producer hands it over, with no dispatch involved. Both producers ignore emit's
return value, so returning None is faithful.
Containment re-verified after the change: dropping error_type from both producers
fails exactly these three tests and nothing else.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
* fix(events): keep TaskFailedEvent JSON-serializable with a class-valued error_type
error_type holds an exception class, which is not a JSON type, so
model_dump(mode="json") raised PydanticSerializationError for the whole event -
not just that field. Two real consumers depend on it: the checkpoint listener
dumps every event through EventRecord, and the tracing listener JSON-POSTs events
to AMP. A single task failure therefore took out checkpointing.
field_serializer with when_used="json" returns the class name. The "json" scope is
load-bearing: event_listener hands the live class to Telemetry.task_failed, which
needs it for _safe_error_type, so python-mode dumps must keep the class.
The annotation is a module-level _ExceptionClass alias rather than an inline
type[BaseException], because TaskFailedEvent declares a field named `type` which
shadows the builtin for the rest of the class body - inline, it raises TypeError
at import ("task_failed"[BaseException]) and mypy rejects it as "Variable ... is
not valid as a type". Quoting satisfies neither tool: ruff flags UP037 and mypy
still resolves it in the class scope.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
* fix(events): let a dumped error_type restore, instead of degrading the event
The serializer added in the previous commit stopped model_dump(mode="json") from
raising, but nothing accepted the class-name string back. _resolve_event
(state/event_record.py:32-35) wraps cls.model_validate in a bare except and falls
back to BaseEvent, so restoring a checkpoint after a task failure silently
dropped the whole event -- including `error`, a plain string that would otherwise
have survived. Traded a loud failure for a quiet one.
Measured before: dumped error_type='ValueError' and error='boom', restored as
BaseEvent with neither attribute. After: restores as TaskFailedEvent with
error='boom' and error_type is ValueError.
A BeforeValidator resolves a name against real exception classes only -- builtins
first, then a walk of BaseException.__subclasses__(). So this does not reopen the
hole the class-typed field closes: "secret_token" resolves to nothing, is returned
unchanged, and is rejected by the field's own type. Asserted for secret_token,
sk_live_1234, dict and os.
A name whose class is not imported in this process still degrades, which is
deliberate: synthesising a class from an arbitrary string is the injection risk
this field exists to avoid.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* feat(flows): enhance conversational flow documentation and APIs
- Updated the description to clarify the use of `handle_turn` and structured streaming in multi-turn chat applications.
- Added a warning about the experimental nature of the conversational features.
- Improved the overview section to include structured streaming and refined the explanation of session handling.
- Enhanced the API documentation for `handle_turn`, `stream_turn`, and `chat` methods, emphasizing their roles in conversational flows.
- Clarified the turn lifecycle and the handling of user messages within the flow.
- Updated examples to reflect changes in message handling and session tracing.
- Ensured consistency across language versions in the documentation.
* feat(flow): deprecate answer_from_history route
Guide conversational flows toward the existing converse route while preserving compatibility warnings and schema metadata.
Co-authored-by: Cursor <cursoragent@cursor.com>
* stacklevel=3 raising it higher
---------
Co-authored-by: Cursor <cursoragent@cursor.com>
* fix(agents): keep message roles when Agent.kickoff gets a conversation
`Agent.kickoff` accepts `str | list[LLMMessage]`, but `_prepare_kickoff` joined
every message's content into one string. Measured with a recording LLM, a
three-turn conversation reached the provider as two messages:
system | You are Support...
user | Current Task: my order id is 42\nthanks, checking\nwhere is it?
So the agent's own previous reply was presented as something the user said, and
the model could not tell who said what. `LiteAgent.kickoff` already did this
correctly, which is why the same list gave four messages with roles intact
there.
The last message is now this turn's request and the ones before it travel as
`inputs["history"]` -- the way `inputs["files"]` already does -- which both
executors splice in after the system prompt and before the user prompt. Memory
recall still runs over the whole conversation text, not just the last turn.
A plain string and a single-message list are byte-identical to before, which is
what every existing caller passes.
Also widens `LiteAgentExecutionStartedEvent.messages` from `list[dict[str, str]]`
to `list[LLMMessage]`: it raised a ValidationError for a message whose content
was `None` or a content-part list, both of which are valid `LLMMessage` shapes
that `Agent.kickoff` already accepts.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(agents): carry history without a system prompt, tool calls, or dup files
Three review findings on the message-role work, all real.
History was spliced only in the branch that builds a system prompt. With
`use_system_prompt=False` or a custom template there is one combined prompt, so
history went nowhere and only the last turn reached the model -- worse than the
flattening this PR replaced, which at least included the text. Both executors
now splice in either branch, via one `_append_history` helper each.
Filtering on truthy content dropped an assistant turn that only requests tool
calls, leaving a `tool` message with no preceding `tool_calls` message -- a
sequence providers reject. A message now counts when it has content, tool
calls, or a tool_call_id.
And `files` were unioned from every message onto the current request while
history messages kept their own, so prior attachments were sent twice. Only the
current request's attachments travel in `inputs["files"]` now.
Found by Cursor and CodeRabbit on #7065.
* fix(agents): treat an attachment as message payload
_carries_payload counted text, tool calls and tool results, but not files.
A final message whose only payload was an attachment was filtered out, so the
previous message became this turn request and the attachment never reached
inputs["files"].
Found independently by Cursor and CodeRabbit on #7065.
* fix(agents): promote the last user message, not the last message
build_agent_context() appends an agent private thread after the current user
turn, so on a later turn the trailing message is an assistant scratch. That
scratch became Current Task while the real question was demoted to history --
reproduced: the request came back as "internal note: checked warehouse".
The request is now the last user message, with everything else kept as history
in order; with no user message the last one stands in, which is what a
single-message caller has always got. Documented on kickoff and kickoff_async.
The old cross-check against LiteAgent only compared roles on a fixture already
ending in a user message, so it could not catch this. It now asserts what holds
for both -- nothing dropped, nothing duplicated -- since Agent has a task slot
in its prompt and LiteAgent does not.
Reported by Vidit-Ostwal on #7065.
* test(agents): cover history placement on the deprecated executor too
`CrewAgentExecutor` carries its own `_setup_messages`, and `Agent.kickoff`
builds an `AgentExecutor` unconditionally, so nothing reached the twin's
two `_append_history` sites. This drives that executor directly with the
real `SystemPromptResult` / `StandardPromptResult` shapes, so both its
branches are pinned.
Verified by mutation: removing either `_append_history` call in either
executor now fails the matching test.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VwxiogL9mQg9q8cx4qLfYJ
* fix(agents): keep turns that follow the request after it
`_prepare_kickoff` packed every non-request message into one `history`
list, and both executors spliced that list before the current user
prompt. A conversation ending on a tool result therefore reached the
provider as `assistant tool_calls -> tool -> user`, hoisting the tool
pair above the question it answers. `LiteAgent` sends the same list as
`user -> assistant -> tool`.
Splits the carried messages at the request instead: what came before
stays `history`, what came after travels as `trailing` and is appended
after the user prompt. Promoting the last user message to `{input}` is
unchanged.
`test_a_tool_call_sequence_survives` missed this because it ends on a
follow-up user line, so the tool pair was already before the request.
Reported by lorenzejay, who also confirmed gpt-4o-mini and gpt-5.6-sol
accept the reordered payload -- an order bug, not a provider 400.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VwxiogL9mQg9q8cx4qLfYJ
* test(agents): assert the ordering through kickoff_async too
`kickoff_async` shares `_prepare_kickoff`, and the async executor entry
points reach the same `_setup_messages`, but sharing a code path is not
the same as covering it. Pins the tool-result ordering through the async
path, and lifts the tool conversation to a module-level fixture so the
sync and async assertions cannot drift.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VwxiogL9mQg9q8cx4qLfYJ
* docs(agents): state where a kickoff conversation's turns land
`concepts/agents.mdx` documents the multi-message form but not which
message becomes the request or what happens to the turns around it --
the contract this branch changed. Corrects the `kickoff` /
`kickoff_async` docstrings to match.
en and ko only: the ar and pt-BR pages do not carry the "Multiple
Messages" section at all, which is a pre-existing translation gap rather
than one this change introduces.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VwxiogL9mQg9q8cx4qLfYJ
* feat(flow): let a declarative agent action receive the conversation (#7066)
* feat(flow): let a declarative agent action receive the conversation
A chat handler could only hand its agent a single string, so a declarative
conversational flow's `agent` action never saw prior turns. Both ends blocked
it: `AgentDefinition.input` was `str` with a validator rejecting anything else,
and `AgentAction.run` raised "agent input must render to a string" once a CEL
template rendered to a list.
`input` now takes a string or a list of messages, and the action normalizes
rather than rejecting. A whole-string `${...}` template keeps its evaluated
type, so `state.messages.map(m, {'role': m.role, 'content': m.content})`
renders the exact shape the agent wants -- no new CEL function needed.
Serialized messages carry `name: None` and `metadata` that the agent event
schema rejects, and `message_to_llm_dict` only drops `None` for a model input,
not the plain dicts a CEL render produces. The normalizer drops them, keeping
`content: None` since that is a valid message shape.
Declarative crews are unaffected: they use `CrewAgentDefinition`, which has no
`input` field at all.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* test(flows): pin content=None survival through agent input normalization
A filter-all-None change would silently drop the assistant turn that only
requests tool calls, and no test covered that key.
Found by CodeRabbit on #7066.
* test(flows): cover the agent action through kickoff, not the helper
The existing tests called _normalize_agent_input directly, so nothing pinned
that Expression.render_template -> normalization -> Agent.kickoff_async keeps a
message list intact. Removing the normalization call now fails this test.
Found by CodeRabbit on #7066.
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
Co-authored-by: Lorenze Jay <63378463+lorenzejay@users.noreply.github.com>
* feat(flow): let a declaration name the router's response format
`conversational.router.response_format` was typed `Any` and dropped with a
warning, because `_router_response_format` hands its value straight to
`llm.call(response_format=...)`, which needs a real class. So the router always
used its synthesized fallback: `intent: str` with the route labels only in a
field description.
The field now takes the same `{"python": "module.path.Class"}` shape a crew
agent's `response_format` uses, resolved through the same
`_resolve_model_class`. That brings the project-root containment with it -- a
declaration cannot reach outside the project to import code -- and gives the
router a `Literal[...]` of the real route labels instead of a bare string.
The DSL projection now emits that shape too, so a live class on a Python flow
round-trips as `{"python": ...}` rather than an opaque `{"ref": ...}` that
nothing could reload.
A bare `module:qualname` ref is now a load-time validation error instead of
being silently discarded; the test that pinned the old drop-with-warning
behavior is updated to assert that.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(flow): do not project a response format that cannot be reloaded
`_python_reference` emitted a dotted path for any class, including two that
cannot be imported back: a non-Pydantic class, and one defined inside a
function, whose `__qualname__` carries `<locals>`. The definition then held a
ref that only failed when something tried to resolve it.
Both are dropped at projection time with a warning naming why, so a reload
falls back to the synthesized response format. The live class still drives the
running flow; only the projection omits it.
Found by CodeRabbit on #7063.
* test(flows): assert the response_format omission warnings
The projection tests only checked for None, so removing the warning that tells
an author their response_format was dropped would still pass.
Found by CodeRabbit on #7063.
* fix(flows): only project a response_format ref that imports back
The check rejected <locals> classes but still emitted a path for a nested one.
The loader splits a ref on its last dot, so module.Outer.Route resolves
module.Outer as a module that does not exist - proven: reload raised
JSONProjectError. A create_model() class held only in a local is unreachable
the same way.
Projection now confirms module.qualname resolves back to the class, against the
already-imported module so it never triggers an import.
Found by CodeRabbit on #7063.
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(core): map GPT-5.6 to the official 1.05M context window
LiteLLM fallback treated Sol, Terra, Luna, and the gpt-5.6 alias as unknown and used the 8k default.
* fix(openai): give GPT-5.6 its own 1.05M window
Native lookup matched gpt-5 first, so Sol, Terra, and Luna inherited 1,047,576. Longest-prefix matching keeps gpt-5 and gpt-5.4-mini on their own sizes.
* fix(azure): map GPT-5.6 deployments to the official 1.05M window
Azure had no gpt-5 / gpt-5.6 entry, so Sol, Terra, and Luna fell back to 8k.
* feat(cli): list GPT-5.6 Sol, Terra, and Luna in curated catalogs
The family is generally available; keep gpt-5.5 as the offline default.
* refactor: keep context-window tables in longest-prefix order
Drop the runtime sort and document that new keys must be inserted longest-first so startswith matching stays correct.
* fix(core): resolve prefixed LiteLLM models to the GPT-5.6 window
openai/gpt-5.6-luna kept its provider prefix on self.model, so startswith matching missed the 1.05M mapping. Strip recognized prefixes for lookup and leave unknown ones intact.
- Updated the description to clarify the use of `handle_turn` and structured streaming in multi-turn chat applications.
- Added a warning about the experimental nature of the conversational features.
- Improved the overview section to include structured streaming and refined the explanation of session handling.
- Enhanced the API documentation for `handle_turn`, `stream_turn`, and `chat` methods, emphasizing their roles in conversational flows.
- Clarified the turn lifecycle and the handling of user messages within the flow.
- Updated examples to reflect changes in message handling and session tracing.
- Ensured consistency across language versions in the documentation.
* feat(flow): let a chat flow declare its own state shape
A conversational declaration could only use `state: {type: pydantic, ref: ...}`
pointing at a `ConversationState` subclass. Every other shape loaded clean and
then died on the first turn -- inline `json_schema` and a non-subclass ref with
`AttributeError: 'StateWithId' object has no attribute 'messages'`, and
`type: dict` with `AttributeError: 'dict' object has no attribute 'id'`.
`Flow._compose_extension_state_model` is a new runtime extension seam -- the
seventh alongside the existing six -- applied to the model built from `state:`
before the engine wraps it for `id`. The conversational mixin uses it to add
the chat fields to whatever the declaration asked for, so declared fields and
defaults survive; a model that already extends `ConversationState` is returned
untouched, so today's supported shape is a no-op.
`dict` and `unknown` state cannot carry those fields at all, so the default
extension state supplies the real shape (seeded from the declared defaults
where they fit) rather than forbidding it. Raising instead would break
construction, and `Flow[dict]` with `conversational = True` constructs today --
`crewai flow plot` and definition-only consumers would stop working.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(flow): keep declared defaults and cover an unbuildable state model
Two review follow-ups on the declared-state work.
A `dict` state's defaults are arbitrary keys, and the fallback kept only the
ones matching `ConversationState`, so `{"type": "dict", "default": {"topic":
"ai"}}` lost `topic` before the first turn and an action reading `state.topic`
would fail. They are carried as extras now.
And a declared `pydantic`/`json_schema` state whose model cannot be built --
a bad ref, an invalid schema -- fell through to a plain dict with none of the
chat fields, so the turn died on `state.id` instead. The engine now re-asks the
extension in that case, as if nothing had been declared.
Found by Cursor and CodeRabbit on #7061.
* refactor(flows): drop the unreachable extension-state fallback
The _initial_state_t branch sat after an unconditional return. The
state_definition is None case and _conversation_state_with_defaults now cover
every path that used to reach it.
Found by Cursor on #7061.
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(telemetry): report project creation with the id minted for it
Acquisition was only observable from a project's first run. That misses every
project created and never run, and dates the rest to the wrong day.
All three scaffolding paths already mint a project_id into the new
pyproject.toml. None of them reported it, and two of them - create_crew and
create_json_crew, which is the default `crewai create crew` path - emitted no
telemetry at all.
`Project Created` carries the kind (crew, json_crew, flow) and the id that was
just minted, and is emitted after the mint so it can carry it.
The attribute is `created_project_id`, not `project_id`, because those are two
different things. CommonAttributesSpanProcessor stamps `project_id` on every
span from get_project_id(), which reads the current working directory and is
cached for the life of the process - during `crewai create` that describes the
directory the command was run from, not the project being created. Reusing the
name would have given one column two meanings depending on span type.
Nothing is emitted for `create_crew(parent_folder=...)`: that adds a crew to a
project which already exists, mints no id, and is not an acquisition.
The existing `Flow Creation` span is left exactly as it is. Note for whoever
reads it: it is emitted from two places with two different meanings - CLI
scaffolding (create_flow.py) and runtime flow construction (event_listener.py on
FlowCreatedEvent) - so it cannot separate acquisition from usage. Not changed
here because it is a live series and renaming it would break continuity.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
* test(telemetry): stop the creation-span tests exporting to the real collector
The recorded_spans fixture has to enable telemetry for its assertions to mean
anything - a disabled Telemetry never builds self.provider, so every assertion
would pass vacuously against a non-recording span. But enabling it is exactly
what makes __init__ wire a BatchSpanProcessor around the real
SafeOTLPSpanExporter, pointed at the production collector.
Measured, with a spy on both SafeOTLPSpanExporter classes reporting at
interpreter exit: before this change the file made 3 real export calls, handed 3
synthetic Project Created spans with invented created_project_id values to the
production exporter, and completed 3 connects to the collector. After: 0, 0, 0.
Sampling at pytest_sessionfinish reports 0 either way and is how this was missed
- BatchSpanProcessor flushes on a background timer, and with no
provider.shutdown() the flush lands in the atexit handler, which runs after
sessionfinish.
--block-network does not prevent it: it is function-scoped and only swaps
socket.connect, which a background batch thread outlives.
Follows telemetry_with_exporter in tests/telemetry/test_tracer_isolation.py:
_NullExporter swapped in before construction, _register_shutdown_handlers
suppressed so no atexit hook is left behind, and provider.shutdown() in finally.
Patch target is crewai_core because that is where this Telemetry comes from.
Also disambiguates the docs rows: the minted ID belongs to the new project, not
to the directory the command ran in, and the two can differ. Reworded in all four
languages rather than renaming the token to created_project_id - this table
documents data, never span-attribute keys (kind and crewai_version on the same
row are unnamed), and `project_id` is already the page's name for the
pyproject.toml key.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
* docs(ar): use tanwin fath on the letter, not on the alif
مشروعًا / جديدًا rather than مشروعاً / جديداً, in the row added by this PR.
Both forms appear in docs/edge/ar (3 each), so this is not a house convention
being broken either way; the corrected form is the more standard one and the text
is mine.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
* docs: stop the creation row implying the span's project_id holds the minted value
CodeRabbit re-raised this as Major after I rejected the first version, and it was
right to. My rejection argued the page never names wire keys, so introducing
created_project_id would be its only one. That part still holds -- grep finds no
attribute key anywhere in the four files. But it was the wrong conclusion: the row
still used the token `project_id` for a value the span does NOT carry under that
key, while the same span's real project_id holds the cwd-derived value. The row
also already exposes literal wire values (`crew`, `json_crew`, `flow` are the
actual kind values), so "this page has no wire detail" was overstated.
Dropping the token resolves the ambiguity without adding the page's only key
name: the row now says "the project ID minted for that new project", and names
`project_id` only to say the minted value is recorded separately from it.
All four languages. No docs/v*/ touched.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
* docs: use an em dash in the creation row, matching the rest of the page
The two ASCII `--` occurrences in these files were both mine, introduced by this
PR: the page otherwise uses em dashes throughout (en 4, ar 4, ko 2, pt-BR 4).
CodeRabbit flagged pt-BR; the same slip was in en, so both are fixed. Now zero
ASCII `--` across all four language files.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* feat(telemetry): record whether a run had inputs, without recording the inputs
The `crew_inputs` payload is gated behind `share_crew` and stays that way, so the
only way to tell a parameterised run from an unparameterised one was to read a
gated key: it is present on roughly 0.02% of spans, all of them opt-in sharers.
That is a measurement of people who opted into sharing, not of users.
`crew_inputs_present` carries just the answer -- "true"/"false" -- on the
already-ungated `Crew Created` span. The payload stays inside the `share_crew`
branch, so nothing new about the contents of anyone's inputs is collected.
A string, for the reason `crew_memory` is a string, and the encoding matters
more here because the majority case is the empty one. Measured over a single day
(312,424,709 spans): `vInt64='0'` occurs 0 times and `vBool='false'` occurs 0
times, while `vStr='0'` does occur. proto3 omits the zero value for ints as well
as bools, so an integer key count would have silently dropped every
unparameterised run -- and among sharers, 54.46% of runs pass `{}`.
`{}` and `None` are both "false": an empty dict parameterises nothing, so
truthiness is the question being asked.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
* test(telemetry): assert input keys are absent too, not only input values
The gating test checked only the input value. A regression that emitted the input
keys - json.dumps(sorted(inputs)) or similar - would have passed it, and key
names are user data as much as values are.
Verified by injecting exactly that regression: the new assertion fails on it and
passes once reverted.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
pip-audit started failing on every open PR. The advisory is against pip itself:
PYSEC-2026-3721 / CVE-2026-13346, which OSV records as affecting pip up to but
not including 26.2. The floor was already pinned at >=26.1.2, so the previously
patched version became the vulnerable one.
Not caused by any open PR. Reproduced on tag 1.15.17 itself (`b3ab193c3`), which
resolves pip 26.1.2: `uv run pip-audit` with CI's exact arguments reports
"Found 1 known vulnerability" there with no branch changes at all. That is why
this is its own PR rather than a fix inside whichever PR happened to run first.
Raising the floor rather than adding --ignore-vuln, since a patched release
exists: 26.2 fixes it and 26.2.1 is current. The trailing comment follows the
convention already used for setuptools>=83.0.0.
The uv.lock change is deliberately hand-scoped to pip's four lines. Running
`uv lock` -- with either uv 0.11.12 or 0.11.15 -- also re-expands environment
markers for numpy, humanfriendly, grpcio, mcp and a dozen nvidia-* packages,
because the committed lock was produced by a uv that simplifies markers
differently from any version available here. Those rewrites change CUDA and
platform resolution and have no business riding along in a security fix. The
four lines applied here are exactly the ones uv itself produced for pip.
Verified: `uv lock --check` passes, so the lock is consistent with pyproject and
needs no regeneration; pip resolves to 26.2.1; `uv run pip-audit` with CI's
arguments reports "No known vulnerabilities found, 1 ignored"; crewai and
crewai_core still import.
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* fix(flow): a resumed flow must emit flow_started, not only flow_finished
_resume_async_body gated FlowStartedEvent behind suppress_flow_events while the
matching FlowFinishedEvent a few hundred lines below stayed ungated. A suppressed
resume therefore emitted an unpaired finish: a flow that reported finishing
without ever having started. That is worse than a missing row - it breaks every
started/finished pairing and any duration or funnel built on it, and it removed
the resumed leg from telemetry entirely.
suppress_flow_events is also the wrong gate for emission. It asks for console
quiet: _flow_origin in events/event_listener.py says so explicitly and notes it
"can legitimately be set on a caller's own flow", and the listener already
honours it at each point where it prints. So a user who set it on their own flow
for quiet output silently lost their resumed runs from telemetry.
The emit is now unconditional, matching both the kickoff path - which never gated
it - and the FlowFinishedEvent it pairs with. The method-execution gates in this
function are left alone: _execute_method gates the same events on the same flag,
so those are symmetric and intended.
Internal flows that set this flag (agent_executor, the memory recall/encoding
flows) will now emit a started event when resumed. That is the point, and the
is_crewai_internal marker already keeps them out of user-facing flow metrics -
a distinction _flow_origin draws precisely because this flag cannot carry it.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
* fix(flow): emit the whole lifecycle on a suppressed resume, not just the start
The first commit on this branch ungated FlowStartedEvent on the resume path
while FlowFinishedEvent stayed gated, which left a suppressed resume emitting a
start with no terminal event. CodeRabbit and cursor both caught it.
The premise that commit was written against was wrong: origin/main gated the
started event and the finished event, so it emitted neither and was symmetric.
It was the detection that was broken, not the code -- a fixed-line lookback for
the enclosing condition missed the multi-line `if (not self.suppress_flow_events
and not self._should_defer_trace_finalization()):` guarding the finish.
The defect is therefore not an unpaired event on main but a silent one: a
resumed run with suppress_flow_events set emits no lifecycle events at all, so
it never reaches a listener or the trace exporter and the run is invisible
downstream. kickoff_async emits them either way and lets listeners filter, and
suppress_flow_events asks for console quiet rather than for telemetry to be
dropped, so resume now matches kickoff.
_should_defer_trace_finalization() still withholds the finish, which is a real
reason: finalize_session_traces() emits it later instead.
respect_suppression is deleted rather than left defaulting to False -- the
resume call site was its only caller, so nothing passes True any more.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(flow): accept crew-style LLM config in a conversational declaration
`conversational.llm` / `intent_llm` / `answer_from_history_llm` and
`router.llm` only accepted a model-id string, so a declaration could not set
`max_tokens`, `temperature` or anything else a declarative crew's agent can.
`_coerce_llm` now delegates to `crewai.utilities.llm_utils.create_llm` -- the
same helper the crew/agent declaration layer resolves through -- so the shapes
match: a model-id string, a config mapping, an `LLMDefinition`, or a live
`LLM`/`BaseLLM` passed straight through.
It keeps one thing `create_llm` does not: `create_llm(1234)` takes the int as a
model name and returns an LLM that only fails later with a provider error. A
declaration is hand-written, so a non-string, non-mapping value raises now
instead. A mapping missing `model` keeps `create_llm`'s own message.
The contract fields stay permissively typed and gain descriptions naming the
accepted shapes. Tightening them to `str | LLMDefinition` would break the DSL
projection: a live custom `BaseLLM` whose config dump lacks a `model` key
degrades to a `{"ref": ...}` mapping, which such a type would reject -- turning
`flow_definition()` on an existing Python flow into a validation error.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(flow): resolve declared LLM mappings for intent classification
`intent_llm` and `answer_from_history_llm` were documented as taking the same
shapes as `llm`, but both route through `_collapse_to_outcome`, whose own
coercion accepts only `str | BaseLLM`. A declared config mapping reached it
unchanged and raised "Invalid llm type: <class 'dict'>" mid-turn -- so the
documentation promised something that failed.
Also fixes the field descriptions. The previous commit's `llm` description
landed on `FlowConversationalRouterDefinition.llm` rather than
`FlowConversationalDefinition.llm`, because both fields are literally
`llm: Any = None` and the first match won. All four now describe their own
field and name every accepted shape, including `LLMDefinition` and a live
instance.
Test changes: adds an `LLMDefinition` resolution case, and the declared-mapping
turn test now patches `create_llm` to prove the mapping reaches it instead of
swapping the config out beforehand, which proved nothing.
Found by Cursor and CodeRabbit on #7062.
* docs(flows): name the full router LLM precedence; pin the coercion path
The conversational llm description skipped intent_llm in the router fallback
order (router.llm, then intent_llm, then llm), and the intent_llm test replaced
the declared mapping with a scripted LLM before the turn, so it never exercised
the coercion. Patch create_llm instead: removing the coercion now fails the
test with "Invalid llm type: <class 'dict'>".
Found by CodeRabbit on #7062.
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(cli): open the conversational TUI for a declarative chat flow
`crewai run` refused a declarative conversational flow and told the user to
drive it from Python. That was wrong: the conversational TUI already exists and
already does this job. `CrewRunApp(conversational=True)` renders a chat pane and
drives `handle_turn` per message (crew_run_tui.py:833-935), and
`kickoff_flow._run_conversational_flow_tui` launches it for a Python
conversational Flow.
A declaration-built flow satisfies everything that TUI needs -- `handle_turn`,
a settable `defer_trace_finalization`, and `finalize_session_traces()` -- so it
now routes there instead of exiting.
A chat loop still needs a terminal. A headless run (`is_interactive()` false,
which folds in CREWAI_DMN) says what it would have needed rather than kicking
off a single turn and presenting that as the whole conversation.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(cli): do not send a human-feedback chat flow to the Textual TUI
A declaration can carry both a `conversational:` block and a method with
`human_feedback:` -- verified, both predicates return True on the same flow.
Routing it to the chat TUI hangs: the runtime collects feedback with a blocking
`input()` (flow/runtime/__init__.py:3719) that Textual cannot service, so the
prompt is never shown. The STEPS TUI already declines these for exactly this
reason. Such a flow now falls back to the terminal REPL, which can prompt.
Also updates the guide in en/ar/ko/pt-BR: it still said `crewai run` has no
chat loop and exits, which is now the opposite of what the CLI does.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(cli): reject --inputs on a conversational flow instead of dropping it
The conversational branch returns before `_resolve_flow_inputs`, and the TUI
calls `handle_turn(message)` -- which owns the kickoff inputs, passing
`{"id": session_id}` itself. So any `--inputs` value was silently discarded and
the conversation ran as if it had been applied. It now errors, and says that
resuming a session by id is not wired up yet rather than implying it worked.
Also corrects the Arabic guide: `مُوجّه محجوز` reads as "reserved router", not
the blocking prompt it describes.
Both found by CodeRabbit on #7060.
* fix(cli): document the conversational routing exceptions
Three review follow-ups:
- The Arabic guide read خدمته (masculine) against the feminine
مُطالبة introduced by the last fix.
- Both docstrings described a routing path that now has exceptions: a
conversational declaration rejects --inputs and skips state-schema
resolution, and a human-feedback one uses the terminal REPL.
- The --inputs rejection test accepted SystemExit(0); it now pins code 1.
Found by CodeRabbit on #7060.
* fix(cli): reject --inputs on a chat flow even when it parses empty
parse_inputs_json returns {} both when the option is absent and when the user
passes --inputs "{}", so the falsy check started the TUI for the second case
while the docs said it was unsupported. The conversational path now takes
whether the option was supplied, not what it parsed to.
Documents the restriction in en, ar, ko and pt-BR.
Found by CodeRabbit on #7060.
* test(cli): pin the headless conversational exit status
pytest.raises(SystemExit) also accepts SystemExit(0), so the error path could
regress to a successful exit unnoticed.
Found by CodeRabbit on #7060.
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
This pipeline cannot carry a false boolean. Measured across 218,400,577 spans,
not one carries vBool=false - proto3 omits the bool zero value, so false is
never serialized and arrives as the key simply being absent. "Memory disabled"
was therefore structurally unrepresentable, and presence had to stand in for the
value, which is why crew_memory read 1 for 99.8% of crews against a field that
defaults to False.
The fix is the convention this file already documents and applies to `resumed`
and `conversational`; crew_memory is the attribute those comments name as the
outstanding case. It was the only remaining CrewAI-emitted boolean attribute -
checked empirically: every other attribute appearing in vBool comes from
third-party instrumentation.
Truthiness rather than `is True`, per the decision that memory counts as enabled
when set by any means: a Memory, MemoryScope or MemorySlice instance is enabled
just as much as `memory=True`. None of those classes defines __bool__ or __len__,
so an instance is always truthy.
Tests cover all four inputs - True, False, None and an instance - and reuse the
existing guard that no attribute is ever passed as a bare boolean. Verified they
fail against the unpatched emitter.
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(cli): backfill project_id from every user-invoked project command
`crewai run` has always backfilled: a project declaring [tool.crewai] without a
project_id gets one minted the first time it runs. No other command did, so a
project driven entirely through `crewai test`, `crewai deploy` or
`crewai traces enable` never acquired an id and every one of its runs stayed
unattributable - which is the denominator problem, not a cosmetic gap.
Adds the same call to train, replay, test, login, deploy create, deploy push,
flow add-crew, enterprise configure and traces enable. Every one is an action the
user explicitly invoked, which is the condition run_crew already relies on, so this
is the existing principle applied evenly rather than a new policy. It is still never
called from the SDK during kickoff, and get_or_create_project_id still refuses to
create the [tool.crewai] table, so an unrelated directory is never rewritten.
`crewai flow kickoff` is deliberately untouched: it delegates to run_crew and
already inherits the backfill. A test pins that so the delegation is not
accidentally duplicated. There is no `crewai evaluate` command - `crewai test` is
that path.
The call is the first statement in each command so a command that later fails still
leaves the project with an id. The tests patch the backfill to raise, which proves
the call happened and guarantees nothing after it runs, so no test touches user
settings, spawns a subprocess or reaches the network. Verified they fail against the
unpatched module: 9 command tests fail, the 2 guard tests still pass.
Tests live under lib/crewai/tests/cli/ because that is the path the required CI job
runs; nothing runs lib/cli/tests/.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
* test(cli): assert the backfill at runtime instead of reading source text
Addresses CodeRabbit and github-code-quality on #7057. The two guard tests
grepped module source for a call string, which asserts on formatting rather than
behavior: a reformat would break them and a real regression could slip past.
They now invoke the commands in an isolated project and assert on observed calls.
The flow-kickoff test patches the two distinct import sites separately and asserts
run_crew's is called exactly once while cli's is not called at all, which is what
makes 'delegates' and 'duplicates' distinguishable at runtime rather than by
reading the file.
Verified both catch what they claim: injecting a duplicate call into flow_run
fails the delegation test, and removing run_crew's own call fails the run test.
This also drops the module-level 'import crewai_cli.cli as cli_module' that mixed
import styles with the existing 'from crewai_cli.cli import crewai', which is the
code-quality finding - the rewrite removes the need for it entirely.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
* test(cli): make the exact-once assertion observable
Addresses CodeRabbit on #7057, and the finding was correct: with
side_effect=_BackfillReached the mock raised on first use, so call_count == 1 was
guaranteed by the mock rather than by the code. A second backfill call inside the
same run_crew execution could never have been observed.
Both backfill mocks now return normally and execution is stopped at the first call
AFTER the backfill (configured_project_json_crew), so the recorded count is real.
Verified the difference this makes: injecting a duplicate get_or_create_project_id()
INSIDE run_crew now fails both tests, which the previous version could not detect at
all. The flow_run duplicate case is still caught.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
* test(cli): assert flow kickoff reaches the post-backfill boundary
Addresses CodeRabbit on #7057, and the finding was right: the flow-kickoff test
discarded the runner.invoke() result, so if the path returned or raised after one
backfill call but before configured_project_json_crew, both call-count assertions
would still have passed - for the wrong reason.
test_run_still_backfills already asserted the boundary; this makes the pair
consistent.
Verified it earns its place: injecting an early return after the backfill and
before the boundary now fails both tests, and previously would have failed
neither.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
* test(cli): pin that the backfill precedes command-specific work
Addresses CodeRabbit on #7057. The finding is valid: the parametrized test proves
the backfill is reached, not that nothing ran before it, so its assertion message
claimed more than the test established.
Fixed in two parts rather than as proposed. The message now states what the test
actually proves, and a new test pins the ordering on login: , whose first action
goes through a module-level name that can be patched without reaching into the
command.
Deliberately not parameterized across all nine commands, which is what the finding
suggested: that would mean naming each command's current first action, and those
change as commands evolve, so the suite would end up tracking their internals
rather than this ordering property. One representative command establishes it, and
placement is visible in the diff for the rest.
Verified it catches the regression: swapping login's first two statements so its
own work runs before the backfill fails the new test.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(telemetry): always emit project_id so absent and empty stay distinct
common_span_attributes() stamped project_id onto every span only when the project
declared one, and omitted the key otherwise. That makes two different situations
indistinguishable downstream: a client too old to report a project id at all, and
a current client whose project simply declares none.
The consequence is not cosmetic. The share of clients that COULD have reported an
id is the denominator of every attribution rate, and with both cases collapsed into
"key absent" that denominator cannot be computed at all - it can only be inferred
from a version floor, which is fragile and silently wrong for any client that
backports or pins.
The key is now always present and is the empty string when the project declares
none. It still never invents an identity: get_project_id() remains read-only and
minting stays with the CLI commands a user explicitly invoked.
Two existing tests asserted the old contract and are updated rather than deleted,
one of them renamed because its name described the behaviour that changed. A third
test is added pinning the distinction itself. The test asserting that a foreign
application's spans are never annotated is unaffected and still passes: this
changes what our processor stamps, not where it is attached.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
* docs(telemetry): note that a failed project_id lookup also yields empty
Addresses CodeRabbit on #7056. The docstring and inline comment described the
empty string only as an undeclared project, but the except branch sets
project_id to None and so lands on the same empty value. Both are deliberately
indistinguishable - neither yields an id - and saying so matters to anyone
debugging an empty value, since an unreadable pyproject.toml looks identical to
a project that simply declares nothing.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* test(flow): unskip the conversational end-to-end suite
The `conversational_graph_broken` marker parked 21 end-to-end conversational
tests with the reason "the definition-first start migration intentionally
stopped scanning inherited methods, so that graph no longer registers".
That is no longer true: `_iter_flow_methods` walks the MRO for
`__conversational_only__` methods (dsl/_utils.py:406-420), so a
`conversational = True` subclass does register `route_conversation`,
`converse_turn`, `end_conversation` and `answer_from_history_turn` — which
`test_flow_definition.py:391-407` already asserts.
Removing the marker takes the file from 47 passed / 21 skipped to 68 passed.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(flow): make conversational opt-in unmistakable
Opting a Flow into chat took two statements, and forgetting one failed
silently. With `@ConversationConfig(...)` but no `conversational = True`:
`FlowDefinition.conversational` came back `None`, the built-in graph never
registered, and `handle_turn()` returned `None` without appending a message
or raising — while `chat()` reported "only available on conversational flows"
on a class that was literally decorated with a conversational config.
Three changes:
- `ConversationConfig.__call__` now also sets `conversational = True`. Every
field on the config is consumed only by the conversational graph, so a
decorated non-conversational Flow could only ever discard it.
- `FlowConversationalDefinition.enabled` defaults to True. The block is absent
on non-conversational flows, so declaring it is the opt-in; `enabled: false`
remains an explicit opt-out.
- `handle_turn()` raises like `chat()` and `stream_turn()` already do instead
of silently returning `None`.
Setting `conversational = True` by hand still works and is still the way to
opt in without a config.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(flow): let a declaration drive conversational mode
`FlowDefinition.conversational` was written by the DSL projection and read by
nothing: every conversational gate resolved through `type(self).flow_definition()`
— the class projection — instead of `self._definition`, the declaration a flow
was actually built from. So `Flow.from_declaration()` on a definition with a
conversational block produced a flow that reported itself non-conversational,
dropped the user message, and never registered its declared routes.
Resolution rules, applied consistently:
- Structure (enabled, methods, route labels, builtin/internal routes) comes
from `self._definition`, which is the loaded declaration for a declarative
flow and the class projection otherwise. Both paths now agree.
- Behavior (`conversational_config`) still prefers the class attribute, which
can hold live objects — a configured LLM, a custom BaseLLM, a response_format
model class — that the serializable definition degrades to a config dict or a
`module:qualname` ref. Reading the definition first would silently downgrade
every decorated Python flow. A declaration-built flow has no class config, so
`_config_from_definition` supplies one, cached for stable identity.
- A declared `state:` block is never replaced. `_create_default_extension_state`
is consulted before `_create_definition_state`, so returning `ConversationState`
there discarded every field the declaration asked for. It now yields to a
declared state and only supplies the default when nothing else does.
The class-scoped `_is_conversational` / `_conversational_definition`
classmethods are gone; the existing instance-scoped `_is_conversational_enabled`
is the single gate.
A router `response_format` that survived serialization as a ref or schema dict
is dropped with a warning rather than handed to `llm.call()`, which needs a
real class.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(flow): synthesize the built-in conversational methods for declarations
A declaration carrying `conversational: {}` loaded clean and then ran zero
methods and returned `None`, because the four built-in graph handlers are
inherited from `_ConversationalMixin` and a declaration has nothing to inherit
from. Authors had to name `crewai.experimental.conversational_mixin:_Conversational
Mixin.route_conversation` and three siblings by hand.
`Flow._extend_definition` is a new runtime extension hook, called once
`_definition` is resolved and before methods are bound. The conversational
mixin overrides it to fill in `route_conversation`, `converse_turn`,
`end_conversation` and `answer_from_history_turn` when they are missing, using
the same code refs the DSL projection already emits so a declaration and a
class projection of the same flow produce identical method definitions.
Synthesis is deliberately a runtime concern, not a contract one:
`FlowDefinition` stays independent of the authoring layer and of the engine,
as `test_flow_definition_contract_is_dsl_agnostic` requires, and a loaded
declaration still serializes back to exactly what its author wrote.
Route descriptions are now carried by the contract. The DSL projects a handler
docstring's first line into `FlowMethodDefinition.description`, and the router
catalog reads that before falling back to the live docstring. This also fixes
a real defect: for a declarative flow `getattr(type(self), handler_name, None)`
is `None`, and the old code read `None.__doc__` — so the router LLM was told a
route's description was "The type of the None singleton."
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(flow): let an agent or crew handler reply in a conversation (#7034)
`handle_turn` promotes a handler's return value to the assistant message when
the handler did not append one itself, but the check required `isinstance(result,
str)`. Declarative `agent` and `crew` actions return `LiteAgentOutput` and
`CrewOutput`, whose text lives on `.raw` — so the most natural declarative
handler was exactly the one whose reply never reached the transcript.
`_is_public_turn_result` now unwraps `.raw` before deciding, matching
`_stringify_result`, which already did. The routing-artefact guards are applied
to the unwrapped text, so an output echoing a route label or this turn's intent
is still not promoted.
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(flow): keep privately recorded agent results out of the transcript
Unwrapping `.raw` in `_is_public_turn_result` made the end-of-turn fallback
promote `LiteAgentOutput` / `CrewOutput` objects that the handler had already
recorded via `append_agent_result` with the default private visibility. That
call does not set `_assistant_reply_appended`, so the fallback republished the
very object the handler asked to keep private — defeating
`visible_agent_outputs`.
Reproduced against `main` for contrast: no leak before the unwrap, leak after.
`append_agent_result` now remembers the object it recorded for the duration of
the turn, and the fallback skips anything already routed that way. The check is
identity-based on purpose: a handler that records scratch work privately and
then returns a user-facing summary still gets that summary promoted, which a
simple "handler already handled it" flag would have broken.
Found by Cursor Bugbot on #7033.
* feat(flow): mark a declarative chat flow conversational on the instance
A declaration enables chat through `conversational.enabled`, without the
`conversational = True` class attribute. Callers outside this package
capability-check that attribute -- the AG-UI serving guide states it as a
requirement -- so it disagreed with `_is_conversational_enabled()` and a
declarative conversational flow looked non-conversational from outside.
`_extend_definition` now sets it on the instance when the definition enables
chat. Instance-only on purpose: the DSL projection reads the attribute off the
*class* to decide whether to emit a conversational block, so setting it there
would make every later subclass look conversational.
Verified on a real declarative flow: `conversational` and `stream_turn` both
now satisfy the documented capability check, while `Flow.conversational` and
any later subclass stay False.
* refactor(flow): derive routing-artefact labels from the effective routes
`_is_public_turn_result` matched a literal set of route labels, duplicating
knowledge that `_effective_builtin_routes()` already owns. A declaration that
adds a builtin route was not covered, so a handler echoing that label could be
promoted into the transcript -- the same class of divergence already fixed for
`route_turn`.
Verified the derived set is byte-identical to the old literal one for a
class-based flow, so this is a pure generalization: `conversation` and
`route_to_flow` stay explicit because neither is a route.
Also replaces a tuple-index lambda in the chat REPL test with a named
`input_fn`; it relied on tuple evaluation order and on the list being mutated
before its length was read.
Both found by CodeRabbit on #7033.
* docs(flow): document declarative conversational flows
The authoring skill told LLM authors "use top-level `conversational` only when
the user asks for a chat flow" while documenting none of its 19 fields — there
was no ModelSpec for either conversational model, so the API reference appendix
skipped them entirely.
- Adds both conversational models to the skill reference, with field
descriptions, and registers them under the existing `conversational` skip so
`skills(skips=["conversational"])` still suppresses the whole block.
- Adds authoring rules: do not declare the built-in graph, do not name a
handler after the route it listens to, do not declare state unless it needs
extra fields, and give every route handler a description.
- Documents the declarative form in the conversational-flows guide across en,
ar, ko and pt-BR, including what is supplied automatically, how to run it,
and what a declaration cannot express (live LLM objects, a response_format
class, route_turn overrides).
- `crewai run` on a conversational declaration now says it has no chat loop and
points at handle_turn/chat, instead of quietly running a single turn and
exiting. It fails closed: a flow that cannot be inspected runs normally.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(flow): render the conversational router section in the skill
Both conversational models shared one `Conversational` section, and the
template renders only the first model of a non-union section. The router's
fields were therefore dropped from the API reference and the generated link to
them pointed at a heading that did not exist.
Also softens the built-in-handler rule: `_extend_definition` keeps an
author-supplied entry and the guide documents that override, so the skill
should say to omit those handlers by default rather than never declare them.
Adds regression tests for both sections rendering, for every field of both
models appearing, and for `skips=["conversational"]` suppressing both.
Both found by CodeRabbit on #7035.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* docs(flow): correct the route-description rule in the authoring skill
The rule said every route handler must define `description`, but
`conversational.router.route_descriptions` is the higher-precedence source --
`_build_route_catalog` checks the overrides before falling back to the method
description. Either one describes a route; the rule now says so, and says what
happens when a route has neither.
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
Co-authored-by: ViditOstwal <viditostwal@gmail.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
* test(flow): unskip the conversational end-to-end suite
The `conversational_graph_broken` marker parked 21 end-to-end conversational
tests with the reason "the definition-first start migration intentionally
stopped scanning inherited methods, so that graph no longer registers".
That is no longer true: `_iter_flow_methods` walks the MRO for
`__conversational_only__` methods (dsl/_utils.py:406-420), so a
`conversational = True` subclass does register `route_conversation`,
`converse_turn`, `end_conversation` and `answer_from_history_turn` — which
`test_flow_definition.py:391-407` already asserts.
Removing the marker takes the file from 47 passed / 21 skipped to 68 passed.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(flow): make conversational opt-in unmistakable
Opting a Flow into chat took two statements, and forgetting one failed
silently. With `@ConversationConfig(...)` but no `conversational = True`:
`FlowDefinition.conversational` came back `None`, the built-in graph never
registered, and `handle_turn()` returned `None` without appending a message
or raising — while `chat()` reported "only available on conversational flows"
on a class that was literally decorated with a conversational config.
Three changes:
- `ConversationConfig.__call__` now also sets `conversational = True`. Every
field on the config is consumed only by the conversational graph, so a
decorated non-conversational Flow could only ever discard it.
- `FlowConversationalDefinition.enabled` defaults to True. The block is absent
on non-conversational flows, so declaring it is the opt-in; `enabled: false`
remains an explicit opt-out.
- `handle_turn()` raises like `chat()` and `stream_turn()` already do instead
of silently returning `None`.
Setting `conversational = True` by hand still works and is still the way to
opt in without a config.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(flow): let a declaration drive conversational mode
`FlowDefinition.conversational` was written by the DSL projection and read by
nothing: every conversational gate resolved through `type(self).flow_definition()`
— the class projection — instead of `self._definition`, the declaration a flow
was actually built from. So `Flow.from_declaration()` on a definition with a
conversational block produced a flow that reported itself non-conversational,
dropped the user message, and never registered its declared routes.
Resolution rules, applied consistently:
- Structure (enabled, methods, route labels, builtin/internal routes) comes
from `self._definition`, which is the loaded declaration for a declarative
flow and the class projection otherwise. Both paths now agree.
- Behavior (`conversational_config`) still prefers the class attribute, which
can hold live objects — a configured LLM, a custom BaseLLM, a response_format
model class — that the serializable definition degrades to a config dict or a
`module:qualname` ref. Reading the definition first would silently downgrade
every decorated Python flow. A declaration-built flow has no class config, so
`_config_from_definition` supplies one, cached for stable identity.
- A declared `state:` block is never replaced. `_create_default_extension_state`
is consulted before `_create_definition_state`, so returning `ConversationState`
there discarded every field the declaration asked for. It now yields to a
declared state and only supplies the default when nothing else does.
The class-scoped `_is_conversational` / `_conversational_definition`
classmethods are gone; the existing instance-scoped `_is_conversational_enabled`
is the single gate.
A router `response_format` that survived serialization as a ref or schema dict
is dropped with a warning rather than handed to `llm.call()`, which needs a
real class.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(flow): synthesize the built-in conversational methods for declarations
A declaration carrying `conversational: {}` loaded clean and then ran zero
methods and returned `None`, because the four built-in graph handlers are
inherited from `_ConversationalMixin` and a declaration has nothing to inherit
from. Authors had to name `crewai.experimental.conversational_mixin:_Conversational
Mixin.route_conversation` and three siblings by hand.
`Flow._extend_definition` is a new runtime extension hook, called once
`_definition` is resolved and before methods are bound. The conversational
mixin overrides it to fill in `route_conversation`, `converse_turn`,
`end_conversation` and `answer_from_history_turn` when they are missing, using
the same code refs the DSL projection already emits so a declaration and a
class projection of the same flow produce identical method definitions.
Synthesis is deliberately a runtime concern, not a contract one:
`FlowDefinition` stays independent of the authoring layer and of the engine,
as `test_flow_definition_contract_is_dsl_agnostic` requires, and a loaded
declaration still serializes back to exactly what its author wrote.
Route descriptions are now carried by the contract. The DSL projects a handler
docstring's first line into `FlowMethodDefinition.description`, and the router
catalog reads that before falling back to the live docstring. This also fixes
a real defect: for a declarative flow `getattr(type(self), handler_name, None)`
is `None`, and the old code read `None.__doc__` — so the router LLM was told a
route's description was "The type of the None singleton."
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(flow): let an agent or crew handler reply in a conversation (#7034)
`handle_turn` promotes a handler's return value to the assistant message when
the handler did not append one itself, but the check required `isinstance(result,
str)`. Declarative `agent` and `crew` actions return `LiteAgentOutput` and
`CrewOutput`, whose text lives on `.raw` — so the most natural declarative
handler was exactly the one whose reply never reached the transcript.
`_is_public_turn_result` now unwraps `.raw` before deciding, matching
`_stringify_result`, which already did. The routing-artefact guards are applied
to the unwrapped text, so an output echoing a route label or this turn's intent
is still not promoted.
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix(flow): keep privately recorded agent results out of the transcript
Unwrapping `.raw` in `_is_public_turn_result` made the end-of-turn fallback
promote `LiteAgentOutput` / `CrewOutput` objects that the handler had already
recorded via `append_agent_result` with the default private visibility. That
call does not set `_assistant_reply_appended`, so the fallback republished the
very object the handler asked to keep private — defeating
`visible_agent_outputs`.
Reproduced against `main` for contrast: no leak before the unwrap, leak after.
`append_agent_result` now remembers the object it recorded for the duration of
the turn, and the fallback skips anything already routed that way. The check is
identity-based on purpose: a handler that records scratch work privately and
then returns a user-facing summary still gets that summary promoted, which a
simple "handler already handled it" flag would have broken.
Found by Cursor Bugbot on #7033.
* feat(flow): mark a declarative chat flow conversational on the instance
A declaration enables chat through `conversational.enabled`, without the
`conversational = True` class attribute. Callers outside this package
capability-check that attribute -- the AG-UI serving guide states it as a
requirement -- so it disagreed with `_is_conversational_enabled()` and a
declarative conversational flow looked non-conversational from outside.
`_extend_definition` now sets it on the instance when the definition enables
chat. Instance-only on purpose: the DSL projection reads the attribute off the
*class* to decide whether to emit a conversational block, so setting it there
would make every later subclass look conversational.
Verified on a real declarative flow: `conversational` and `stream_turn` both
now satisfy the documented capability check, while `Flow.conversational` and
any later subclass stay False.
* refactor(flow): derive routing-artefact labels from the effective routes
`_is_public_turn_result` matched a literal set of route labels, duplicating
knowledge that `_effective_builtin_routes()` already owns. A declaration that
adds a builtin route was not covered, so a handler echoing that label could be
promoted into the transcript -- the same class of divergence already fixed for
`route_turn`.
Verified the derived set is byte-identical to the old literal one for a
class-based flow, so this is a pure generalization: `conversation` and
`route_to_flow` stay explicit because neither is a route.
Also replaces a tuple-index lambda in the chat REPL test with a named
`input_fn`; it relied on tuple evaluation order and on the list being mutated
before its length was read.
Both found by CodeRabbit on #7033.
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
Co-authored-by: ViditOstwal <viditostwal@gmail.com>
* test(flow): unskip the conversational end-to-end suite
The `conversational_graph_broken` marker parked 21 end-to-end conversational
tests with the reason "the definition-first start migration intentionally
stopped scanning inherited methods, so that graph no longer registers".
That is no longer true: `_iter_flow_methods` walks the MRO for
`__conversational_only__` methods (dsl/_utils.py:406-420), so a
`conversational = True` subclass does register `route_conversation`,
`converse_turn`, `end_conversation` and `answer_from_history_turn` — which
`test_flow_definition.py:391-407` already asserts.
Removing the marker takes the file from 47 passed / 21 skipped to 68 passed.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(flow): make conversational opt-in unmistakable
Opting a Flow into chat took two statements, and forgetting one failed
silently. With `@ConversationConfig(...)` but no `conversational = True`:
`FlowDefinition.conversational` came back `None`, the built-in graph never
registered, and `handle_turn()` returned `None` without appending a message
or raising — while `chat()` reported "only available on conversational flows"
on a class that was literally decorated with a conversational config.
Three changes:
- `ConversationConfig.__call__` now also sets `conversational = True`. Every
field on the config is consumed only by the conversational graph, so a
decorated non-conversational Flow could only ever discard it.
- `FlowConversationalDefinition.enabled` defaults to True. The block is absent
on non-conversational flows, so declaring it is the opt-in; `enabled: false`
remains an explicit opt-out.
- `handle_turn()` raises like `chat()` and `stream_turn()` already do instead
of silently returning `None`.
Setting `conversational = True` by hand still works and is still the way to
opt in without a config.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(flow): let a declaration drive conversational mode
`FlowDefinition.conversational` was written by the DSL projection and read by
nothing: every conversational gate resolved through `type(self).flow_definition()`
— the class projection — instead of `self._definition`, the declaration a flow
was actually built from. So `Flow.from_declaration()` on a definition with a
conversational block produced a flow that reported itself non-conversational,
dropped the user message, and never registered its declared routes.
Resolution rules, applied consistently:
- Structure (enabled, methods, route labels, builtin/internal routes) comes
from `self._definition`, which is the loaded declaration for a declarative
flow and the class projection otherwise. Both paths now agree.
- Behavior (`conversational_config`) still prefers the class attribute, which
can hold live objects — a configured LLM, a custom BaseLLM, a response_format
model class — that the serializable definition degrades to a config dict or a
`module:qualname` ref. Reading the definition first would silently downgrade
every decorated Python flow. A declaration-built flow has no class config, so
`_config_from_definition` supplies one, cached for stable identity.
- A declared `state:` block is never replaced. `_create_default_extension_state`
is consulted before `_create_definition_state`, so returning `ConversationState`
there discarded every field the declaration asked for. It now yields to a
declared state and only supplies the default when nothing else does.
The class-scoped `_is_conversational` / `_conversational_definition`
classmethods are gone; the existing instance-scoped `_is_conversational_enabled`
is the single gate.
A router `response_format` that survived serialization as a ref or schema dict
is dropped with a warning rather than handed to `llm.call()`, which needs a
real class.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
Co-authored-by: ViditOstwal <viditostwal@gmail.com>
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
Connection events used the raw endpoint as `server_name`, so traces
titled the row with the full Bright Data URL including query params.
HTTP and SSE `_get_server_info` now emit the hostname and keep the
full URL on `server_url`.
* test(flow): unskip the conversational end-to-end suite
The `conversational_graph_broken` marker parked 21 end-to-end conversational
tests with the reason "the definition-first start migration intentionally
stopped scanning inherited methods, so that graph no longer registers".
That is no longer true: `_iter_flow_methods` walks the MRO for
`__conversational_only__` methods (dsl/_utils.py:406-420), so a
`conversational = True` subclass does register `route_conversation`,
`converse_turn`, `end_conversation` and `answer_from_history_turn` — which
`test_flow_definition.py:391-407` already asserts.
Removing the marker takes the file from 47 passed / 21 skipped to 68 passed.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
* feat(flow): make conversational opt-in unmistakable
Opting a Flow into chat took two statements, and forgetting one failed
silently. With `@ConversationConfig(...)` but no `conversational = True`:
`FlowDefinition.conversational` came back `None`, the built-in graph never
registered, and `handle_turn()` returned `None` without appending a message
or raising — while `chat()` reported "only available on conversational flows"
on a class that was literally decorated with a conversational config.
Three changes:
- `ConversationConfig.__call__` now also sets `conversational = True`. Every
field on the config is consumed only by the conversational graph, so a
decorated non-conversational Flow could only ever discard it.
- `FlowConversationalDefinition.enabled` defaults to True. The block is absent
on non-conversational flows, so declaring it is the opt-in; `enabled: false`
remains an explicit opt-out.
- `handle_turn()` raises like `chat()` and `stream_turn()` already do instead
of silently returning `None`.
Setting `conversational = True` by hand still works and is still the way to
opt in without a config.
Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
---------
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
* fix: close the agent scope on every failed attempt
`_check_execution_error` only emitted `AgentExecutionErrorEvent` once the
retries were exhausted, but each retry re-enters `execute_task` and opens a
new `agent_execution_started` scope. The scopes left open were then popped
by the next ending event, so `task_failed` closed an agent scope instead of
`task_started` and the task never got its own terminal pairing. Passthrough
exceptions keep bubbling untouched, since a HITL pause must leave its scope
open for the resume.
* fix: return the retried result instead of finalizing it twice
A retry reenters `execute_task`, whose own `_finalize_task_execution`
already emitted `AgentExecutionCompletedEvent`, and the outer frame then
finalized the same result again. The duplicate used to be absorbed by the
`agent_execution_started` scope that a failed attempt left open, so
closing every attempt exposed it: the extra completed event popped
`task_started`, and the task and crew ends paired with the wrong scopes.
---------
Co-authored-by: Vidit Ostwal <110953813+Vidit-Ostwal@users.noreply.github.com>
`Telemetry.tool_usage_error` has always accepted `tool_name` and writes the
attribute when it is truthy, but no caller passed it, so every `Tool Usage Error`
span landed with an empty name. Per-tool error rates were therefore not
computable at all: named tools read zero errors while the unnamed bucket held
all of them.
Passes the tool name at the four sites where the tool is known. They are the same
two failures in both execution modes - usage-limit and execution-error, each once
in the sync `_use` and once in the async `_ause` - so the fix is symmetric across
the sync/async matrix rather than four unrelated edits.
Leaves the fifth site in `_tool_calling` unattributed on purpose, with a comment
saying why: that path is a tool-call PARSING failure, so the tool the model wanted
was never identified. The only string available is the raw, unparsed model output,
and putting that into a metrics dimension would give it unbounded cardinality. An
empty name is the honest representation there.
Adds tests over the full matrix, including the parsing case pinning the opposite
expectation. Verified they fail against the unpatched module: the four attribution
tests fail and the parsing test still passes, which is the intended split.
Claude-Session: https://claude.ai/code/session_01RfV2uMqWRcdfufMvtdCVoN
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
The `conversational_graph_broken` marker parked 21 end-to-end conversational
tests with the reason "the definition-first start migration intentionally
stopped scanning inherited methods, so that graph no longer registers".
That is no longer true: `_iter_flow_methods` walks the MRO for
`__conversational_only__` methods (dsl/_utils.py:406-420), so a
`conversational = True` subclass does register `route_conversation`,
`converse_turn`, `end_conversation` and `answer_from_history_turn` — which
`test_flow_definition.py:391-407` already asserts.
Removing the marker takes the file from 47 passed / 21 skipped to 68 passed.
Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
An MCP tool's name is derived from the server URL, so nothing on the
resolved tool records which reference it was requested by. `MCPNativeTool`
now keeps that reference as `server_reference` when `_resolve_amp` built
it, leaving servers requested by URL untouched. Hooks can then attribute a
tool call to the server the user actually selected.
* fix(OSS-128): split oversized messages before context chunking
Normalize single messages that exceed the token budget before boundary
chunking so summarization LLM calls do not replay the same context error.
Reserve summarization prompt overhead from the chunk budget for large
context windows.
* refactor(OSS-128): inline message content text extraction as lambda
* refactor(OSS-128): restore _message_content_text as a function
Revert the lambda assignment to satisfy ruff E731 and keep the helper
readable alongside the LLMMessage content shape.
* refactor(OSS-128): drop summarization prompt overhead from chunk budget
Use the full context window size for message chunking instead of
subtracting a fixed prompt overhead.
* fix(OSS-128): preserve LLMMessage fields when splitting oversized content
Copy the original message attributes into each sub-message and only
replace content when expanding oversized entries for chunking.
* test(OSS-128): assert rendered summarization requests fit raw context
Verify each chunked summarization payload, including system and
instruction overhead, stays within the model limit implied by the
85% context window usage ratio.
* fix(tools): pin SSRF checks to each redirect hop and peer IP
validate_url only inspected the original URL string, so scraping fetches
could follow a 302 to an internal address or rebind DNS between check and
connect. Route safe_get through an HTTPAdapter that re-validates every hop
and connects to the authorised sockaddr, and let FORCE_SAFE_PATHS ignore a
tenant-supplied escape hatch on managed workers.
Co-authored-by: Rip&Tear <theCyberTech@users.noreply.github.com>
* Potential fix for pull request finding 'Except block handles 'BaseException''
Co-authored-by: Copilot Autofix powered by AI <223894421+github-code-quality[bot]@users.noreply.github.com>
* test(azure): use a plain stand-in for Responses API delegate mocks
MagicMock instances are not reliably stored on Pydantic PrivateAttr via
BaseLLM.__setattr__, which left _responses_delegate as None and failed
last_response_id / reset_chain assertions on CI.
Co-authored-by: Rip&Tear <theCyberTech@users.noreply.github.com>
---------
Co-authored-by: Cursor Agent <cursoragent@cursor.com>
Co-authored-by: Rip&Tear <theCyberTech@users.noreply.github.com>
Co-authored-by: Copilot Autofix powered by AI <223894421+github-code-quality[bot]@users.noreply.github.com>
2026-08-17 13:08:03 +05:30
5839 changed files with 1400463 additions and 6945 deletions
- PRs over 500 lines are labeled `size/XL` automatically
- Title must follow the same conventional commit format
- Link related issues where applicable
- Link related issues where applicable (`#123`, `Fixes #123`, or the issue URL)
- First-time contributors must open or pick an existing **open** issue first, then mention it in the PR title or body (for example `#123`). PRs without a linked open issue are closed automatically and labeled `needs-issue`.
| `ask-docs` | Querying the live [CrewAI docs MCP server](https://docs.crewai.com/mcp) for up-to-date API details |
@@ -189,47 +189,76 @@ The true power of CrewAI emerges when combining Crews and Flows. This synergy al
### Getting Started with Installation
To get started with CrewAI, follow these simple steps:
To get started with CrewAI, follow these simple steps. The full walkthrough lives in the [installation guide](https://docs.crewai.com/en/installation).
### 1. Installation
Ensure you have Python >=3.10 <3.14 installed on your system. CrewAI uses [UV](https://docs.astral.sh/uv/) for dependency management and package handling, offering a seamless setup and execution experience.
CrewAI requires `Python >=3.10 and <3.14`. Check your version with:
First, install CrewAI:
```shell
uv pip install crewai
```bash
python3 --version
```
If you want to install the 'crewai' package along with its optional features that include additional tools for agents, you can do so by using the following command:
CrewAI uses [UV](https://docs.astral.sh/uv/) for dependency management and package handling. If you haven't installed `uv` yet, install it first.
**macOS/Linux:**
```shell
uv pip install 'crewai[tools]'
curl -LsSf https://astral.sh/uv/install.sh | sh
```
The command above installs the basic package and also adds extra components which require more dependencies to function.
If your system doesn't have `curl`, you can use `wget`:
### Troubleshooting Dependencies
```shell
wget -qO- https://astral.sh/uv/install.sh | sh
```
If you encounter issues during installation or usage, here are some common solutions:
- If issues persist, use a pre-built wheel: `uv pip install tiktoken --prefer-binary`
If you encounter a `PATH` warning, run:
### 2. Setting Up Your Crew with the YAML Configuration
```shell
uv tool update-shell
```
To create a new CrewAI project, run the following CLI (Command Line Interface) command:
If you encounter the `chroma-hnswlib==0.7.6` build error (`fatal error C1083: Cannot open include file: 'float.h'`) on Windows, install [Visual Studio Build Tools](https://visualstudio.microsoft.com/downloads/) with *Desktop development with C++*.
Verify the install:
```shell
uv tool list
```
You should see something like:
```shell
crewai v0.102.0
- crewai
```
To upgrade the global CLI later:
```shell
uv tool install crewai --upgrade
```
This upgrades the **global `crewai` CLI tool** only. To upgrade the `crewai` version inside a project's virtual environment, see [Upgrading CrewAI in a project](https://docs.crewai.com/en/guides/migration/upgrading-crewai).
### 2. Setting Up Your Crew
`crewai create crew` creates a JSON-first crew project. Agents live in `agents/*.jsonc`, tasks and crew-level settings live in `crew.jsonc`, and `crewai run` loads that JSON definition directly.
```shell
crewai create crew <project_name>
@@ -240,200 +269,126 @@ This command creates a new project folder with the following structure:
```
my_project/
├── .gitignore
├── .env
├── agents/
│ └── researcher.jsonc
├── crew.jsonc
├── knowledge/
├── pyproject.toml
├── README.md
├── .env
└── src/
└── my_project/
├── __init__.py
├── main.py
├── crew.py
├── tools/
│ ├── custom_tool.py
│ └── __init__.py
└── config/
├── agents.yaml
└── tasks.yaml
├── skills/
└── tools/
```
You can now start developing your crew by editing the files in the `src/my_project` folder. The `main.py` file is the entry point of the project, the`crew.py` file is where you define your crew, the `agents.yaml` file is where you define your agents, and the `tasks.yaml` file is where you define your tasks.
If you need the older Python/YAML scaffold with `crew.py`, `config/agents.yaml`, and `config/tasks.yaml`, run:
```shell
crewai create crew <project_name> --classic
```
See [Using Annotations](https://docs.crewai.com/en/learn/using-annotations) for the classic pattern.
#### To customize your project, you can:
- Modify `src/my_project/config/agents.yaml` to define your agents.
- Modify `src/my_project/config/tasks.yaml` to define your tasks.
-Modify `src/my_project/crew.py` to add your own logic, tools, and specific arguments.
-Modify `src/my_project/main.py` to add custom inputs for your agents and tasks.
- Modify `agents/*.jsonc` to define each agent's role, goal, backstory, LLM, tools, and behavior.
- Modify `crew.jsonc` to define tasks, process, and input defaults.
-Add custom tools in `tools/` and reference them as `"custom:<name>"`.
-Add optional knowledge files in `knowledge/` and skill files in `skills/`.
- Add your environment variables into the `.env` file.
Use `{placeholder}` values in agent and task text, then set defaults in `crew.jsonc` under `inputs`. When you run `crewai run`, the CLI prompts for any missing values.
#### Example of a simple crew with a sequential process:
Instantiate your crew:
```shell
crewai create crew latest-ai-development
cd latest_ai_development
```
Modify the files as needed to fit your use case:
Then edit the generated files:
**agents.yaml**
**agents/researcher.jsonc**
```yaml
# src/my_project/config/agents.yaml
researcher:
role:>
{topic} Senior Data Researcher
goal:>
Uncover cutting-edge developments in {topic}
backstory:>
You're a seasoned researcher with a knack for uncovering the latest
developments in {topic}. Known for your ability to find the most relevant
information and present it in a clear and concise manner.
reporting_analyst:
role:>
{topic} Reporting Analyst
goal:>
Create detailed reports based on {topic} data analysis and research findings
backstory:>
You're a meticulous analyst with a keen eye for detail. You're known for
your ability to turn complex data into clear and concise reports, making
it easy for others to understand and act on the information you provide.
```jsonc
{
"role":"{topic} Senior Data Researcher",
"goal":"Uncover cutting-edge developments in {topic}",
"backstory":"You're a seasoned researcher who finds relevant information and presents it clearly.",
"llm":"openai/gpt-4o",
"tools":["SerperDevTool"],
"settings":{
"verbose":true
}
}
```
**tasks.yaml**
**agents/reporting_analyst.jsonc**
````yaml
# src/my_project/config/tasks.yaml
research_task:
description: >
Conduct a thorough research about {topic}
Make sure you find any interesting and relevant information given
the current year is 2026.
expected_output: >
A list with 10 bullet points of the most relevant information about {topic}
agent: researcher
reporting_task:
description: >
Review the context you got and expand each topic into a full section for a report.
Make sure the report is detailed and contains any and all relevant information.
expected_output: >
A fully fledged report with the main topics, each with a full section of information.
Formatted as markdown without '```'
agent: reporting_analyst
output_file: report.md
````
**crew.py**
```python
# src/my_project/crew.py
from crewai import Agent, Crew, Process, Task
from crewai.project import CrewBase, agent, crew, task
from crewai_tools import SerperDevTool
from crewai.agents.agent_builder.base_agent import BaseAgent
from typing import List
@CrewBase
class LatestAiDevelopmentCrew():
"""LatestAiDevelopment crew"""
agents: List[BaseAgent]
tasks: List[Task]
@agent
def researcher(self) -> Agent:
return Agent(
config=self.agents_config['researcher'],
verbose=True,
tools=[SerperDevTool()]
)
@agent
def reporting_analyst(self) -> Agent:
return Agent(
config=self.agents_config['reporting_analyst'],
verbose=True
)
@task
def research_task(self) -> Task:
return Task(
config=self.tasks_config['research_task'],
)
@task
def reporting_task(self) -> Task:
return Task(
config=self.tasks_config['reporting_task'],
output_file='report.md'
)
@crew
def crew(self) -> Crew:
"""Creates the LatestAiDevelopment crew"""
return Crew(
agents=self.agents, # Automatically created by the @agent decorator
tasks=self.tasks, # Automatically created by the @task decorator
process=Process.sequential,
verbose=True,
)
```jsonc
{
"role":"{topic} Reporting Analyst",
"goal":"Create detailed reports based on {topic} data analysis and research findings",
"backstory":"You're a meticulous analyst who turns complex data into clear, concise reports.",
"llm":"openai/gpt-4o",
"settings":{
"verbose":true
}
}
```
**main.py**
**crew.jsonc**
```python
#!/usr/bin/env python
# src/my_project/main.py
import sys
from latest_ai_development.crew import LatestAiDevelopmentCrew
def run():
"""
Run the crew.
"""
inputs = {
'topic': 'AI Agents'
```jsonc
{
"name":"Latest AI Development",
"agents":["researcher","reporting_analyst"],
"tasks":[
{
"name":"research_task",
"description":"Conduct thorough research about {topic}. Find recent, relevant information.",
"expected_output":"A list with 10 bullet points of the most relevant information about {topic}.",
"agent":"researcher"
},
{
"name":"reporting_task",
"description":"Review the research and expand each topic into a full section for a report.",
"expected_output":"A markdown report with the main topics, each with a full section of information. No fenced code blocks around the whole document.",
Before running your crew, make sure you have the following keys set as environment variables in your `.env` file:
Before running your crew, set the required keys in your `.env` file:
- An [OpenAI API key](https://platform.openai.com/account/api-keys) (or other LLM API key): `OPENAI_API_KEY=sk-...`
- A [Serper.dev](https://serper.dev/) API key: `SERPER_API_KEY=YOUR_KEY_HERE`
- Your model provider API key — see [LLM setup](https://docs.crewai.com/en/concepts/llms#setting-up-your-llm)
- A [Serper.dev](https://serper.dev/) API key if you use web search: `SERPER_API_KEY=YOUR_KEY_HERE`
Lock the dependencies and install them by using the CLI command but first, navigate to your project directory:
Then install dependencies and run from the project directory:
```shell
cd my_project
crewai install (Optional)
```
To run your crew, execute the following command in the root of your project:
```bash
crewai install
crewai run
```
or
If you need additional packages, use `uv add <package-name>`.
```bash
python src/my_project/main.py
```
If an error happens due to the usage of poetry, please run the following command to update your crewai package:
```bash
crewai update
```
You should see the output in the console and the `report.md` file should be created in the root of your project with the full final report.
You should see the output in the console, and `output/report.md` should be created in the project root.
In addition to the sequential process, you can use the hierarchical process, which automatically assigns a manager to the defined crew to properly coordinate the planning and execution of tasks through delegation and validation of results. [See more about the processes here](https://docs.crewai.com/en/concepts/processes).
For a Flow-first walkthrough, see the [Quickstart](https://docs.crewai.com/en/quickstart).
## Key Features
CrewAI gives developers a practical foundation for building agentic systems that move from prototype to production: autonomous collaboration where it helps, explicit workflow control where it matters, and Python-native customization throughout.
@@ -701,17 +656,13 @@ A: CrewAI is a lean, fast Python framework built specifically for orchestrating
### Q: How do I install CrewAI?
A: Install CrewAI with [UV](https://docs.astral.sh/uv/):
A: Install the CrewAI CLI with [UV](https://docs.astral.sh/uv/):
```shell
uv pip install crewai
uv tool install crewai
```
For additional tools, use:
```shell
uv pip install 'crewai[tools]'
```
Then create a project with `crewai create crew <project_name>`, run `crewai install`, and start it with `crewai run`. See the [installation guide](https://docs.crewai.com/en/installation) for details.
result = llm.call("Summarize the incident", response_model=Report)
except openai.InternalServerError as e:
# "z-ai/glm-5.3 via openrouter.ai returned HTTP 200 with an upstream error
# and no choices: The operation was aborted (upstream code 504)"
print(f"Upstream provider failed, safe to retry: {e}")
```
<Warning>
إن استخدام `response_model` كبير أو متداخل بعمق يزيد احتمال انتهاء مهلة المزود. تعامل مع هذه الحالات كأعطال مؤقتة في المزود، وليس كإنتاج النموذج مخرجات منظمة تالفة.
داخل مشروع الطاقم تُثبَّت المهارة في `./skills/{name}/`؛ وخارج المشروع تذهب إلى ذاكرة التخزين المؤقتة المشتركة في `~/.crewai/skills/{org}/{name}/`.
<Note>
استخدم **UUID** الخاص بمؤسستك وليس اسمها — فأسماء المؤسسات ليست فريدة، وقد يشير الاسم إلى مؤسسة خاطئة فيفشل التثبيت برسالة "غير موجود". شغّل `crewai org list` لعرض الـ UUID (عمود `ID`) لكل مؤسسة تنتمي إليها.
</Note>
داخل مشروع الطاقم تُثبَّت المهارة في `./skills/{name}/`؛ وخارج المشروع تذهب إلى ذاكرة التخزين المؤقتة المشتركة في `~/.crewai/skills/{org-uuid}/{name}/`.
يمكن للوكلاء أيضًا الإشارة إلى مهارات السجل مباشرة — يتم حلّها من ذاكرة التخزين المؤقتة المحلية (أو من مجلد `skills/` في المشروع) وقت التشغيل:
@@ -217,7 +221,7 @@ agent = Agent(
role="Senior Code Reviewer",
goal="Review pull requests for quality and security issues",
backstory="Staff engineer with expertise in secure coding practices.",
- **معالجة الأخطاء** – توجيه كيفية استجابة الـ Agents للإخفاقات والاستثناءات وحالات انتهاء المهلة.
- **مطالبات خاصة بالأدوات** – تعريف تعليمات مفصلة لكيفية استدعاء الأدوات أو استخدامها.
اطلع على [قوالب المطالبات الأصلية في مستودع CrewAI](https://github.com/crewAIInc/crewAI/blob/main/src/crewai/translations/en.json) لمعرفة كيفية تنظيم هذه العناصر. من هناك، يمكنك تجاوزها أو تكييفها حسب الحاجة لفتح سلوكيات متقدمة.
اطلع على [قوالب المطالبات الأصلية في مستودع CrewAI](https://github.com/crewAIInc/crewAI/blob/main/lib/crewai/src/crewai/translations/en.json) لمعرفة كيفية تنظيم هذه العناصر. من هناك، يمكنك تجاوزها أو تكييفها حسب الحاجة لفتح سلوكيات متقدمة.
استخدم CLI الخاص بـ CrewAI لإنشاء هيكل مشروع، وسيُضاف `AGENTS.md` تلقائيًا في الجذر.
استخدم CLI الخاص بـ CrewAI لإنشاء هيكل مشروع. يُضاف `AGENTS.md` في الجذر، ومعه ملفا `CLAUDE.md` و`GEMINI.md` اللذان يستوردانه، بحيث يقرأ Claude Code وGemini CLI نفس التوجيهات التي يقرأها كل مساعد آخر.
```bash
# Crew
@@ -32,24 +32,28 @@ crewai tool create my_tool
### Claude Code
يخزّن Claude Code ذاكرة المشروع في `CLAUDE.md`. يمكنك تهيئته بـ `/init` وتحريره باستخدام `/memory`. يدعم Claude Code أيضًا الاستيرادات داخل `CLAUDE.md`، فيمكنك إضافة سطر واحد مثل `@AGENTS.md` لسحب التعليمات المشتركة دون تكرارها.
يقرأ Claude Code ملف `CLAUDE.md` ويتجاهل `AGENTS.md`. تأتي المشاريع المُنشأة بملف `CLAUDE.md` تعليمته الوحيدة هي سطر الاستيراد `@AGENTS.md`، بحيث تُحمَّل التوجيهات المشتركة دون تكرارها. أضف الملاحظات الخاصة بـ Claude تحت هذا السطر واحتفظ بالاصطلاحات المشتركة في `AGENTS.md`.
يمكنك ببساطة استخدام:
لمشروع أُنشئ قبل أن يُضاف `CLAUDE.md` إلى الهيكل، أضف الاستيراد بنفسك:
```bash
mv AGENTS.md CLAUDE.md
printf '@AGENTS.md\n' > CLAUDE.md
```
لا تُعِد تسمية `AGENTS.md` إلى `CLAUDE.md`: يقرأ Codex وCursor ملف `AGENTS.md`، وإعادة التسمية تخفيه عنهما.
### Gemini CLI وGoogle Antigravity
يقوم Gemini CLI وAntigravity بتحميل ملف سياق المشروع (الافتراضي: `GEMINI.md`) من جذر المستودع والمجلدات الأصلية. يمكنك تهيئته لقراءة `AGENTS.md` بدلاً من ذلك (أو بالإضافة إليه) بتعيين `context.fileName` في إعدادات Gemini CLI. على سبيل المثال، عيّنه إلى `AGENTS.md` فقط، أو أدرج كلاً من `AGENTS.md` و`GEMINI.md` إذا أردت الاحتفاظ بتنسيق كل أداة.
يقوم Gemini CLI وAntigravity بتحميل ملف سياق المشروع (الافتراضي: `GEMINI.md`) من جذر المستودع والمجلدات الأصلية. تأتي المشاريع المُنشأة بملف `GEMINI.md` تعليمته الوحيدة هي سطر الاستيراد `@./AGENTS.md`، بحيث تُحمَّل التوجيهات المشتركة دون تكرارها. أضف الملاحظات الخاصة بـ Gemini تحت هذا السطر واحتفظ بالاصطلاحات المشتركة في `AGENTS.md`.
يمكنك ببساطة استخدام:
لمشروع أُنشئ قبل أن يُضاف `GEMINI.md` إلى الهيكل، أضف الاستيراد بنفسك:
```bash
mv AGENTS.md GEMINI.md
printf '@./AGENTS.md\n' > GEMINI.md
```
بدلاً من ذلك، عيّن `context.fileName` في إعدادات Gemini CLI ليشمل `AGENTS.md` فيقرأه Gemini مباشرة. لا تُعِد تسمية `AGENTS.md` إلى `GEMINI.md`: يقرأ Codex وCursor ملف `AGENTS.md`، وإعادة التسمية تخفيه عنهما.
### Cursor
يدعم Cursor ملف `AGENTS.md` كملف تعليمات مشروع. ضعه في جذر المشروع لتوفير توجيهات لمساعد البرمجة في Cursor.
description: أنشئ تطبيقات دردشة متعددة الجولات مع kickoff لكل جولة وسجل الرسائل وتوجيه النية والتتبع وجسور WebSocket.
description: أنشئ تطبيقات دردشة متعددة الجولات باستخدام handle_turn لكل جولة، وسجل الرسائل، وتوجيه النية، والتتبع، والبث المنظّم.
icon: comments
mode: "wide"
---
## نظرة عامة
تعامل التطبيقات المحادثية مع كل سطر من المستخدم كـ **تشغيل flow جديد** بنفس **معرّف الجلسة**. توفر CrewAI مساعدات لسجل الرسائل وتصنيف النية الاختياري وتأجيل التتبع وجسور الواجهة، إضافة إلى REPL محلي `flow.chat()` للتدفقات المحادثية.
تعامل التطبيقات المحادثية مع كل سطر من المستخدم كـ **تشغيل flow جديد** بنفس **معرّف الجلسة**. توفر CrewAI مساعدات لسجل الرسائل، وتوجيه النية الاختياري، وتأجيل التتبع، والبث المنظّم للجولات، إضافة إلى REPL محلي عبر `flow.chat()`.
| تتبع الجلسة الكامل | `ConversationConfig(defer_trace_finalization=True)` + `finalize_session_traces()` |
## واجهات الجولات
استخدم **`flow.handle_turn(message, session_id=...)`** لكل رسالة مستخدم من REST أو WebSocket أو الاختبارات أو الواجهات المخصصة. استخدم **`flow.chat()`** عندما تريد حلقة دردشة محلية في الطرفية لـ `Flow` محادثي.
لا يقبل `Flow.kickoff()` الوسيطين `user_message=` أو `session_id=`. في التدفقات المحادثية، يخزن `handle_turn()` الرسالة المعلقة ويستدعي داخلياً `kickoff(inputs={"id": session_id})`.
لا يقبل `Flow.kickoff()` الوسيطين `user_message=` أو `session_id=`. في التدفقات المحادثية، يخزن `handle_turn()` الرسالة المعلقة ويستدعي داخلياً `kickoff(inputs={"id": session_id})` بعد إعادة ضبط حالة التنفيذ الخاصة بالجولة.
| API | الاستخدام |
|-----|-----------|
| `handle_turn(message, session_id=...)` | غلاف مريح لجولة واحدة في `Flow` محادثي |
| `chat()` | REPL محلي في الطرفية لـ `Flow` محادثي |
| `kickoff(inputs={...})` | تشغيل متقدم للـ flow بدون معالجة جولة محادثية |
| `ask()` | مطالبة حاجزة **داخل** خطوة واحدة |
| `ask()` | مطالبة حاجزة **داخل** خطوة واحدة (معالج إرشادي أو طلب توضيح) |
| `@human_feedback` | الموافقة/الرفض على **مخرجات خطوة** — وليس السطر التالي |
| `ChatSession.handle_turn(...)` | طبقة نقل فوق `handle_turn` |
ترفع `handle_turn()` و`stream_turn()` و`chat()` الخطأ `ValueError` ما لم يكن الوضع المحادثاتي مفعّلاً. يؤدي تطبيق `@ConversationConfig(...)` إلى تفعيله تلقائياً؛ وإلا فعيّن `conversational = True`.
## بداية سريعة
@@ -38,7 +40,7 @@ from uuid import uuid4
from crewai import Flow
from crewai.flow import listen
from crewai.experimental.conversational import (
from crewai.flow import (
ConversationConfig,
ConversationState,
)
@@ -46,31 +48,29 @@ from crewai.experimental.conversational import (
flow.handle_turn("وماذا عن الإرجاع؟", session_id=session_id)
flow.handle_turn("Where is my order?", session_id=session_id)
flow.handle_turn("What about returns?", session_id=session_id)
finally:
flow.finalize_session_traces()
flow.finalize_session_traces() # one trace link for the whole chat
```
## بث جولة
استخدم `stream_turn()` عندما تحتاج واجهة مستخدم أو بيئة تشغيل إلى أحداث منظّمة لجولة دردشة واحدة. يعيد جلسة بث تحتوي على إطارات مرتبة لتوجيه Flow، وأجزاء LLM، ونشاط الأدوات، ورسائل المحادثة.
```python
stream = flow.stream_turn("Where is my order?", session_id=session_id)
with stream:
for frame in stream.events:
if frame.channel == "llm" and frame.type == "llm_stream_chunk":
print(frame.content, end="", flush=True)
result = stream.result
```
راجع [عقد بيئة البث](/edge/ar/learn/streaming-runtime-contract) للاطلاع على عقد الإطارات الكامل وقائمة القنوات.
6. **نهاية التشغيل** — يُتخطى `flow_finished` والتتبع لكل جولة عند التأجيل؛ `Agent.kickoff()` / crews لا تغلق دفعة الأب.
4. **ترطيب الجولة المعلقة** — تُضاف رسالة المستخدم إلى `state.messages`، وتُضبط `current_user_message` / `last_user_message`، ويُجرى التصنيف اختيارياً عند ضبط `intents` / `default_intents` مع `intent_llm`.
5. **تنفيذ الرسم** — طرق `@start` التي يعرّفها المستخدم (إن وجدت) → `route_conversation` (نقطة البدء/الموجّه المدمجة) → معالج `@listen` المختار. تستدعي `route_conversation` أيضاً المساعد القابل للتجاوز `conversation_start()`.
6. **نهاية التشغيل** — يُتخطى `flow_finished` لكل جولة وإنهاء التتبع عند تفعيل التأجيل؛ كما لا تغلق استدعاءات `Agent.kickoff()` المتداخلة أو crews دفعة الأب.
استدعِ **`append_assistant_message(reply)`** في المعالجات. سطر المستخدم محفوظ عبر `handle_turn` — لا تُضفه مرة أخرى.
استدعِ **`append_assistant_message(reply)`** عندما لا تطابق الرد الظاهر قيمة الإرجاع، أو عند قصّ التاريخ. تُسجَّل أيضاً سلسلة الإرجاع العامة كمساعد وتُضمَّن في لقطة `@persist`، فتستعيدها نسخة Flow جديدة. سطر المستخدم محفوظ عبر `handle_turn` — لا تُضفه مرة أخرى.
## `ConversationalConfig` (افتراضيات على مستوى الصنف)
## نظرة عامة على الإعداد
عيّن على صنف `Flow` كـ `conversational_config: ClassVar[ConversationalConfig | None]`.
يؤدي تزيين صنف فرعي من `Flow` بـ `ConversationConfig` إلى إرفاق افتراضيات الدردشة وتفعيل الوضع المحادثاتي معاً. راجع [مرجع الحقول الكامل](#conversationconfig) أدناه. ويمكنك تجاوز التصنيف المسبق لكل جولة عبر `handle_turn(..., intents=..., intent_llm=...)`.
| `interactive_timeout` | `None` | مهلة لكل سطر في الوضع التفاعلي |
| `exit_commands` | `exit`, `quit` | كلمات إنهاء الوضع التفاعلي |
| `defer_trace_finalization` | `True` | إبقاء دفعة trace واحدة مفتوحة بين الجولات |
## مساعدات `ChatState` منخفضة المستوى
يمكن التجاوز لكل kickoff عبر `intents=` و`intent_llm=`.
## `ChatState` (شكل الحالة الموصى به للحفظ)
تظل `ChatState` و`ConversationalConfig` القديمة ومساعدات `crewai.flow.conversation` قابلة للاستيراد للتنسيق المتقدم أو الاختبارات أو الأغلفة المخصصة. وهي منفصلة عن واجهتي `ConversationState` / `ConversationConfig`، ولا تضيف وسيطي `user_message=` أو `session_id=` إلى `Flow.kickoff()`.
| `id` | UUID الجلسة (مثل `session_id` / `inputs["id"]`) |
| `messages` | قائمة `{role, content}` لسجل LLM |
| `id` | UUID الجلسة (نفس `inputs["id"]`) |
| `messages` | `list` من `{role, content}` لسجل LLM |
| `last_user_message` | آخر سطر مستخدم في هذه الجولة |
| `last_intent` | تسمية المسار بعد التصنيف (إن وُجد) |
| `session_ready` | علم bootstrap لمرة واحدة |
| `session_ready` | علم bootstrap لمرة واحدة (الصلاحيات، وذاكرات التخزين المؤقت، وغيرها) |
`ConversationalInputs` هو `TypedDict` لـ `kickoff(inputs={...})`: `id`, `user_message`, `last_intent`.
`ConversationalInputs` هو `TypedDict` لمفاتيح `kickoff(inputs={...})` الاصطلاحية: `id` و`user_message` و`last_intent`.
تخزن `ConversationState` رسائل `messages` ككائنات `ConversationMessage`، وتوفر أيضاً `current_user_message` و`ended` و`events` و`agent_threads`. استخدم `conversation_messages` عند تمرير سجلها القانوني إلى LLM.
## API المحادثة على `Flow`
### معاملات `kickoff` / `kickoff_async`
### معاملات `handle_turn`
| المعامل | الغرض |
|---------|--------|
| `user_message` | نص هذه الجولة (أو `{"role": "user", "content": "..."}`) |
| `intents` | تسميات outcome لـ `classify_intent` قبل kickoff |
| `intents` | تسميات النتائج لـ `classify_intent` قبل kickoff |
| `intent_llm` | LLM للتصنيف (مطلوب مع `intents`) |
| `interactive` | حلقة CLI عبر `ask()` (للعروض المحلية فقط) |
| `interactive_prompt` | مطالبة الوضع التفاعلي |
| `interactive_timeout` | مهلة `ask()` لكل سطر |
| `exit_commands` | كلمات إنهاء الوضع التفاعلي |
| `inputs` | حقول حالة إضافية |
| `restore_from_state_id` | استنساخ من flow محفوظ آخر |
| `**kickoff_kwargs` | تُمرر إلى `kickoff()` لخيارات مثل `input_files` و`from_checkpoint` و`restore_from_state_id` |
### معاملات `kickoff`
يقبل `Flow.kickoff()` كلاً من `inputs` و`input_files` و`from_checkpoint` و`restore_from_state_id`. مرر `inputs={"id": session_id}` عندما تحتاج إلى تنفيذ flow خام، لكن استخدم `handle_turn()` عندما يمثل الاستدعاء رسالة دردشة.
### سمات المثيل
| السمة | الغرض |
|-------|--------|
| `conversational_config` | افتراضيات `ConversationalConfig` على مستوى الصنف |
| `defer_trace_finalization` | علم المثيل؛ يُضبط تلقائياً من config عند kickoff |
| `defer_trace_finalization` | تجاوز اختياري على مستوى المثيل. وإلا تقرأ `_should_defer_trace_finalization()` القيمة `ConversationConfig.defer_trace_finalization`. |
| `suppress_flow_events` | يخفي لوحات flow في الطرفية ويمنع أحداث تنفيذ الطرق؛ وتظل أحداث بدء/انتهاء flow تصدر |
| `stream` | علم البث العام لـ Flow. استخدم `stream_turn()` للجولات المحادثية بدلاً من جمع هذا العلم مع `handle_turn()`. |
### طرق وخصائص
| الاسم | الوصف |
|------|--------|
| `append_assistant_message(content)` | إضافة رد مساعد مرئي للمستخدم إلى `state.messages` |
| `append_message(role, content, **extra)` | إضافة إلى `state.messages` |
| `conversation_messages` | سجل للقراءة فقط لاستدعاءات LLM |
| `classify_intent(text, outcomes, *, llm, context=None)` | تعيين outcome |
| `receive_user_message(text, *, outcomes=None, llm=None)` | إضافة رسالة مستخدم؛ `last_intent` اختياري |
| `classify_intent(text, outcomes, *, llm, context=None)` | تعيين النص إلى نتيجة واحدة (بنفس منطق الاختزال المستخدم في `@human_feedback`) |
| `receive_user_message(text, *, outcomes=None, llm=None)` | إضافة رسالة مستخدم، وضبط `last_intent` اختيارياً |
| `finalize_session_traces()` | إصدار `flow_finished` المؤجل وإنهاء دفعة trace |
| `_should_defer_trace_finalization()` | هل يُؤجل إنهاء trace لكل جولة |
| `_should_defer_trace_finalization()` | hook متقدم/داخلي يحسم ما إذا كان إنهاء trace لكل جولة مؤجلاً |
| `input_history` | سجل تدقيق مطالبات وردود `ask()` |
### مساعدات الوحدة (`crewai.flow.conversation`)
يمكن استيرادها من `crewai.flow.conversation` للاختبارات أو التنسيق المخصص. تستخدم هذه المساعدات بنية `ConversationalConfig` القديمة؛ كما تمسح `prepare_conversational_turn()` قيمة `last_intent`، بخلاف `handle_turn()` التي تحتفظ بها كسياق للموجّه.
| الدالة | الوصف |
|--------|--------|
| `normalize_kickoff_inputs(...)` | دمج kwargs المحادثة في `inputs` |
| `receive_user_message(flow, text, ...)` | مثل طريقة المثيل |
| `set_state_field(flow, name, value)` | تعيين حقل dict أو Pydantic |
| `get_conversational_config(flow)` | قراءة `conversational_config` |
| `input_history_to_messages(entries)` | تحويل `input_history` لصيغة رسائل LLM |
## أنماط توجيه النية
### أ. تصنيف مسبق عبر `ConversationalConfig` (الأبسط)
### أ. تصنيف مسبق عبر `ConversationConfig` (الأبسط)
عيّن `default_intents` و`intent_llm`. كل kickoff يصنّف قبل `@router`؛ اقرأ `self.state.last_intent` في `route()`.
عيّن `default_intents` و`intent_llm`. يصنّف كل `handle_turn()` الرسالة الحالية مسبقاً. تكون الأولوية لنتيجة غير فارغة يعيدها `route_turn()` مخصص؛ وإلا تستخدم `route_conversation` النية المصنّفة للجولة الحالية.
### ب. تصنيف داخل `@router` (مطالبات أغنى)
### ب. تصنيف داخل `route_turn` (مطالبات أغنى)
عيّن `default_intents=None` ليضيف kickoff الرسالة فقط. في `route()` استدعِ `classify_intent`:
عيّن `default_intents=None` كي يضيف `handle_turn()` رسالة المستخدم فقط. داخل `route_turn()`، استدعِ `classify_intent` بمطالبة أو أوصاف مخصصة:
llm=self.conversational_config.intent_llm or "gpt-4o-mini",
llm="gpt-4o-mini",
)
self.state.last_intent = intent
return intent
@@ -212,70 +223,59 @@ def route(self):
## عندما ينتهي الـ flow ويستمر المستخدم
`FlowFinished` يعني أن **تنفيذ الرسم هذا** اكتمل. تستمر المحادثة بـ `kickoff` آخر ونفس `session_id`. `@persist` يستعيد `messages` والأعلام والسياق.
يُكمل كل `handle_turn()` تشغيل رسم واحد، وتستمر المحادثة عبر `handle_turn()` آخر يستخدم `session_id` نفسه. مع دورة حياة التتبع المؤجلة افتراضياً، يصدر ذلك التشغيل `conversation_turn_completed`، بينما يصدر `FlowFinished` مرة واحدة عندما تغلق `finalize_session_traces()` الجلسة. ويستعيد `@persist` الرسائل والأعلام والسياق.
**نمط الحفظ:** يُفضّل `@persist` على **خطوة نهائية واحدة** (مثل `finalize`) وليس على صنف `Flow` بالكامل. الحفظ على مستوى الصنف بعد كل method قد يفقد تحديثات المعالجات في نفس الجولة.
**نمط الحفظ:** يُفضّل `@persist` على **خطوة نهائية واحدة** (مثل `finalize`) وليس على صنف `Flow` بالكامل. يحفظ الاستمرار على مستوى الصنف بعد كل طريقة؛ وتستخدم `load_state` أحدث صف، وقد يكون لقطة في منتصف التشغيل (مثلاً بعد `bootstrap` مباشرة) لا تتضمن تحديثات المعالج من الجولة نفسها.
لا تستخدم `@human_feedback` لأسطر المتابعة في الدردشة إلا عند الحاجة لموافقة بشرية على مخرجات خطوة محددة.
## `Flow` المحادثاتي (تجريبي)
## `Flow` المحادثاتي
<Warning>
**ميزة تجريبية.** سطح `Flow` المحادثاتي (`conversational = True`،
`ConversationState`، الرسم البياني المدمج والمساعدات) يقع تحت
`crewai.experimental` وقد يتغير شكله قبل التخرج. ثبّت إصدار CrewAI إذا
كنت تعتمد على سلوك محدد، وراقب changelog للتحديثات الكاسرة. الملاحظات
والمشاكل مرحب بها.
</Warning>
فعّل الرسم المحادثاتي بتعيين `conversational = True` على صنف فرعي من `Flow`. عندئذٍ يُظهر `Flow` الأساسي رسم `@start` / `@router` / `converse_turn` / `end_conversation` مدمجاً، ويدير `state.messages`، ويُشغّل LLM التوجيه، ويبقي دفعة trace مفتوحة عبر الجولات. أنت تكتب **المسارات المخصصة** فقط؛ والإطار يتولى الباقي.
اشترك في رسم الدردشة المحادثاتي بتعيين `conversational = True` على صنف فرعي من `Flow` أو بتطبيق `@ConversationConfig(...)`. يوفر `Flow` الأساسي عندئذٍ `route_conversation` كنقطة البدء/الموجّه المدمجة، إضافة إلى مستمعي `converse_turn` و`end_conversation`. يظل المستمع المهمل `answer_from_history_turn` متاحاً للتوافق. يدير الإطار `state.messages`، ويمكنه تشغيل LLM للموجّه، ويبقي دفعة trace مفتوحة عبر الجولات. أنت تكتب **المسارات المخصصة**؛ والإطار يتولى الباقي.
استخدمه عندما تريد دردشة متعددة الجولات مع موجّه قائم على LLM ومعالجات لكل مسار دون توصيل دورة الحياة يدوياً. استخدم `Flow[ChatState]` (النمط الأدنى مستوى في الأعلى) عندما تحتاج تحكماً كاملاً.
### مثال سريع
```python
from crewai import LLM, Flow
from crewai import Flow
from crewai.flow import listen
from crewai.experimental.conversational import (
from crewai.flow import (
ConversationConfig,
ConversationState,
RouterConfig,
)
ROUTER_LLM = LLM(model="gpt-4o-mini")
@ConversationConfig(
system_prompt="A multi-agent assistant for ordinary chat and tool-backed tasks.",
llm=ROUTER_LLM,
router=RouterConfig(), # المسارات + الأوصاف تُكتشف تلقائياً من معالجات @listen
ويجري تجاوزها عندما يعيد الموجّه التلقائي المعتاد مساراً. تظل الإعدادات
الحالية تعمل وتُصدر `DeprecationWarning`.
</Warning>
عند عدم وجود مسارات مخصصة، تسقط الجولات إلى `converse`. ومع وجود مسارات مخصصة وLLM للمحادثة/الموجّه، ينشئ الإطار `RouterConfig` افتراضية؛ لا توفر واحدة صراحةً إلا لتخصيص المطالبة أو قائمة المسارات أو الأوصاف أو سلوك fallback. أما ضبط `default_intents` فيستخدم مسار التصنيف المسبق القديم.
إذا لم يُهيأ LLM للمحادثة، يعيد `converse_turn` المدمج عنصراً نائباً للإعداد بدلاً من توليد إجابة.
2. `Flow.builtin_route_descriptions[label]` — نص جاهز من الإطار لـ `converse` و`end` و`answer_from_history` (مصاغ لـ LLM التوجيه).
3. أول سطر غير فارغ من docstring معالج `@listen(label)`.
4. فارغ (المسار يظهر في الفهرس بلا وصف).
2. `Flow.builtin_route_descriptions[label]` — نص جاهز من الإطار لـ `converse` و`end` ولمسار التوافق المهمل `answer_from_history` (مصاغ لـ LLM التوجيه).
3. قيمة `description` المعلنة للطريقة (تستخدمها التدفقات التعريفية وإسقاطات DSL).
4. أول سطر غير فارغ من docstring معالج `@listen(label)`.
5. فارغ (المسار يظهر في الفهرس بلا وصف).
عملياً، **إضافة مسار جديد = `@listen("X")` + docstring من سطر واحد**:
```python
from crewai.flow import listen
@listen("INTERNET_SEARCH")
def handle_internet_search(self) -> str:
"""Fresh web research, current news, real-time lookups."""
@@ -350,13 +381,34 @@ Routes:
`RouterConfig.prompt` مخصص لـ **تأطير النطاق** (شخصية المساعد، قواعد العمل، النبرة). فهرس المسارات يُبنى تلقائياً — لا تُدرج المسارات في `prompt`؛ سيختل التزامن لحظة إضافة معالج جديد.
### تسمية المعالجات
السلسلة النصية في `@listen("…")` هي **تسمية مسار للموجّه** (اسم حدث)، وليست اسم طريقة Python. تتشارك تسميات المسارات وأحداث اكتمال الطرق مساحة مشغلات واحدة، ولذلك تؤدي تسمية المعالج باسم مساره نفسه إلى إعادة تشغيل المعالج في حلقة.
استخدم اسماً مختلفاً للطريقة — تستخدم أمثلة التوثيق بادئة `handle_*`:
```python
@listen("create_video")
def handle_create_video(self) -> str:
"""User wants a new video."""
...
```
لا تكرر تسمية المسار في اسم الطريقة:
```python
@listen("create_video")
def create_video(self) -> str: # rejected at flow instantiation
...
```
### المسارات المدمجة
| المسار | المعالج | الغرض |
|--------|---------|-------|
| `converse` | `converse_turn` | معالج الدردشة الافتراضي. يستدعي `ConversationConfig.llm` بـ system prompt + التاريخ القانوني للرسائل. |
| `answer_from_history` | `answer_from_history_turn` | اختياري. يُوجَّه إليه عندما يكون `ConversationConfig.answer_from_history_llm` مُعيَّناً ويمكن الإجابة على الرسالة من التاريخ فقط. |
| `answer_from_history` | `answer_from_history_turn` | **مسار توافق مهمل.** استخدم `converse`، الذي يتلقى السجل القانوني بالفعل. |
يمكنك تجاوز أي من هذه بتعريف معالج بنفس الاسم في الصنف الفرعي.
@@ -366,9 +418,9 @@ Routes:
1. يعيد ضبط تعقّب التنفيذ لكل جولة (`_completed_methods`, `_method_outputs`) ليُعاد تشغيل الرسم — بدون ذلك، استدعاءات `kickoff` المتكررة على نفس النسخة ستُحدث دائرة قصر من الجولة الثانية لأن `Flow.kickoff_async` يعتبر `inputs={"id": ...}` استعادة من نقطة تفتيش.
2. يُلحق رسالة المستخدم بـ `state.messages` ويضبط `current_user_message` / `last_user_message`. يُحافَظ على `last_intent` **من الجولة السابقة** كي يستخدمها LLM التوجيه كإشارة.
3. يُشغّل طرق `@start` التي يعرّفها المستخدم (إن وجدت)، ثم `route_conversation` كنقطة البدء/الموجّه المدمجة، ثم معالج `@listen` المختار. وتستدعي `route_conversation` المساعد القابل للتجاوز `conversation_start()`.
4. يخزّن الموجّه قراره في `state.last_intent` (يكون مرئياً لسياق التوجيه في الجولة التالية).
5. إذا أعاد معالجك سلسلة نصية ولم يستدعِ `append_assistant_message`، فإن `handle_turn` يُلحقها نيابةً عنك.
5. إذا أعاد معالجك سلسلة نصية ولم يستدعِ `append_assistant_message`، فإن `handle_turn` يُلحقها نيابةً عنك ويحفظ `state.messages` المحدَّث حتى تشمل استعادة `@persist` جولة المساعد.
5. ينهي traces الجلسة المؤجلة داخل كتلة `finally`.
يُفعّل `chat(defer_trace_finalization=True)` مؤقتاً علم التأجيل على مستوى المثيل للـ REPL، ثم يعيد قيمته السابقة عند الخروج.
خصص سلوك الطرفية عبر I/O قابل للحقن:
```python
@@ -407,6 +461,12 @@ flow.chat(
لتشغيل آثار جانبية (إعداد ناقل أحداث، قياس عن بُعد) في كل قرار توجيه، تجاوز `route_turn`:
```python
from typing import Any
from crewai import Flow
from crewai.flow import ConversationState
class SupportFlow(Flow[ConversationState]):
conversational = True
@@ -415,7 +475,7 @@ class SupportFlow(Flow[ConversationState]):
return super().route_turn(context)
```
لتجاوز موجّه LLM واختيار مسار برمجياً، أعد سلسلة نصية من `route_turn`؛ إعادة `None` تسقط إلى `_route_with_config(...)`.
لتجاوز موجّه LLM بالكامل واختيار مسار برمجياً، أعد سلسلة نصية غير فارغة من `route_turn`. لا يؤدي إرجاع قيمة falsy من التجاوز إلى استدعاء `_route_with_config()`؛ بل يسقط التوجيه إلى النية المصنّفة مسبقاً لهذه الجولة، ثم إلى مسار التوافق المهمل `answer_from_history` عند إعداده، وأخيراً إلى `converse`. تكون `last_intent` من الجولة السابقة متاحة في سياق الموجّه، لكنها لا تُعاد أبداً كـ fallback.
@@ -426,9 +486,76 @@ class SupportFlow(Flow[ConversationState]):
يمكن لـ `ConversationConfig.visible_agent_outputs` رفع النتائج الخاصة لـ agents محددين إلى عامة عالمياً (`"all"` أو قائمة بالأسماء).
## تعريف تدفق محادثاتي بصيغة JSON/YAML
يمكن لـ [التدفق التعريفي](/edge/ar/concepts/cli) أن يكون محادثاتيًا أيضًا. أضف كتلة `conversational` في المستوى الأعلى وعرّف مساراتك الخاصة كطرق تستمع (`listen`) إلى تسمية مسار:
```yaml
schema: crewai.flow/v1
name: SupportFlow
conversational:
system_prompt: You are a terse support assistant.
llm: gpt-4o-mini
router:
llm: gpt-4o-mini
methods:
handle_order:
description: Order status, shipping and delivery questions.
listen: order
do:
call: agent
with:
role: Support specialist
goal: Answer order questions accurately
backstory: Knows the fulfilment pipeline.
input: "${state.current_user_message}"
```
تعريف الكتلة هو الاشتراك نفسه — القيمة الافتراضية لـ `enabled` هي `true`. اضبطها على `enabled: false` للاحتفاظ بالإعدادات مع إيقاف المحادثة. يؤدي ذلك أيضاً إلى تعطيل إنشاء الطرق المدمجة، ولذلك يجب أن توفر التعريفة رسماً عادياً غير محادثاتي.
تُوفَّر لك ثلاثة أشياء:
| المُوفَّر | التفاصيل |
|----------|--------|
| الرسم البياني المدمج | تُضاف `route_conversation` و`converse_turn` و`end_conversation` تلقائيًا. يُحتفظ بـ `answer_from_history_turn` المهملة للتوافق. عرّف طريقة بأحد هذه الأسماء لتجاوزها. |
| حالة المحادثة | تُستخدم `ConversationState` عند عدم وجود كتلة `state`. وتُركّب حالة Pydantic ذات `ref` أو `json_schema` تلقائياً مع الحقول المحادثية؛ ولا يلزم أن ترث من `ConversationState`. |
| كتالوج المسارات | يُستنتج من الطرق غير الموجّهة التي تحمل تسميات `listen`، مع استبعاد المسارات الداخلية. تتبع الأوصاف ترتيب الأولوية أعلاه، ويمكن لـ `router.routes` الصريحة تقييد الخيارات. |
تقبل حقول `llm` و`router.llm` و`intent_llm` التعريفية إما معرّف نموذج أو خريطة إعدادات مثل `{model: openai/gpt-4o-mini, max_tokens: 512}`. وتدعم كتلة `conversational` أيضاً `default_intents` و`visible_agent_outputs` و`defer_trace_finalization` وحقول `RouterConfig` الموضحة أعلاه. تظل تعريفات `answer_from_history_prompt` / `answer_from_history_llm` المهملة مقبولة للتوافق.
شغّله من Python بنفس واجهات الجولة المستخدمة مع تدفق محادثاتي معرّف بصنف:
```python
from crewai.flow import Flow
flow = Flow.from_declaration(path="flow.yaml")
try:
flow.handle_turn("Where is my order?", session_id="session-1")
finally:
flow.finalize_session_traces()
```
### تسمية المسارات
تتشارك تسميات المسارات وأسماء الطرق مساحة اسم واحدة للمشغّلات، لذا يجب ألا يحمل المعالج اسم المسار الذي يستمع إليه — يُرفض `create_video` الذي يستمع إلى `create_video` عند بناء التدفق. استخدم بادئة `handle_*`.
### ما لا يمكن للتعريفة التعبير عنه
| غير قابل للتعبير | استخدم بدلًا منه |
|-----------------|-------------|
| مثيل `LLM` حي أو `BaseLLM` مخصص | سلسلة معرّف نموذج أو خريطة إعدادات ثابتة |
| تجاوز `route_turn()` | اكتب Flow بلغة Python، أو استبدل طريقة `route_conversation` التعريفية بإجراء `call: code` / expression |
| تجاوز `can_answer_from_history()` | مهمل. استخدم `converse` أو تجاوز `converse_turn()` في Python. |
يفتح `crewai run` واجهة المحادثة النصية للتدفق المحادثاتي التعريفي — نفس الواجهة التي يحصل عليها Flow محادثاتي مكتوب بلغة Python. تحتاج حلقة المحادثة إلى طرفية، ولذلك يخرج التشغيل بدون طرفية برمز غير صفري مع إرشادات بدلاً من تنفيذ جولة واحدة؛ شغّله من Python هناك عبر `handle_turn()` أو `stream_turn()`. وتعمل الطريقة التعريفية ذات كتلة `human_feedback:` (وفي Python: `@human_feedback`) على REPL طرفي، لأن runtime يجمع الملاحظات بمطالبة حاجزة لا تستطيع TUI خدمتها. لا يُقبل `--inputs` مع Flow محادثاتي — فمدخل كل جولة هو الرسالة التي تكتبها — واستئناف جلسة حسب المعرّف غير موصول بواجهة CLI بعد؛ استخدم `flow.handle_turn(message, session_id=...)` من Python لذلك.
## التتبع عبر الجولات
مع `defer_trace_finalization=True` (افتراضي في `ConversationalConfig`):
مع `defer_trace_finalization=True` (افتراضي في `ConversationConfig`):
- **دفعة trace واحدة** لجلسة الدردشة.
- **`flow_started`** في الجولة الأولى فقط؛ **`flow_finished`** مرة في `finalize_session_traces()`.
@@ -439,17 +566,30 @@ class SupportFlow(Flow[ConversationState]):
flow.chat(session_id=session_id)
```
`flow.chat()` يستدعي `finalize_session_traces()` نيابةً عنك. عندما تملك الحلقة عبر `handle_turn()` أو `kickoff(...)`، استدعِ `finalize_session_traces()` عند انتهاء الجلسة.
`flow.chat()` يستدعي `finalize_session_traces()` نيابةً عنك. عندما تملك الحلقة عبر `handle_turn()`، استدعِ `finalize_session_traces()` عند انتهاء الجلسة.
`suppress_flow_events=True` يخفي لوحات Rich فقط؛ أحداث trace والـ methods تُصدر.
يخفي `suppress_flow_events=True` لوحات Rich ويمنع أحداث تنفيذ الطرق. وتظل أحداث بدء/انتهاء Flow تصدر، فيبقى بالإمكان تتبع دورة حياة Flow الخارجية، بينما تُحذف spans الطرق الفردية.
### دورة حياة trace لـ `Flow` المحادثاتي
يستخدم [`Flow` المحادثاتي](#flow-المحادثاتي-تجريبي) التجريبي نفس دورة حياة tracing: `defer_trace_finalization` افتراضياً `True`، فيبقي كل `handle_turn()` أثر الجلسة مفتوحاً. أنهِ دوماً عند نهاية الجلسة — لُف حلقتك بـ `try/finally` واستدعِ `flow.finalize_session_traces()` عند الخروج. بدون ذلك، تبقى الدفعة مفتوحة وقد لا تُصدَّر آخر محادثة أبداً.
يستخدم [`Flow` المحادثاتي](#flow-المحادثاتي) دورة حياة التتبع نفسها: القيمة الافتراضية لـ `defer_trace_finalization` هي `True`، ولذلك يبقي كل `handle_turn()` trace الجلسة مفتوحاً. تمنع الجولات المؤجلة أيضاً إصدار `flow_failed` لكل جولة؛ وعند حدوث خطأ في جولة أو إلغاء الجلسة، أنهِ الجلسة صراحةً. يغلق ذلك الدفعة بحدث `FlowFinished` على مستوى الجلسة بدلاً من حدث `FlowFailed` لكل جولة. لُف REPL/الحلقة دائماً بـ `try/finally` واستدعِ `flow.finalize_session_traces()` عند الخروج. بدون ذلك، تبقى دفعة trace مفتوحة وقد لا تُصدَّر المحادثة النهائية أبداً.
## البث
اضبط `stream = True` على صنف `Flow`. عندئذٍ يُصدر `kickoff(...)` أحداث `assistant_delta` (وما يرتبط بها) عبر ناقل الأحداث القياسي.
استخدم `stream_turn()` للواجهات المحادثية، وكرّر عبر كائنات `StreamFrame` المرتبة التي يعيدها:
```python
stream = flow.stream_turn("Where is my order?", session_id=session_id)
with stream:
for frame in stream.events:
if frame.channel == "llm" and frame.type == "llm_stream_chunk":
print(frame.content, end="", flush=True)
reply = stream.result
```
بالنسبة إلى Flow غير محادثاتي، يؤدي ضبط `stream = True` إلى جعل `kickoff()` يعيد `StreamSession`. لا تضبط `flow.stream = True` عند استخدام `handle_turn()`؛ إذ تملك `stream_turn()` دورة حياة البث المحادثاتي.
## الاستيراد
@@ -464,10 +604,15 @@ from crewai.flow import (
router,
start,
)
from crewai.flow.conversation import prepare_conversational_turn
from crewai.flow import (
ConversationConfig,
ConversationState,
RouterConfig,
)
```
## مراجع
- [إتقان إدارة حالة Flow](/ar/guides/flows/mastering-flow-state)
- [أنشئ أول Flow](/ar/guides/flows/first-flow)
- Demo: `lib/crewai/runner_conversational_flow_simple.py` — REPL بسيط مع `RESEARCH` ووكيل Exa
description: شغّل نفس وكيل CrewAI كروبوت على Slack أو Teams باستخدام CopilotKit Channels SDK ومنصة Intelligence المُدارة.
icon: messages
mode: "wide"
---
## قابل مستخدميك حيث هم بالفعل
وكيل CrewAI الذي بنيته في [النظرة العامة](/edge/ar/guides/frontend/overview) لا يجب أن يعيش خلف تطبيق ويب فقط. يمكن لنفس الـ Crew أو الـ Flow أن يعمل كروبوت داخل منصة مراسلة. لا حاجة لإعادة البناء ولا لنسخة ثانية من منطق وكيلك: يبقى الوكيل مكشوفًا عبر [بروتوكول AG-UI](https://docs.ag-ui.com)، وتقوم **قناة** بتشغيله من Slack أو Microsoft Teams.
يوفّر [Channels SDK](https://docs.copilotkit.ai/slack) من CopilotKit تلك القناة. تُعرّف `createChannel` في وقت تشغيل صغير، وتوجّهه إلى وكيل CrewAI الخاص بك، وتتولى منصة **Intelligence** المُدارة من CopilotKit التوسّط في الاتصال مع مزوّد المراسلة.
<Note>
على خلاف بقية هذا القسم، فإن Channels **ليست ذاتية الاستضافة**. تعمل من خلال **CopilotKit Intelligence** — وهي سطح مطلوب لـ Channels، بحكم التصميم (تتوفر طبقة مجانية). تحتفظ Intelligence باتصال المنصة وبيانات الاعتماد، وتستقبل كل حدث من المنصة، وتسلّم الدور إلى عملية قناتك؛ تشغّل عمليتك الوكيل وتبثّ الرد مرة أخرى. تقوم بإعداد Slack مرة واحدة في لوحة تحكم Intelligence، ولا تدخل بيانات اعتماد المنصة عمليتك أبدًا. يبقى وكيلك وأدواتك وحالتك ملكًا لك.
</Note>
## كيف تتكامل الأجزاء معًا
لا يتغير أي شيء بخصوص خادم وكيل CrewAI الخاص بك. يستمر في تقديم الـ Crew أو الـ Flow عبر AG-UI تمامًا كما في النظرة العامة. ما تضيفه هو عملية Node منفصلة طويلة الأمد مبنية باستخدام `@copilotkit/channels`: تسجّل قناة على `CopilotRuntime`، وتتصل بـ Intelligence، وتشغّل وكيلك كلما وصلت رسالة.
```
Slack / Teams ──► CopilotKit Intelligence ──► channel process (Node) ──► CrewAI server (AG-UI) ──► Crew / Flow
```
تحتفظ عملية القناة باتصال دائم مع بوابة Intelligence، لذا فهي تحتاج إلى مضيف طويل الأمد — لا يمكن لمعالج طلبات بلا خادم (serverless) أن يملك ذلك الاتصال. يمكن لخادم CrewAI الخاص بك أن يستمر في تقديم واجهة الويب الأمامية من النظرة العامة في الوقت نفسه: تطبيق الويب والقناة ما هما إلا عميلان لنقطة نهاية AG-UI واحدة.
## دليل التكامل
<Steps>
<Step title="ثبّت حزم Channels">
يأتي Channels SDK مكتمل العناصر — كل منصة تُشحن في الحزمة الواحدة، بلا محوّل خاص بكل منصة لتثبيته. أضفه إلى جانب وقت التشغيل الذي يستضيف القناة وعميل CrewAI AG-UI:
في [لوحة تحكم CopilotKit](https://docs.copilotkit.ai/slack)، أنشئ قناة واربط Slack — ترشدك Intelligence خلال إنشاء تطبيق Slack وتحتفظ ببيانات اعتماده. يترك ذلك متغيّري بيئة لعمليتك، كلاهما من لوحة التحكم:
```bash
export INTELLIGENCE_API_KEY=... # authenticates the runtime with Intelligence (free tier available)
export INTELLIGENCE_CHANNEL_ID=... # the Channel ID, matched by createChannel({ name })
```
</Step>
<Step title="عرّف القناة">
تُعرّف `createChannel` القناة وتربط وكيلك بها. ابنِ الوكيل كمصنع لكل خيط (thread) بحيث تحصل كل محادثة على جلستها الخاصة، مستخدمًا نفس `CrewAIAgent` الذي تستخدمه النظرة العامة في وقت تشغيل الويب، موجّهًا إلى نقطة نهاية AG-UI الخاصة بك. تتيح `identifyUser: "platform"` لـ Intelligence ربط كل مستخدم من المنصة بهوية ثابتة.
```ts
// channel.ts
import { createChannel } from "@copilotkit/channels";
import { CrewAIAgent } from "@ag-ui/crewai";
const channel = createChannel({
name: process.env.INTELLIGENCE_CHANNEL_ID!, // must match the Channel ID in Intelligence
identifyUser: "platform",
// A fresh agent per conversation, pointed at your CrewAI AG-UI endpoint.
agent: (threadId) => {
const agent = new CrewAIAgent({ url: "http://localhost:8000/recipe" });
agent.threadId = threadId;
return agent;
},
});
// A mention subscribes the thread and runs the agent; afterwards every message
// in a subscribed thread runs it without needing another mention.
channel.onMention(async ({ thread }) => {
await thread.subscribe();
await thread.runAgent();
});
channel.onMessage(async ({ thread }) => {
if (await thread.isSubscribed()) await thread.runAgent();
});
export { channel };
```
</Step>
<Step title="سجّل القناة على وقت التشغيل">
أنشئ `CopilotRuntime` مع بوابة Intelligence وقناتك، ثم قدّمه باستخدام `createCopilotNodeListener`. تبقى خريطة `agents` فارغة — القناة توفّر وكيلها الخاص. انتظر حتى تكون القناة جاهزة كي يفشل بدء التشغيل بصوت عالٍ عند وجود إعداد معطوب.
```ts
// server.ts
import { createServer } from "node:http";
import { CopilotRuntime, CopilotKitIntelligence } from "@copilotkit/runtime/v2";
import { createCopilotNodeListener } from "@copilotkit/runtime/v2/node";
import { channel } from "./channel";
const runtime = new CopilotRuntime({
agents: {}, // the channel supplies its own agent; no web-facing agents needed
intelligence: new CopilotKitIntelligence({
apiKey: process.env.INTELLIGENCE_API_KEY!, // free tier available
اذكر الروبوت في Slack أو Teams فيشغّل الـ Crew أو الـ Flow الخاص بك، ويبثّ الرد مرة أخرى داخل الخيط. يبقى الخيط مشتركًا، لذا تعمل رسائل المتابعة دون الحاجة إلى ذكر آخر.
</Step>
</Steps>
## نموذج الأحداث
تتفاعل القناة مع أحداث المنصة عبر معالِجات، ويستقبل كل معالِج خيطًا (`thread`) تديره بعدد قليل من الدوال:
- **`channel.onMention`** يُطلَق عندما يذكر مستخدم الروبوت بـ @. استدعِ `thread.subscribe()` للانضمام إلى الخيط، ثم `thread.runAgent()` لتشغيل وكيل CrewAI الخاص بك عند الذكر.
- **`channel.onMessage`** يُطلَق عند كل رسالة في خيط يمكن للروبوت رؤيته. قيّده بـ `thread.isSubscribed()` كي لا يستجيب الوكيل إلا حيث انضمّ، ثم `thread.runAgent()`.
- **`thread.runAgent()`** يشغّل وكيل CrewAI المرفق للدور الحالي ويبثّ مخرجاته مرة أخرى داخل القناة. مرّر `{ prompt }` لتجاوز النص الذي يعمل عليه الوكيل.
يستقبل وكيلك `RunAgentInput` عاديًا من AG-UI ويصدر أحداث AG-UI عادية؛ تبقى آليات المنصة خلف القناة، لذا يعمل نفس الـ Crew أو الـ Flow دون تغيير عبر كل منصة. تكشف القناة أيضًا معالِجات للترحيبات والمقاطعات والأوامر والتفاعلات والنوافذ (modals) — راجع [مرجع `Channel`](https://docs.copilotkit.ai/reference/channels/classes/Channel) للاطلاع على السطح الكامل.
## دعم المنصات
يغطي مسار Intelligence المُدار **Slack** و**Microsoft Teams** اليوم — يعمل نفس كود القناة على أيٍّ منهما، وتفيد `message.platform` / `thread.platform` بالأصل الأصلي. تُبلَغ المنصات الأخرى (Discord وTelegram وWhatsApp) عبر **محوّلات مباشرة** يشغّلها المطوّر بدلًا من المسار المُدار — تملك عمليتك الخاصة بيانات اعتماد المنصة والنقل. راجع [توثيق CopilotKit Channels](https://docs.copilotkit.ai/slack) للاطلاع على قائمة المنصات الحالية والإعداد الخاص بكل منصة.
## ذات صلة
<CardGroup cols={2}>
<Card title="النظرة العامة على الواجهة الأمامية" icon="browser" href="/edge/ar/guides/frontend/overview">
قدّم الـ Crew أو الـ Flow الخاص بك عبر AG-UI — الأساس الذي تُبنى عليه كل قناة.
description: ابنِ واجهات مستخدم تفاعلية لوكلاء CrewAI الخاصين بك باستخدام CopilotKit وبروتوكول AG-UI.
icon: browser
mode: "wide"
---
## امنح وكلاءك واجهة مستخدم
يشغّل CrewAI وكلاءك. ويمنحهم [CopilotKit](https://copilotkit.ai) واجهة أمامية. معًا يتيحان لك بناء تطبيقات يحادث فيها المستخدمون Crew أو Flow، ويشاهدونه يعمل في الوقت الفعلي، ويوافقون على قراراته، ويرون مخرجاته معروضة كواجهة حيّة بدلًا من جدران من النص.
يتصل الاثنان عبر [بروتوكول AG-UI](https://docs.ag-ui.com). تكشف حزمة `ag-ui-crewai` أي Crew أو Flow كنقطة نهاية AG-UI. وتستهلك خطافات (hooks) ومكوّنات React من CopilotKit تلك النقطة. يفتح ذلك تجارب تتجاوز بكثير صندوق المحادثة:
<CardGroup cols={2}>
<Card title="واجهة المستخدم التوليدية (Generative UI)" icon="wand-magic-sparkles" href="/edge/en/guides/frontend/generative-ui">
اعرض استدعاءات أدوات الوكيل وحالته كمكوّنات React خاصة بك.
يغطي هذا الدليل المسار **الذاتي الاستضافة**: تشغّل خادم وكيل CrewAI بنفسك باستخدام `ag-ui-crewai`، ويعمل محليًا دون أي خدمة مُدارة. يقدّم CopilotKit أيضًا مسارًا **مُدارًا** (CopilotKit Cloud / Enterprise Intelligence) بخيوط مستضافة وأداة فحص — راجع [دليل البدء السريع لـ CopilotKit مع CrewAI](https://docs.copilotkit.ai/crewai-crews/quickstart) إن أردت ذلك بدلًا منه. كود الواجهة الأمامية في هذا القسم هو نفسه في الحالتين؛ الاختلاف فقط في كيفية استضافة الوكيل وتسجيله.
</Note>
<Note>
يعمل CrewAI خلف AG-UI بثلاثة أشكال: الـ **Flows** العادية (المستخدمة في هذه الأدلة)، و**[الـ Flows المحادثية (Conversational Flows)](/edge/en/guides/frontend/conversational-flows)** (أصلية، مدركة للجلسة، قائمة على الأدوار، بتكافؤ كامل في الميزات)، والـ **Crews** (محادثة أساسية). الواجهة الأمامية في هذا القسم متطابقة عبرها جميعًا — الاختلاف فقط في تأليف الخلفية وتسجيلها.
</Note>
## دليل التكامل
<Steps>
<Step title="قدّم وكيلك عبر AG-UI">
ثبّت حزمة التكامل في مشروع CrewAI الخاص بك:
```bash
pip install ag-ui-crewai
```
اكشف وكيلك من تطبيق FastAPI. تستخدم الـ Flows دالة `add_crewai_flow_fastapi_endpoint`؛ وتستخدم الـ Crews دالة `add_crewai_crew_fastapi_endpoint`. يمكنك تسجيل ما تشاء منها، كلٌّ على مساره الخاص.
<CodeGroup>
```python Flow
# server.py
from fastapi import FastAPI
from ag_ui_crewai.endpoint import add_crewai_flow_fastapi_endpoint
from my_agents.recipe_flow import RecipeFlow
app = FastAPI(title="CrewAI Agent Server")
add_crewai_flow_fastapi_endpoint(
app=app,
flow=RecipeFlow(),
path="/recipe",
)
```
```python Crew
# server.py
from fastapi import FastAPI
from ag_ui_crewai.endpoint import add_crewai_crew_fastapi_endpoint
from my_agents.research_crew import ResearchCrew
app = FastAPI(title="CrewAI Agent Server")
add_crewai_crew_fastapi_endpoint(
app=app,
crew=ResearchCrew().crew(),
path="/research",
)
```
</CodeGroup>
شغّله:
```bash
uvicorn server:app --port 8000
```
<Note>
اضبط متغيّرات البيئة الخاصة بمزوّد الـ LLM الخاص بك (على سبيل المثال `OPENAI_API_KEY`) قبل بدء الخادم.
يوضح هذا الدليل كيفية دمج **Arize Phoenix** مع **CrewAI** باستخدام OpenTelemetry عبر حزمة [OpenInference](https://github.com/openinference/openinference) SDK. بنهاية هذا الدليل، ستتمكن من تتبع وكلاء CrewAI وتصحيح أخطاء وكلائك بسهولة.
يوضح هذا الدليل كيفية دمج **Arize Phoenix** مع **CrewAI** باستخدام OpenTelemetry عبر حزمة [OpenInference](https://github.com/openinference/openinference) SDK. بنهاية هذا الدليل، ستتمكن من تتبع وكلاء CrewAI وتصحيح سلوك الوكلاء.
> **ما هو Arize Phoenix؟** [Arize Phoenix](https://phoenix.arize.com) هو منصة مراقبة LLM توفر التتبع والتقييم لتطبيقات الذكاء الاصطناعي.
> **ما هو Arize Phoenix؟** [Arize Phoenix](https://arize.com/phoenix/) هو خيار المراقبة والتقييم مفتوح المصدر من [Arize AI](https://arize.com/?utm_source=crewai-docs&utm_medium=partner&utm_campaign=partner-docs&utm_content=observability-arize-phoenix). استخدم Phoenix عندما تريد التشغيل محلياً أو الاستضافة الذاتية. استخدم [Arize AX](https://arize.com/products/ax/) لمنصة سحابية مُدارة أو ذاتية الاستضافة للمؤسسات لأنظمة الذكاء الاصطناعي في الإنتاج.
[](https://www.youtube.com/watch?v=Yc5q3l6F7Ww)
قم بإعداد مفاتيح API لـ Phoenix Cloud وإعداد OpenTelemetry لإرسال التتبعات إلى Phoenix. Phoenix Cloud هو إصدار مستضاف من Arize Phoenix، لكنه ليس مطلوباً لاستخدام هذا التكامل.
قم بإعداد مفتاح API الخاص بـ Phoenix ونقطة نهاية OpenTelemetry لإرسال التتبعات إلى Phoenix. يعمل الإعداد نفسه مع نقطة نهاية Phoenix محلية أو ذاتية الاستضافة عن طريق تغيير عنوان المجمع.
يمكنك الحصول على مفتاح Serper API المجاني [هنا](https://serper.dev/).
os.environ["PHOENIX_COLLECTOR_ENDPOINT"] = "https://app.phoenix.arize.com" # Phoenix Cloud, change this to your own endpoint if you are using a self-hosted instance
os.environ["PHOENIX_COLLECTOR_ENDPOINT"] = "https://app.phoenix.arize.com" # Change this to your own endpoint if you are using a self-hosted instance
os.environ["OPENAI_API_KEY"] = OPENAI_API_KEY
os.environ["SERPER_API_KEY"] = SERPER_API_KEY
```
@@ -131,7 +131,7 @@ print(result)
بعد تشغيل الوكيل، يمكنك عرض التتبعات المولدة من تطبيق CrewAI في Phoenix. سترى خطوات مفصلة لتفاعلات الوكلاء واستدعاءات LLM، مما يساعدك في التصحيح والتحسين.
سجل الدخول إلى حساب Phoenix Cloud الخاص بك وانتقل إلى المشروع الذي حددته في معامل `project_name`. سترى عرض زمني للتتبع مع جميع تفاعلات الوكلاء واستخدامات الأدوات واستدعاءات LLM.
افتح مشروع Phoenix وانتقل إلى المشروع الذي حددته في معامل `project_name`. سترى عرض زمني للتتبع مع جميع تفاعلات الوكلاء واستخدامات الأدوات واستدعاءات LLM.
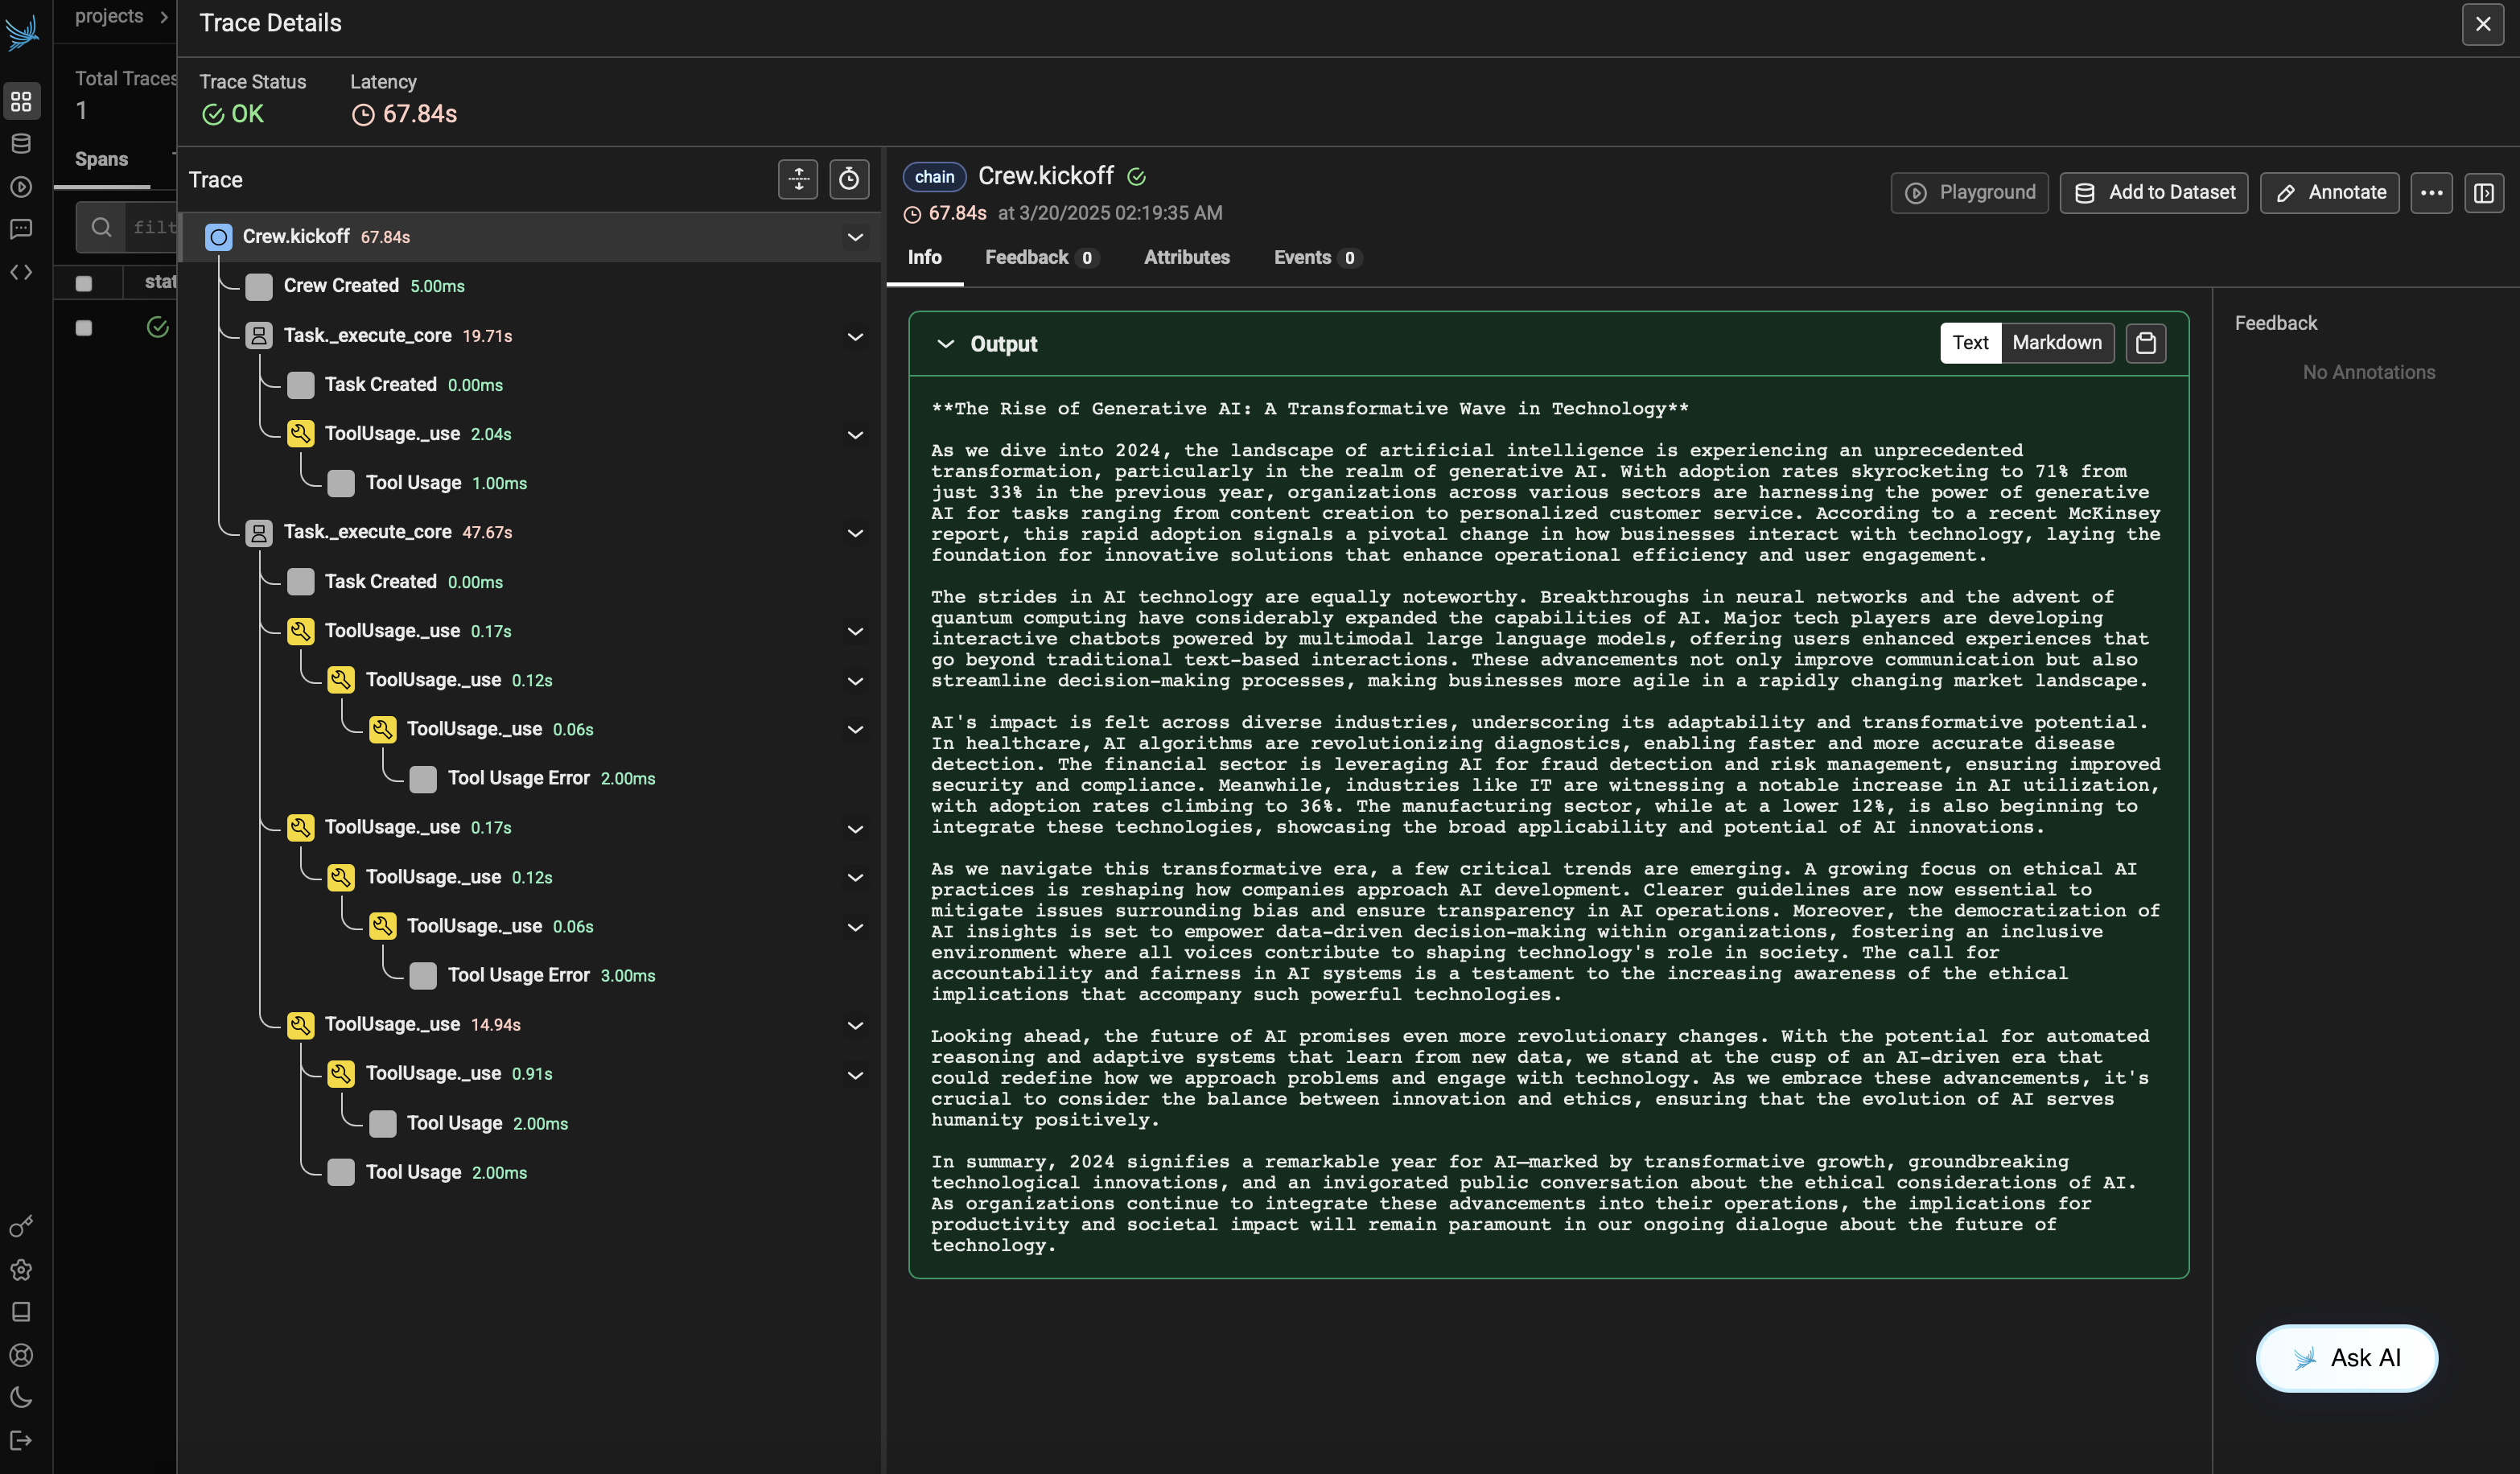
@@ -145,6 +145,9 @@ print(result)
### المراجع
- [وثائق Phoenix](https://docs.arize.com/phoenix/) - نظرة عامة على منصة Phoenix.
يوفر CrewAI إمكانيات تتبع مدمجة تتيح لك مراقبة وتصحيح أخطاء الطواقم والتدفقات في الوقت الفعلي. يوضح هذا الدليل كيفية تفعيل التتبع لكل من **الطواقم** و**التدفقات** باستخدام منصة المراقبة المتكاملة في CrewAI.
> **ما هو تتبع CrewAI؟** يوفر التتبع المدمج في CrewAI مراقبة شاملة لوكلاء الذكاء الاصطناعي، بما في ذلك قرارات الوكلاء وجداول تنفيذ المهام واستخدام الأدوات واستدعاءات LLM - كل ذلك متاح عبر [منصة CrewAI AMP](https://app.crewai.com).
> **ما هو تتبع CrewAI؟** يوفر التتبع المدمج في CrewAI مراقبة شاملة لوكلاء الذكاء الاصطناعي، بما في ذلك قرارات الوكلاء وجداول تنفيذ المهام واستخدام الأدوات واستدعاءات LLM - كل ذلك متاح عبر [منصة CrewAI AMP](https://app.crewai.com). يتم إدارة التتبع بشكل مستقل عن [القياس عن بُعد](/ar/telemetry).

@@ -150,8 +150,8 @@ result = flow.kickoff()
### الخطوة 5: عرض التتبعات في لوحة تحكم CrewAI AMP
بعد تشغيل الطاقم أو التدفق، يمكنك عرض التتبعات التي أنشأها تطبيق CrewAI في لوحة تحكم CrewAI AMP. يجب أن ترى خطوات تفصيلية لتفاعلات الوكلاء واستخدامات الأدوات واستدعاءات LLM.
ما عليك سوى النقر على الرابط أدناه لعرض التتبعات أو التوجه إلى علامة تبويب التتبعات في لوحة التحكم [هنا](https://app.crewai.com/crewai_plus/trace_batches)
لا تُرفع التتبعات إلا بعد نجاح التصدير باستخدام المصادقة أو الرفع المجهول الذي وافقت عليه صراحةً. لا يوجد تتبع مرفوع لأي تشغيل حُذف مخزنه المؤقت المحلي.
للتتبعات المرتبطة بحسابك، افتح [علامة تبويب التتبعات في لوحة تحكم CrewAI AMP](https://app.crewai.com/crewai_plus/trace_batches) لعرض تفاعلات الوكلاء واستخدام الأدوات واستدعاءات LLM.

### البديل: إعداد متغير البيئة
@@ -170,6 +170,49 @@ CREWAI_TRACING_ENABLED=true
عند تعيين متغير البيئة هذا، ستُفعّل جميع الطواقم والتدفقات التتبع تلقائياً، حتى بدون تعيين `tracing=True` صراحةً.
## عرض التتبعات بعد أول تشغيل
في المرة الأولى التي تشغّل فيها طاقماً أو تدفقاً، قد يسألك طرف تفاعلي:
```text
Share this execution trace with CrewAI? [y/N]
```
اختر **yes** لرفع التتبع المخزّن مؤقتاً إلى CrewAI. قد تحتوي التتبعات على
المطالبات والمدخلات والمخرجات. يُحذف المخزن المؤقت عند الرفض أو انتهاء المهلة
أو التشغيل دون مطالبة تفاعلية بالموافقة. يمكنك تغيير إعداد التتبع لاحقاً باستخدام
`crewai traces enable` أو `crewai traces disable`، أو بتعيين `tracing`
على الطاقم أو التدفق.
### التخزين المؤقت المحلي والتصدير بعد المصادقة
يبقى جمع التتبعات في أول تشغيل داخل ذاكرة العملية إلى أن توافق على المشاركة،
حتى إذا كانت لديك بيانات تسجيل دخول محفوظة. يستخدم التتبع دون مصادقة مسار
الموافقة نفسه. قبل الموافقة، لا يطلب CrewAI تصريح رفع ولا يرسل أي مقاطع تنفيذ.
يحتفظ المخزن المؤقت بحد أقصى **1,000 مقطع** و**8 MiB من بيانات OTLP المرمّزة**.
اضبط `CREWAI_EPHEMERAL_TRACE_MAX_SPANS` و
`CREWAI_EPHEMERAL_TRACE_MAX_BYTES` على أعداد صحيحة موجبة لتعديل هذين الحدّين.
عند تجاوز السعة، تُحذف أقدم المقاطع؛ ويُحذف أي مقطع يتجاوز وحده حد البايتات.
يُفرّغ المخزن المؤقت بعد مشاركته أو تجاهله.
عند تفعيل التتبع وتوفّر بيانات الاعتماد، يستبدل CrewAI بيانات تسجيل دخول CLI
أو `CREWAI_USER_PAT` أو بيانات اعتماد تكامل المنصة لدى AMP بتصريح خاص
بالتنفيذ. ثم يصدّر مقاطع OpenTelemetry مباشرةً إلى Wharf باستخدام ذلك التصريح.
لا تؤدي بيانات الاعتماد غير الصالحة إلى الرجوع إلى الرفع المجهول.
### جلسات التنفيذ المستضافة
يمكن للبيئات المضيفة إحاطة التنفيذ بـ `telemetry_session` من
`crewai.telemetry.tracing`. تستخدم الجلسة أحداث دورة حياة CrewAI لإنشاء
المقاطع وإنهائها، مع الحفاظ على طوابعها الزمنية وعلاقاتها بالمقاطع الأصل وروابط
الإيقاف والاستئناف في HITL. مرّر موفّراً موجوداً عبر `providers=` للاحتفاظ
بمتتبّع البيئة المضيفة وتكامل التسجيل لديها. مرّر معالجات المقاطع عبر
`processors=` ودالة تسجيل للمضيف عبر `log_emitter=`. يتولى المضيف أي تنقيح
للبيانات في هذه التكاملات.
تدير كل جلسة دورة حياة التتبع الخاصة بها وتترك موفّر OpenTelemetry العام
للتطبيق دون تغيير.
## عرض التتبعات
### الوصول إلى لوحة تحكم CrewAI AMP
@@ -210,5 +253,5 @@ CREWAI_TRACING_ENABLED=true
1. تأكد من تعيين `tracing=True` في الطاقم/التدفق
2. تحقق من `CREWAI_TRACING_ENABLED=true` إذا كنت تستخدم متغيرات البيئة
3. تأكد من المصادقة عبر `crewai login`
4. تحقق من أن الطاقم/التدفق قيد التنفيذ فعلاً
3. للتصدير باستخدام المصادقة، تحقّق من تسجيل دخول CLI أو `CREWAI_USER_PAT` أو بيانات اعتماد تكامل المنصة. للمشاركة المجهولة، وافق صراحةً على مطالبة الموافقة؛ لا يلزم تسجيل الدخول
4. تحقّق من تنفيذ الطاقم/التدفق ونجاح تصدير التتبع. يؤدي رفض الموافقة أو انتهاء المهلة أو التشغيل دون مطالبة تفاعلية بالموافقة إلى حذف المخزن المؤقت المحلي دون رفعه
عند تفعيل ميزة `share_crew`، يتم جمع بيانات تفصيلية تشمل أوصاف المهام وخلفيات وأهداف الوكلاء وسمات محددة أخرى
لتوفير رؤى أعمق. قد يتضمن جمع البيانات الموسع هذا معلومات شخصية إذا دمجها المستخدمون في طواقمهم أو مهامهم.
يجب على المستخدمين النظر بعناية في محتوى طواقمهم ومهامهم قبل تفعيل `share_crew`.
يمكن للمستخدمين تعطيل القياس عن بُعد عبر تعيين متغير البيئة `CREWAI_DISABLE_TELEMETRY` إلى `true` أو تعيين `OTEL_SDK_DISABLED` إلى `true` (لاحظ أن الأخير يعطل جميع أدوات OpenTelemetry عالمياً).
يمكن للمستخدمين تعطيل القياس عن بُعد في CrewAI عبر تعيين `CREWAI_DISABLE_TELEMETRY` إلى `true` أو `1` أو `yes` أو `on` (بغض النظر عن حالة الأحرف). `OTEL_SDK_DISABLED` بنفس القيم يعطّل أيضاً مُصدِّر CrewAI. مجموعة أدوات OpenTelemetry نفسها ما تزال تقبل `true` فقط لتعطيل بقية أدوات القياس في العملية.
تتبع AMP مشمول بشكل منفصل في [التتبع](/ar/observability/tracing).
| نعم | إصدار CrewAI وPython | تتبع إصدارات البرمجيات. مثال: CrewAI v1.2.3، Python 3.8.10. لا بيانات شخصية. |
| نعم | بيانات وصفية للطاقم | تشمل: مفتاح ومعرّف مُولّد عشوائياً، نوع العملية (مثل 'sequential'، 'parallel')، علم منطقي لاستخدام الذاكرة (true/false)، عدد المهام، عدد الوكلاء. كلها غير شخصية. |
| نعم | بيانات وصفية للطاقم | تشمل: مفتاح ومعرّف مُولّد عشوائياً، نوع العملية (مثل 'sequential'، 'parallel')، علم منطقي لاستخدام الذاكرة (true/false)، علم منطقي يوضح ما إذا تم تمرير أي مدخلات للتشغيل (true/false — وليس مفاتيح المدخلات أو قيمها، والتي لا تُجمع إلا عند تمكين `share_crew`)، عدد المهام، عدد الوكلاء. كلها غير شخصية. |
| نعم | بيانات الوكيل | تشمل: مفتاح ومعرّف مُولّد عشوائياً، اسم الدور (يجب ألا يتضمن معلومات شخصية)، إعدادات منطقية (verbose، التفويض مُفعّل، تنفيذ الكود مسموح)، أقصى عدد تكرارات، أقصى RPM، أقصى حد لإعادة المحاولة، معلومات LLM (انظر سمات LLM)، قائمة أسماء الأدوات (يجب ألا تتضمن معلومات شخصية). لا بيانات شخصية. |
| نعم | بيانات وصفية للمهمة | تشمل: مفتاح ومعرّف مُولّد عشوائياً، إعدادات تنفيذ منطقية (async_execution، human_input)، دور ومفتاح الوكيل المرتبط، قائمة أسماء الأدوات. كلها غير شخصية. |
| نعم | إحصائيات استخدام الأدوات | تشمل: اسم الأداة (يجب ألا يتضمن معلومات شخصية)، عدد محاولات الاستخدام (عدد صحيح)، سمات LLM المستخدمة. لا بيانات شخصية. |
| نعم | بيانات تنفيذ الاختبار | تشمل: مفتاح ومعرّف الطاقم المُولّد عشوائياً، عدد التكرارات، اسم النموذج المستخدم، درجة الجودة (عدد عشري)، وقت التنفيذ (بالثواني). كلها غير شخصية. |
| نعم | بيانات دورة حياة المهمة | تشمل: أوقات الإنشاء وبدء/انتهاء التنفيذ، معرّفات الطاقم والمهمة. مخزنة كنطاقات مع طوابع زمنية. لا بيانات شخصية. |
| نعم | بيانات دورة حياة المهمة | تشمل: أوقات الإنشاء وبدء/انتهاء التنفيذ، معرّفات الطاقم والمهمة، وما إذا نجحت المهمة أو فشلت. وعند فشل المهمة، يُسجَّل **اسم صنف** الاستثناء (مثل `TimeoutError`) بحيث يمكن عدّ حالات الفشل وتشخيصها — وليس رسالة الخطأ أبدًا، فهي قد تحتوي على مطالبات أو مخرجات نموذج أو مسارات ملفات أو بيانات اعتماد. مخزنة كنطاقات مع طوابع زمنية. لا بيانات شخصية. |
| نعم | سمات LLM | تشمل: الاسم، model_name، model، top_k، temperature، واسم فئة LLM. كلها بيانات تقنية غير شخصية. |
| نعم | محاولة نشر الطاقم باستخدام CLI الخاص بـ CrewAI | تشمل: حقيقة إجراء النشر ومعرّف الطاقم، وما إذا كان يحاول سحب السجلات، وما إذا بدأ النشر من أمر CLI أو من واجهة التشغيل TUI. لا تُسجَّل محتويات المشروع أو الطاقم. لا توجد بيانات شخصية. |
| نعم | بيئة التنفيذ | تشمل: مساعد البرمجة بالذكاء الاصطناعي الذي يشغّل العملية إن وُجد (واحد من قائمة ثابتة مثل `claude_code` أو `codex` أو `cursor` أو `unknown`)، ومكان تشغيل العملية (واحد من قائمة ثابتة مثل `ci` أو `container` أو `serverless` أو `interactive`)، و`project_id` من ملف `pyproject.toml` عند ضبطه. يتحقق الاكتشاف فقط مما إذا كانت متغيرات البيئة المعروفة مضبوطة، ولا يقرأ قيمها أبدًا. لا بيانات شخصية. |
| نعم | إنشاء مشروع باستخدام CLI الخاص بـ CrewAI | تشمل: أن مشروعًا جديدًا أُنشئ عبر `crewai create`، ونوعه (`crew` أو `json_crew` أو `flow`)، ومعرّف المشروع الذي تم توليده لهذا المشروع الجديد وكُتب في ملف `pyproject.toml` الخاص به. وهو معرّف المشروع الجديد نفسه، ويُسجَّل بشكل منفصل عن `project_id` الخاص بالمجلد الذي شُغّل منه الأمر — وقد يختلفان. لا اسم مشروع، ولا محتويات ملفات، ولا شيفرة. لا بيانات شخصية. |
| نعم | محاولة نشر الطاقم باستخدام CLI الخاص بـ CrewAI | تشمل: حقيقة إجراء النشر ومعرّف الطاقم، وما إذا كان يحاول سحب السجلات، وما إذا بدأ النشر من أمر CLI أو من واجهة التشغيل TUI. إذا فشل إنشاء النشر، تُسجَّل فئة الفشل (واحدة من قائمة ثابتة مثل `api_4xx` أو `network_error` أو `user_declined`) ورمز حالة HTTP لاستجابة API إن وُجدت — ولا تُسجَّل رسالة الخطأ أبدًا. لا تُسجَّل محتويات المشروع أو الطاقم. لا توجد بيانات شخصية. |
| نعم | بيئة التنفيذ | تشمل: مساعد البرمجة بالذكاء الاصطناعي الذي يشغّل العملية إن وُجد (واحد من قائمة ثابتة مثل `claude_code` أو `codex` أو `cursor` أو `unknown`)، ومكان تشغيل العملية (واحد من قائمة ثابتة مثل `ci` أو `container` أو `serverless` أو `interactive`)، و`project_id` من ملف `pyproject.toml` عند ضبطه، ونطاقًا تقريبيًا لحجم الجهاز (واحد من `1-2` أو `3-4` أو `5-8` أو `9-16` أو `17-32` أو `33+` أو `unknown`). النطاق مجال وليس العدد الدقيق للأنوية أبدًا — العدد الدقيق اختياري فقط، ضمن «معلومات البيئة» أدناه. تأتي فئة الحجم من عدد أنوية المضيف؛ ويتحقق اكتشاف المساعد وموقع التشغيل فقط مما إذا كانت متغيرات البيئة المعروفة مضبوطة، ولا يقرأ قيمها أبدًا. لا بيانات شخصية. |
| نعم | إشارات دورة حياة التدفق | تشمل: بدء التدفق، وما إذا اكتمل أو فشل، وما إذا فشلت إحدى طرقه، وما إذا توقف مؤقتًا لانتظار إدخال أو ملاحظات بشرية، وما إذا كان البدء تشغيلًا مستأنفًا، وما إذا فشل دور محادثة، ومدة تشغيل التدفق، وما إذا كان التدفق مما تشغّله CrewAI داخليًا أو مما كتبته أنت. ويُسجَّل اسم التدفق، كما هو الحال بالفعل لإنشاء التدفق وتنفيذه. وعند فشل تدفق أو إحدى طرقه، يُسجَّل **اسم فئة** الاستثناء (مثل `TimeoutError`) لتشخيص الأعطال — ولا تُسجَّل أبدًا رسالة الخطأ، التي قد تحتوي على مطالبات أو مخرجات النموذج أو مسارات ملفات أو بيانات اعتماد. ولا تُسجَّل أبدًا أسماء الطرق أو حالة التدفق. لا توجد بيانات شخصية. |
| نعم | إشارة مشاركة التتبع | تشمل: نجاح مشاركة دفعة من عمليات التتبع مع CrewAI AMP، وما إذا تمت المشاركة بشكل مجهول (قبل إنشاء حساب) أو مرتبطة بحسابك. ومثل كل span، تحمل أيضًا سمات بيئة التنفيذ الموضحة أعلاه (`project_id` عند تكوينه، ومساعد البرمجة، وبيئة التشغيل). يصف هذا الصف بيانات القياس عن بُعد الخاصة بالمشاركة فقط — وليس محتويات التتبع أو الوصول الذي تمنحه روابط التتبع المشتركة. لا تُسجَّل محتويات التتبع أو المدخلات أو المخرجات في هذه الإشارة. قبل مشاركة التتبعات، راجع الأسرار والبيانات الشخصية وإعدادات التنقيح والاحتفاظ في AMP. |
| لا | بيانات الوكيل الموسّعة | تشمل: وصف الهدف، نص الخلفية، معرّف ملف موجهات i18n. يجب على المستخدمين التأكد من عدم تضمين معلومات شخصية في حقول النص. |
- `model_name` (str): اسم نموذج Sentence Transformers. القيمة الافتراضية: `all-MiniLM-L6-v2`. الخيارات: `all-mpnet-base-v2`، `all-MiniLM-L6-v2`، `paraphrase-multilingual-MiniLM-L12-v2`
- `device` (str): الجهاز للتشغيل. القيمة الافتراضية: `cpu`. الخيارات: `cpu`، `cuda`، `mps`
- `device` (str): الجهاز للتشغيل. القيمة الافتراضية: `cpu`. الخيارات: `cpu`، `cuda`، `mps`، `xpu`
- `normalize_embeddings` (bool): ما إذا كان يتم تطبيع التضمينات. القيمة الافتراضية: `False`
أداة `ScrapeElementFromWebsiteTool` مصممة لاستخراج عناصر محددة من المواقع باستخدام محددات CSS. تسمح هذه الأداة لوكلاء CrewAI باستخراج محتوى مستهدف من صفحات الويب، مما يجعلها مفيدة لمهام استخراج البيانات حيث تكون أجزاء محددة فقط من صفحة الويب مطلوبة.
أداة `ScrapeElementFromWebsiteTool` مصممة لاستخراج عناصر محددة من المواقع باستخدام محددات CSS. تسمح هذه الأداة لوكلاء CrewAI باستخراج محتوى مستهدف من صفحات الويب، مما يجعلها مفيدة لمهام استخراج البيانات حيث تكون أجزاء محددة فقط من صفحة الويب مطلوبة. تمر الطلبات عبر مساعد HTTP الآمن ضد SSRF في CrewAI: يتم فحص عنوان URL المطلوب وكل قفزة إعادة توجيه مقابل النطاقات الخاصة والمحجوزة (بما في ذلك بيانات تعريف السحابة)، ويُثبَّت اتصال TCP على عنوان IP الذي اجتاز هذا الفحص.
أداة مصممة لاستخراج وقراءة محتوى موقع محدد. قادرة على التعامل مع أنواع مختلفة من صفحات الويب عن طريق إجراء طلبات HTTP وتحليل محتوى HTML المستلم.
يمكن أن تكون هذه الأداة مفيدة بشكل خاص لمهام استخراج البيانات من الويب وجمع البيانات أو استخراج معلومات محددة من المواقع.
تمر الطلبات عبر مساعد HTTP الآمن ضد SSRF في CrewAI: يتم فحص عنوان URL المطلوب وكل قفزة إعادة توجيه مقابل النطاقات الخاصة والمحجوزة (بما في ذلك بيانات تعريف السحابة)، ويُثبَّت اتصال TCP على عنوان IP الذي اجتاز هذا الفحص.
- Initiates the deployment process on the CrewAI AMP platform.
- Upon successful initiation, it will output the Deployment created successfully! message along with the Deployment Name and a unique Deployment ID (UUID).
- Push keeps the source used at create. Adding a git `origin` later does not switch a ZIP deployment to git.
- **Deployment Status**: You can check the status of your deployment with:
@@ -578,6 +579,7 @@ Trace collection is controlled by checking three settings in priority order:
```
- Checked only if `tracing` is not set in code and `CREWAI_TRACING_ENABLED` is not set to `true`
- Running `crewai traces enable` is sufficient to enable tracing by itself
- The first-run prompt (`Would you like to view your execution traces?`) also updates this preference
<Note>
**To enable tracing**, use any one of these methods:
@@ -37,7 +37,7 @@ A crew in crewAI represents a collaborative group of agents working together to
| **Chat LLM** _(optional)_ | `chat_llm` | The language model used to orchestrate `crewai chat` CLI interactions with the crew. Accepts a model name string or `LLM` instance. Defaults to `None`. |
| **Before Kickoff Callbacks** _(optional)_ | `before_kickoff_callbacks` | A list of callable functions executed **before** the crew starts. Each callback receives and can modify the inputs dict. Distinct from the `@before_kickoff` decorator. Defaults to `[]`. |
| **After Kickoff Callbacks** _(optional)_ | `after_kickoff_callbacks` | A list of callable functions executed **after** the crew finishes. Each callback receives and can modify the `CrewOutput`. Distinct from the `@after_kickoff` decorator. Defaults to `[]`. |
| **Tracing** _(optional)_ | `tracing` | Controls OpenTelemetry tracing for the crew. `True` = always enable, `False` = always disable, `None` = inherit from environment / user settings. Defaults to `None`. |
| **Tracing** _(optional)_ | `tracing` | Controls tracing for the crew. `True` = always enable, `False` = always disable, `None` = inherit from environment / user settings. Defaults to `None`. |
| **Skills** _(optional)_ | `skills` | A list of `Path` objects (skill search directories) or pre-loaded `Skill` objects applied to all agents in the crew. Defaults to `None`. |
| **Security Config** _(optional)_ | `security_config` | A `SecurityConfig` instance managing crew fingerprinting and identity. Defaults to `SecurityConfig()`. |
| **Checkpoint** _(optional)_ | `checkpoint` | Enables automatic checkpointing. Pass `True` for sensible defaults, a `CheckpointConfig` for full control, `False` to opt out, or `None` to inherit. See the [Checkpointing](#checkpointing) section below. Defaults to `None`. |
Gateways such as OpenRouter return `200 OK` as soon as the upstream provider accepts the request, so a provider timeout arrives in the response body instead of the status code.
</Tip>
CrewAI raises the same exception the upstream code would have produced as a real HTTP status, so a masked failure is caught by the retry handling you already have:
result = llm.call("Summarize the incident", response_model=Report)
except openai.InternalServerError as e:
# "z-ai/glm-5.3 via openrouter.ai returned HTTP 200 with an upstream error
# and no choices: The operation was aborted (upstream code 504)"
print(f"Upstream provider failed, safe to retry: {e}")
```
<Warning>
A large or deeply nested `response_model` makes upstream timeouts more likely. Treat these as transient provider failures, not as the model producing malformed structured output.
@@ -210,13 +210,17 @@ Publishing reads `name`, `description`, and `metadata.version` from the `SKILL.m
### Install
Install a published skill by its `@org/name` reference:
Install a published skill by its `@org-uuid/name` reference:
```shell Terminal
crewai skill install @acme/code-review
crewai skill install @your-org-uuid/code-review
```
Inside a crew project the skill lands in `./skills/{name}/`; outside a project it goes to the shared cache at `~/.crewai/skills/{org}/{name}/`.
<Note>
Use your organization's **UUID**, not its name — organization names are not unique, so a name can resolve to the wrong organization and the install fails with a "not found" error. Run `crewai org list` to see the UUID (the `ID` column) of every organization you belong to.
</Note>
Inside a crew project the skill lands in `./skills/{name}/`; outside a project it goes to the shared cache at `~/.crewai/skills/{org-uuid}/{name}/`.
Agents can also reference registry skills directly — they resolve from the local cache (or project `skills/` directory) at runtime:
@@ -225,7 +229,7 @@ agent = Agent(
role="Senior Code Reviewer",
goal="Review pull requests for quality and security issues",
backstory="Staff engineer with expertise in secure coding practices.",
@@ -26,7 +26,7 @@ Under the hood, CrewAI employs a modular prompt system that you can customize ex
- **Error handling** – Direct how agents respond to failures, exceptions, or timeouts.
- **Tool-specific prompts** – Define detailed instructions for how tools are invoked or utilized.
Check out the [original prompt templates in CrewAI's repository](https://github.com/crewAIInc/crewAI/blob/main/src/crewai/translations/en.json) to see how these elements are organized. From there, you can override or adapt them as needed to unlock advanced behaviors.
Check out the [original prompt templates in CrewAI's repository](https://github.com/crewAIInc/crewAI/blob/main/lib/crewai/src/crewai/translations/en.json) to see how these elements are organized. From there, you can override or adapt them as needed to unlock advanced behaviors.
Use the CrewAI CLI to scaffold a project, then `AGENTS.md` will be automatically added at the root.
Use the CrewAI CLI to scaffold a project. `AGENTS.md` is added at the root, together with a `CLAUDE.md` and a `GEMINI.md` that import it, so Claude Code and Gemini CLI read the same guidance as every other assistant.
```bash
# Crew
@@ -36,24 +36,28 @@ Codex can be guided by `AGENTS.md` files placed in your repository. Use them to
### Claude Code
Claude Code stores project memory in `CLAUDE.md`. You can bootstrap it with `/init` and edit it using `/memory`. Claude Code also supports imports inside `CLAUDE.md`, so you can add a single line like `@AGENTS.md` to pull in the shared instructions without duplicating them.
Claude Code reads `CLAUDE.md` and ignores `AGENTS.md`. Scaffolded projects ship a `CLAUDE.md` whose only instruction is the import line `@AGENTS.md`, so the shared guidance is loaded without duplicating it. Add Claude-specific notes under that line and keep shared conventions in `AGENTS.md`.
You can simply use:
For a project created before `CLAUDE.md` was scaffolded, add the import yourself:
```bash
mv AGENTS.md CLAUDE.md
printf '@AGENTS.md\n' > CLAUDE.md
```
Do not rename `AGENTS.md` to `CLAUDE.md`: Codex and Cursor read `AGENTS.md`, and the rename hides it from them.
### Gemini CLI and Google Antigravity
Gemini CLI and Antigravity load a project context file (default: `GEMINI.md`) from the repo root and parent directories. You can configure it to read `AGENTS.md` instead (or in addition) by setting `context.fileName` in your Gemini CLI settings. For example, set it to `AGENTS.md` only, or include both `AGENTS.md` and `GEMINI.md` if you want to keep each tool’s format.
Gemini CLI and Antigravity load a project context file (default: `GEMINI.md`) from the repo root and parent directories. Scaffolded projects ship a `GEMINI.md` whose only instruction is the import line `@./AGENTS.md`, so the shared guidance is loaded without duplicating it. Add Gemini-specific notes under that line and keep shared conventions in `AGENTS.md`.
You can simply use:
For a project created before `GEMINI.md` was scaffolded, add the import yourself:
```bash
mv AGENTS.md GEMINI.md
printf '@./AGENTS.md\n' > GEMINI.md
```
Alternatively, set `context.fileName` in your Gemini CLI settings to include `AGENTS.md` and Gemini reads it directly. Do not rename `AGENTS.md` to `GEMINI.md`: Codex and Cursor read `AGENTS.md`, and the rename hides it from them.
### Cursor
Cursor supports `AGENTS.md` as a project instruction file. Place it at the project root to provide guidance for Cursor’s coding assistant.
description: Build multi-turn chat apps with handle_turn per turn, message history, intent routing, tracing, and WebSocket bridges.
description: Build multi-turn chat apps with handle_turn per turn, message history, intent routing, tracing, and structured streaming.
icon: comments
mode: "wide"
---
## Overview
Conversational apps treat each user line as a **new flow run** with the **same session id**. CrewAI adds helpers for message history, optional intent routing, deferred tracing, UI bridges, and a local `flow.chat()` REPL for conversational flows.
Conversational apps treat each user line as a **new flow run** with the **same session id**. CrewAI adds helpers for message history, optional intent routing, deferred tracing, structured turn streaming, and a local `flow.chat()` REPL.
For the full frame contract, channel list, and async API, see [Streaming Runtime Contract](/edge/en/learn/streaming-runtime-contract).
For the full frame contract and channel list, see [Streaming Runtime Contract](/edge/en/learn/streaming-runtime-contract).
## Turn lifecycle
@@ -111,29 +110,18 @@ Each `handle_turn` runs this pipeline:
2. **State restore** — if `inputs["id"]` exists and `@persist` is configured, loads the latest snapshot.
3. **`FlowStarted`** — emitted on the first deferred session turn only.
4. **Pending turn hydration** — appends the user message to `state.messages`, sets `current_user_message` / `last_user_message`, and optionally classifies when `intents` / `default_intents` + `intent_llm` are set.
5. **Graph execution** — user-defined `@start` methods (if any) → `route_conversation` (the built-in start/router) → the selected `@listen` handler. `route_conversation` also calls the overridable `conversation_start()` helper.
6. **End of run** — per-turn `flow_finished` and trace finalization are **skipped** when deferral is enabled; nested `Agent.kickoff()` / crews do not close the parent batch either.
Handlers should call **`append_assistant_message(reply)`** so the next turn’s `conversation_messages` includes assistant text. The user line is already stored by `handle_turn` — do not append it again in handlers.
Handlers should call **`append_assistant_message(reply)`** when the visible reply is not the return value, or when you trim history. A public string return is also recorded as assistant and included in the `@persist` snapshot, so a fresh Flow instance restores it. The user line is already stored by `handle_turn` — do not append it again in handlers.
## `ConversationConfig` (class-level defaults)
## Configuration overview
Decorate your conversational `Flow` subclass with `ConversationConfig`.
| Field | Default | Purpose |
|-------|---------|---------|
| `system_prompt` | Framework default | System message used by the built-in `converse_turn`. |
| `llm` | `None` | Conversation LLM used by `converse_turn` and as router fallback. |
| `router` | `None` | `RouterConfig` for LLM-driven routing. |
| `default_intents` | `None` | Outcome labels for pre-classification. |
| `defer_trace_finalization` | `True` | Keep one trace batch open across `handle_turn()` calls. |
Override pre-classification per turn with `handle_turn(..., intents=..., intent_llm=...)`.
Decorating a `Flow` subclass with `ConversationConfig` both attaches the chat defaults and enables conversational mode. See the [full field reference](#conversationconfig) below. Override pre-classification per turn with `handle_turn(..., intents=..., intent_llm=...)`.
## Lower-level `ChatState` helpers
`ChatState`, `ConversationalConfig`, and `crewai.flow.conversation` helpers are still importable for advanced orchestration, tests, or custom wrappers. They do not add `user_message=` or `session_id=` keyword arguments to `Flow.kickoff()`.
`ChatState`, the legacy `ConversationalConfig`, and `crewai.flow.conversation` helpers are still importable for advanced orchestration, tests, or custom wrappers. They are separate from the `ConversationState` / `ConversationConfig` API and do not add `user_message=` or `session_id=` keyword arguments to `Flow.kickoff()`.
```python
from crewai.flow import ChatState
@@ -155,6 +143,8 @@ class MyChatState(ChatState):
`ConversationalInputs` is a `TypedDict` for conventional `kickoff(inputs={...})` keys: `id`, `user_message`, `last_intent`.
`ConversationState` stores `messages` as `ConversationMessage` objects and additionally provides `current_user_message`, `ended`, `events`, and `agent_threads`. Use `conversation_messages` when passing its canonical history to an LLM.
## `Flow` conversational API
### `handle_turn` parameters
@@ -176,9 +166,9 @@ class MyChatState(ChatState):
| Attribute | Purpose |
|-----------|---------|
| `conversational` | Set to `True` to enable the conversational graph and `handle_turn()` |
| `defer_trace_finalization` | Instance flag; set automatically from config on `handle_turn()` |
| `_should_defer_trace_finalization()` | Advanced/internal hook that resolves whether per-turn trace finalization is deferred |
| `input_history` | Audit trail of `ask()` prompts and responses |
### Module helpers (`crewai.flow.conversation`)
Importable for tests or custom orchestration:
Importable from `crewai.flow.conversation` for tests or custom orchestration. These helpers use the legacy `ConversationalConfig` shape; `prepare_conversational_turn()` also clears `last_intent`, unlike `handle_turn()`, which preserves it as router context.
| Function | Description |
|----------|-------------|
@@ -212,7 +202,7 @@ Importable for tests or custom orchestration:
### A. Pre-classify via `ConversationConfig` (simplest)
Set `default_intents` and `intent_llm`. Each `handle_turn()` runs classification before routing; read `self.state.last_intent` in `route_turn()`.
Set `default_intents` and `intent_llm`. Each `handle_turn()` pre-classifies the current message. A non-empty result returned by a custom `route_turn()` takes precedence; otherwise `route_conversation` uses the current turn's classified intent.
### B. Classify inside `route_turn` (richer prompts)
@@ -233,24 +223,15 @@ Use **`@listen("RESEARCH")`** (or similar) for steps that run `Agent.kickoff()`
## When the flow finishes but the user keeps chatting
`FlowFinished` means **this graph run** completed. The conversation continues with another `handle_turn()` and the same `session_id`. `@persist` restores `messages`, flags, and context.
Each `handle_turn()` completes one graph run, and the conversation continues with another `handle_turn()` using the same `session_id`. With the default deferred trace lifecycle, that run emits `conversation_turn_completed`, while `FlowFinished` is emitted once when `finalize_session_traces()` closes the session. `@persist` restores `messages`, flags, and context.
**Persist pattern:** prefer `@persist` on a **single terminal step** (for example `finalize`) rather than on the whole `Flow` class. Class-level persist saves after every method; `load_state` uses the latest row, which may be a mid-run snapshot (for example right after `bootstrap`) and miss handler updates from the same turn.
Do **not** use `@human_feedback` for follow-up chat lines unless a human must approve a specific step output before it is shown.
## Conversational `Flow` (experimental)
## Conversational `Flow`
<Warning>
**This is an experimental feature.** The conversational `Flow` surface
`RouterConfig`, `ConversationState`, the built-in graph + helpers) lives
under `crewai.experimental` and may change shape before it graduates.
Pin your CrewAI version if you depend on specific behavior, and watch the
changelog for breaking updates. Open issues / feedback welcome.
</Warning>
Opt into the conversational chat graph by setting `conversational = True` on a `Flow` subclass. The base `Flow` then ships a built-in `@start` / `@router` / `converse_turn` / `end_conversation` graph, manages `state.messages`, can drive a router LLM, and keeps the trace batch open across turns. You write the **custom routes**; the framework owns the rest.
Opt into the conversational chat graph by setting `conversational = True` on a `Flow` subclass or applying `@ConversationConfig(...)`. The base `Flow` then supplies `route_conversation` as the built-in start/router plus the `converse_turn` and `end_conversation` listeners. The deprecated `answer_from_history_turn` listener remains available for compatibility. The framework manages `state.messages`, can drive a router LLM, and keeps the trace batch open across turns. You write the **custom routes**; the framework owns the rest.
Use this when you want a multi-turn chat with a router and per-route handlers without wiring the lifecycle yourself. Use `Flow[ChatState]` (the lower-level pattern above) when you need full control.
@@ -259,7 +240,7 @@ Use this when you want a multi-turn chat with a router and per-route handlers wi
```python
from crewai import Flow
from crewai.flow import listen
from crewai.experimental.conversational import (
from crewai.flow import (
ConversationConfig,
ConversationState,
)
@@ -267,8 +248,6 @@ from crewai.experimental.conversational import (
message = (self.state.current_user_message or "").lower()
if "search" in message or "news" in message:
@@ -318,14 +297,26 @@ Class decorator that attaches per-class chat defaults.
|-------|---------|---------|
| `system_prompt` | `slices.conversational_system_prompt` from i18n | System message used by the built-in `converse_turn`. Pass `""` to opt out entirely. |
| `llm` | `None` | Conversation LLM (used by `converse_turn` and as router fallback). |
| `router` | `None` | `RouterConfig` for LLM-driven routing. Without it, the flow always falls through to `converse`. |
| `answer_from_history_prompt` | Framework default | System message for the optional `answer_from_history` route. |
| `answer_from_history_llm` | `None` | Enables the `answer_from_history` short-circuit when set. |
| `router` | `None` | Optional `RouterConfig` overrides. With custom listeners and a resolvable LLM, routing auto-enables even when this is omitted. |
| `answer_from_history_prompt` | Framework default | **Deprecated.** Use the `converse` system prompt or override `converse_turn()`. |
| `answer_from_history_llm` | `None` | **Deprecated.** Use `llm`; `converse` already receives canonical history. |
| `visible_agent_outputs` | `None` | `"all"`, or a list of agent names whose `append_agent_result()` calls should be promoted to public assistant messages. |
| `defer_trace_finalization` | `True` | Keep one trace batch open across `handle_turn()` calls. |
<Warning>
`answer_from_history_prompt`, `answer_from_history_llm`, and the
`answer_from_history` route are deprecated and will be removed in a future
release. They duplicate `converse`, add an eligibility LLM call, and are
bypassed when the normal auto-router returns a route. Existing configurations
continue to work and emit `DeprecationWarning`.
</Warning>
With no custom routes, turns fall through to `converse`. With custom routes and a conversation/router LLM, the framework synthesizes a default `RouterConfig`; provide one explicitly only to customize its prompt, route list, descriptions, or fallback behavior. Setting `default_intents` uses the legacy pre-classification path instead.
If no conversation LLM is configured, the built-in `converse_turn` returns a configuration placeholder rather than generating an answer.
### `RouterConfig` and the auto-built route catalog
```python
@@ -334,7 +325,7 @@ from typing import Literal
from pydantic import BaseModel
from crewai import LLM
from crewai.experimental.conversational import RouterConfig
2. `Flow.builtin_route_descriptions[label]` — framework-canned text for `converse`, `end`, `answer_from_history` (phrased for the router LLM).
3. First non-empty line of the `@listen(label)` handler's docstring.
4. Empty (the route is listed without a description).
2. `Flow.builtin_route_descriptions[label]` — framework-canned text for `converse`, `end`, and the deprecated `answer_from_history` compatibility route (phrased for the router LLM).
3. The method's declared `description` (used by declarative flows and DSL projections).
4. First non-empty line of the `@listen(label)` handler's docstring.
5. Empty (the route is listed without a description).
So in practice, **adding a new route is `@listen("X")` + a one-line docstring**:
@@ -415,7 +407,7 @@ Routes:
|-------|---------|---------|
| `converse` | `converse_turn` | Default chat handler. Calls `ConversationConfig.llm` with the system prompt + canonical message history. |
| `end` | `end_conversation` | Sets `state.ended = True` and emits a terminator reply. |
| `answer_from_history` | `answer_from_history_turn` | Optional. Routes here when `ConversationConfig.answer_from_history_llm` is set and the message can be answered from existing history. |
| `answer_from_history` | `answer_from_history_turn` | **Deprecated compatibility route.** Use `converse`, which already receives canonical history. |
You can override any of these by defining a same-named handler in your subclass.
@@ -425,9 +417,9 @@ You can override any of these by defining a same-named handler in your subclass.
1. Resets per-execution tracking (`_completed_methods`, `_method_outputs`) so the graph re-runs — without this, repeated `kickoff` calls on the same flow instance would short-circuit on turn 2+ because `Flow.kickoff_async` treats `inputs={"id": ...}` as a checkpoint restore.
2. Appends the user message to `state.messages`, sets `current_user_message` / `last_user_message`. `last_intent` is **preserved from the prior turn** so the router LLM can use it as a signal.
3. Runs `conversation_start` → `route_conversation` → the chosen `@listen` handler.
3. Runs user-defined `@start` methods (if any), then `route_conversation` as the built-in start/router, then the chosen `@listen` handler. `route_conversation` invokes the overridable `conversation_start()` helper.
4. The router stores its decision in `state.last_intent` (visible to the next turn's router context).
5. If your handler returned a string and didn't already call `append_assistant_message`, `handle_turn` appends it for you.
5. If your handler returned a string and didn't already call `append_assistant_message`, `handle_turn` appends it for you and persists the updated `state.messages` so `@persist` restore includes the assistant turn.
Call `handle_turn()` for chat messages. Calling `kickoff(inputs={"id": ...})` directly runs the flow graph without applying the conversational turn wrapper.
@@ -448,6 +440,8 @@ It handles the common local loop:
4. Prints the assistant result.
5. Finalizes deferred session traces in a `finally` block.
`chat(defer_trace_finalization=True)` temporarily enables the instance deferral flag for the REPL and restores its prior value on exit.
Customize the terminal behavior with injectable I/O:
```python
@@ -469,7 +463,7 @@ To run side effects (event bus setup, telemetry) on every routing decision, over
from typing import Any
from crewai import Flow
from crewai.experimental.conversational import ConversationState
from crewai.flow import ConversationState
class SupportFlow(Flow[ConversationState]):
@@ -480,7 +474,7 @@ class SupportFlow(Flow[ConversationState]):
return super().route_turn(context)
```
To bypass the LLM router entirely and pick a route programmatically, return a string from `route_turn`; returning `None` falls back to `_route_with_config(...)`.
To bypass the LLM router entirely and pick a route programmatically, return a non-empty string from `route_turn`. A falsy return does **not** invoke `_route_with_config()` from your override; routing falls through to this turn's pre-classified intent, then the deprecated `answer_from_history` compatibility path when configured, and finally `converse`. A previous turn's `last_intent` is available in router context but is never replayed as a fallback.
### `append_assistant_message` and `append_agent_result`
@@ -491,6 +485,73 @@ Inside a `@listen(label)` handler, choose:
`ConversationConfig.visible_agent_outputs` can promote specific agents' private results to public globally (`"all"`, or a list of agent names).
## Declaring a conversational flow in JSON/YAML
A [declarative Flow](/edge/en/concepts/cli) can be conversational too. Add a top-level `conversational` block and declare your own routes as methods that `listen` to a route label:
```yaml
schema: crewai.flow/v1
name: SupportFlow
conversational:
system_prompt: You are a terse support assistant.
llm: gpt-4o-mini
router:
llm: gpt-4o-mini
methods:
handle_order:
description: Order status, shipping and delivery questions.
listen: order
do:
call: agent
with:
role: Support specialist
goal: Answer order questions accurately
backstory: Knows the fulfilment pipeline.
input: "${state.current_user_message}"
```
Declaring the block is the opt-in — `enabled` defaults to `true`. Set `enabled: false` to keep the configuration while turning chat off. This also disables built-in method synthesis, so the declaration must provide a normal non-conversational graph.
Three things are supplied for you:
| Supplied | Detail |
|----------|--------|
| The built-in graph | `route_conversation`, `converse_turn`, and `end_conversation` are added automatically. Deprecated `answer_from_history_turn` is retained for compatibility. Declare a method under one of those names to override it. |
| Conversation state | `ConversationState` is used when there is no `state` block. A Pydantic `ref` or `json_schema` state is automatically composed with the conversational fields; it does not need to extend `ConversationState`. |
| The route catalog | Inferred from non-router methods with `listen` labels, excluding internal routes. Descriptions follow the precedence above, and explicit `router.routes` can limit the choices. |
Declarative `llm`, `router.llm`, and `intent_llm` fields accept either a model id or a configuration mapping such as `{model: openai/gpt-4o-mini, max_tokens: 512}`. The `conversational` block also supports `default_intents`, `visible_agent_outputs`, `defer_trace_finalization`, and the `RouterConfig` fields shown above. Deprecated `answer_from_history_prompt` / `answer_from_history_llm` declarations remain accepted for compatibility.
Run it from Python with the same turn APIs as a class-based conversational Flow:
```python
from crewai.flow import Flow
flow = Flow.from_declaration(path="flow.yaml")
try:
flow.handle_turn("Where is my order?", session_id="session-1")
finally:
flow.finalize_session_traces()
```
### Naming routes
Route labels and method names share one trigger namespace, so a handler must not be named after the route it listens to — `create_video` listening to `create_video` is rejected when the flow is built. Use a `handle_*` prefix.
### What a declaration cannot express
| Not expressible | Use instead |
|-----------------|-------------|
| A live `LLM` instance or a custom `BaseLLM` | A model id string or static configuration mapping |
| `router.response_format` as a live model class | Name the class with a python ref: `response_format: {python: my_project.schemas.ConversationRoute}`. Omit it and the framework synthesizes one |
| A `route_turn()` override | Author the Flow in Python, or replace the declarative `route_conversation` method with a `call: code` / expression action |
| A `can_answer_from_history()` override | Deprecated. Use `converse` or override `converse_turn()` in Python. |
`crewai run` opens the chat TUI for a declarative conversational flow — the same one a Python conversational Flow gets. A chat loop needs a terminal, so a headless run exits non-zero with guidance instead of running a single turn; drive it from Python there with `handle_turn()` or `stream_turn()`. A declarative method with a `human_feedback:` block (Python: `@human_feedback`) runs on a terminal REPL, because the runtime collects feedback with a blocking prompt the TUI cannot service. `--inputs` is not accepted for a conversational flow — each turn's input is the message you type — and resuming a session by id is not wired into the CLI yet; use `flow.handle_turn(message, session_id=...)` from Python for that.
## Tracing across turns
With `defer_trace_finalization=True` (default in `ConversationConfig`):
with `handle_turn()`, call `finalize_session_traces()` when
the session ends.
`suppress_flow_events=True` only hides Rich console panels; trace and method events still emit for observability.
`suppress_flow_events=True` hides Rich console panels and suppresses method execution events. Flow start/finish events still emit, so the outer Flow lifecycle remains traceable, but individual method spans are omitted.
### Conversational `Flow` trace lifecycle
The experimental [conversational `Flow`](#conversational-flow-experimental) uses the same tracing lifecycle: `defer_trace_finalization` defaults to `True`, so each `handle_turn()` keeps the session trace open. Always finalize at the end of the session — wrap your REPL/loop in `try/finally` and call `flow.finalize_session_traces()` on exit. Without it, the trace batch stays open and the final conversation may never export.
The [conversational `Flow`](#conversational-flow) uses the same tracing lifecycle: `defer_trace_finalization` defaults to `True`, so each `handle_turn()` keeps the session trace open. Deferred turns also suppress per-turn `flow_failed`; on a turn error or session abort, finalize the session explicitly. This closes the batch with the session-level `FlowFinished` event rather than a per-turn `FlowFailed` event. Always wrap your REPL/loop in `try/finally` and call `flow.finalize_session_traces()` on exit. Without it, the trace batch stays open and the final conversation may never export.
## Streaming
Set `stream = True` on the `Flow` class. `kickoff(...)` will then emit `assistant_delta` (and related) events through the standard event bus.
For conversational UIs, use `stream_turn()` and iterate its ordered `StreamFrame` objects:
```python
stream = flow.stream_turn("Where is my order?", session_id=session_id)
with stream:
for frame in stream.events:
if frame.channel == "llm" and frame.type == "llm_stream_chunk":
print(frame.content, end="", flush=True)
reply = stream.result
```
For a non-conversational Flow, setting `stream = True` makes `kickoff()` return a `StreamSession`. Do not set `flow.stream = True` when using `handle_turn()`; `stream_turn()` owns the conversational streaming lifecycle.
## Imports
@@ -531,10 +605,15 @@ from crewai.flow import (
router,
start,
)
from crewai.flow.conversation import prepare_conversational_turn
from crewai.flow import (
ConversationConfig,
ConversationState,
RouterConfig,
)
```
## See also
- [Mastering Flow State Management](/en/guides/flows/mastering-flow-state) — persistence, Pydantic state, `@persist`
- [Build Your First Flow](/en/guides/flows/first-flow) — flow basics
description: Run the same CrewAI agent as a chat bot on Slack and Discord with the CopilotKit Channels SDK.
icon: slack
description: Run the same CrewAI agent as a Slack or Teams bot with the CopilotKit Channels SDK and managed Intelligence platform.
icon: messages
mode: "wide"
---
## Meet your users where they already are
The CrewAI agent you built in the [Overview](/edge/en/guides/frontend/overview) does not have to live behind a web app. The same Crew or Flow can run as a bot inside a messaging platform. No rebuild, no second copy of your agent logic: the agent stays exposed over the [AG-UI protocol](https://docs.ag-ui.com), and a bot process drives it.
The CrewAI agent you built in the [Overview](/edge/en/guides/frontend/overview) does not have to live behind a web app. The same Crew or Flow can run as a bot inside a messaging platform. No rebuild, no second copy of your agent logic: the agent stays exposed over the [AG-UI protocol](https://docs.ag-ui.com), and a **channel** drives it from Slack or Microsoft Teams.
CopilotKit's [Channels SDK](https://docs.copilotkit.ai/reference/channels) provides that bot process. It ships a platform-agnostic engine plus per-platform adapters.
CopilotKit's [Channels SDK](https://docs.copilotkit.ai/slack) provides that channel. You declare a `createChannel` in a small runtime, point it at your CrewAI agent, and CopilotKit's managed **Intelligence** platform brokers the connection to the messaging provider.
<Note>
Unlike the rest of this section, Channels is **not self-hosted**. It runs through **CopilotKit Intelligence** — a required surface for Channels, by design (a free tier is available). Intelligence holds the platform connection and credentials, receives each platform event, and delivers the turn to your channel process; your process runs the agent and streams the reply back. You configure Slack once in the Intelligence dashboard, and platform credentials never enter your process. Your agent, tools, and state stay yours.
</Note>
## How it fits together
Nothing about your agent server changes. It keeps serving your Crew or Flow over AG-UI exactly as in the Overview. What you add is a separate **bot process**: it connects to a platform adapter, listens for messages, and runs your agent when it is messaged. The reply streams back into the channel.
Nothing about your CrewAI agent server changes. It keeps serving your Crew or Flow over AG-UI exactly as in the Overview. What you add is a separate long-running Node process built with `@copilotkit/channels`: it registers a channel on the `CopilotRuntime`, connects to Intelligence, and runs your agent whenever a message arrives.
```
Slack / Discord ──► Channels bot process ──► CrewAI server (AG-UI) ──► Crew / Flow
Slack / Teams ──► CopilotKit Intelligence ──► channel process (Node) ──► CrewAI server (AG-UI) ──► Crew / Flow
```
Your agent server can keep serving the web frontend from the Overview at the same time. The web app and the bot are just two clients of one AG-UI endpoint.
The channel process holds a persistent connection to the Intelligence gateway, so it needs a long-running host — a serverless request handler cannot own that connection. Your CrewAI server can keep serving the web frontend from the Overview at the same time: the web app and the channel are just two clients of one AG-UI endpoint.
## Slack
## Integration guide
<Steps>
<Step title="Install the Channels packages">
The Channels SDK is batteries-included — every platform ships in the one package, with no per-platform adapter to install. Add it alongside the runtime that hosts the channel and the CrewAI AG-UI client:
Create an app in the Slack API dashboard for your workspace, enable Socket Mode, and grant it the message and event scopes it needs to read and post in channels. Then expose its tokens to the bot process:
In the [CopilotKit dashboard](https://docs.copilotkit.ai/slack), create a Channel and connect Slack — Intelligence walks you through creating the Slack app and holds its credentials. That leaves two environment variables for your process, both from the dashboard:
export INTELLIGENCE_API_KEY=... # authenticates the runtime with Intelligence (free tier available)
export INTELLIGENCE_CHANNEL_ID=... # the Channel ID, matched by createChannel({ name })
```
</Step>
<Step title="Point the bot at your CrewAI agent">
<Step title="Define the channel">
`createBot` wires a Slack adapter to your agent. The `agent` factory returns a `CrewAIAgent` pointed at the AG-UI path your server exposes (the same URL you registered in the runtime in the Overview).
`createChannel` declares the channel and attaches your agent. Build the agent as a per-thread factory so each conversation gets its own session, using the same `CrewAIAgent` the Overview uses in the web runtime, pointed at your AG-UI endpoint. `identifyUser: "platform"` lets Intelligence map each platform user to a stable identity.
```ts
// bot.ts
import { createBot } from "@copilotkit/channels";
import { slack, defaultSlackTools, defaultSlackContext } from "@copilotkit/channels-slack";
// channel.ts
import { createChannel } from "@copilotkit/channels";
agent: (threadId) => new CrewAIAgent({ url: "http://localhost:8000/recipe" }),
tools: [...defaultSlackTools],
context: [...defaultSlackContext],
const channel = createChannel({
name: process.env.INTELLIGENCE_CHANNEL_ID!, // must match the Channel ID in Intelligence
identifyUser: "platform",
// A fresh agent per conversation, pointed at your CrewAI AG-UI endpoint.
agent: (threadId) => {
const agent = new CrewAIAgent({ url: "http://localhost:8000/recipe" });
agent.threadId = threadId;
return agent;
},
});
bot.start();
// A mention subscribes the thread and runs the agent; afterwards every message
// in a subscribed thread runs it without needing another mention.
channel.onMention(async ({ thread }) => {
await thread.subscribe();
await thread.runAgent();
});
channel.onMessage(async ({ thread }) => {
if (await thread.isSubscribed()) await thread.runAgent();
});
export { channel };
```
</Step>
<Step title="Run the bot">
<Step title="Register the channel on the runtime">
Start the bot process alongside your agent server:
Create a `CopilotRuntime` with the Intelligence gateway and your channel, then serve it with `createCopilotNodeListener`. The `agents` map stays empty — the channel supplies its own agent. Wait for the channel to be ready so a broken config fails startup loudly.
```ts
// server.ts
import { createServer } from "node:http";
import { CopilotRuntime, CopilotKitIntelligence } from "@copilotkit/runtime/v2";
import { createCopilotNodeListener } from "@copilotkit/runtime/v2/node";
import { channel } from "./channel";
const runtime = new CopilotRuntime({
agents: {}, // the channel supplies its own agent; no web-facing agents needed
intelligence: new CopilotKitIntelligence({
apiKey: process.env.INTELLIGENCE_API_KEY!, // free tier available
Message the bot in Slack and it runs your Crew or Flow, streaming the reply back into the thread.
Mention the bot in Slack or Teams and it runs your Crew or Flow, streaming the reply back into the thread. The thread stays subscribed, so follow-up messages run without another mention.
</Step>
</Steps>
<Note>
Slack app scopes, Socket Mode setup, and the full adapter options are maintained by CopilotKit. Follow the [Slack channel reference](https://docs.copilotkit.ai/reference/channels/slack) together with Slack's own app setup guide for the authoritative steps.
</Note>
## The event model
## Discord
A channel reacts to platform events with handlers, and each handler receives a `thread` you drive with a few methods:
Discord uses the same `createBot` engine with the Discord adapter from `@copilotkit/channels-discord`:
- **`channel.onMention`** fires when a user @-mentions the bot. Call `thread.subscribe()` to join the thread, then `thread.runAgent()` to run your CrewAI agent on the mention.
- **`channel.onMessage`** fires on every message in a thread the bot can see. Gate it with `thread.isSubscribed()` so the agent only responds where it has joined, then `thread.runAgent()`.
- **`thread.runAgent()`** runs the attached CrewAI agent for the current turn and streams its output back into the channel. Pass `{ prompt }` to override the text the agent runs on.
```ts
import { createBot } from "@copilotkit/channels";
import { discord } from "@copilotkit/channels-discord";
agent: (threadId) => new CrewAIAgent({ url: "http://localhost:8000/recipe" }),
});
bot.start();
```
See the [Discord channel reference](https://docs.copilotkit.ai/reference/channels/discord) for the exact adapter options and bot setup.
Your agent receives an ordinary AG-UI `RunAgentInput` and emits ordinary AG-UI events; the platform mechanics stay behind the channel, so the same Crew or Flow runs unchanged across every platform. The channel also exposes handlers for welcomes, interrupts, commands, reactions, and modals — see the [`Channel` reference](https://docs.copilotkit.ai/reference/channels/classes/Channel) for the full surface.
## Platform support
Slack and Discord have official Channels adapters (`@copilotkit/channels-slack`, `@copilotkit/channels-discord`). Microsoft Teams is available through CopilotKit's managed offering (currently waitlisted). Check the [Channels reference](https://docs.copilotkit.ai/reference/channels) for the current list before promising a platform.
The managed Intelligence path covers **Slack** and **Microsoft Teams** today — the same channel code runs on either, and `message.platform` / `thread.platform` report the native origin. Other platforms (Discord, Telegram, WhatsApp) are reached through developer-operated **direct adapters** rather than the managed path — your own process holds the platform credentials and transport. Check the [CopilotKit Channels documentation](https://docs.copilotkit.ai/slack) for the current platform list and per-platform setup.
This guide demonstrates how to integrate **Arize Phoenix** with **CrewAI** using OpenTelemetry via the [OpenInference](https://github.com/openinference/openinference) SDK. By the end of this guide, you will be able to trace your CrewAI agents and easily debug your agents.
This guide demonstrates how to integrate **Arize Phoenix** with **CrewAI** using OpenTelemetry via the [OpenInference](https://github.com/openinference/openinference) SDK. By the end of this guide, you will be able to trace your CrewAI agents and debug agent behavior.
> **What is Arize Phoenix?** [Arize Phoenix](https://phoenix.arize.com) is an LLM observability platform that provides tracing and evaluation for AI applications.
> **What is Arize Phoenix?** [Arize Phoenix](https://arize.com/phoenix/) is the open-source observability and evaluation option from [Arize AI](https://arize.com/?utm_source=crewai-docs&utm_medium=partner&utm_campaign=partner-docs&utm_content=observability-arize-phoenix). Use Phoenix when you want to run locally or self-host. Use [Arize AX](https://arize.com/products/ax/) for a managed cloud or enterprise self-hosted platform for production AI systems.
[](https://www.youtube.com/watch?v=Yc5q3l6F7Ww)
Setup Phoenix Cloud API keys and configure OpenTelemetry to send traces to Phoenix. Phoenix Cloud is a hosted version of Arize Phoenix, but it is not required to use this integration.
Configure your Phoenix API key and OpenTelemetry endpoint to send traces to Phoenix. The same setup works with a local or self-hosted Phoenix endpoint by changing the collector URL.
You can get your free Serper API key [here](https://serper.dev/).
@@ -35,8 +35,8 @@ You can get your free Serper API key [here](https://serper.dev/).
import os
from getpass import getpass
# Get your Phoenix Cloud credentials
PHOENIX_API_KEY = getpass("🔑 Enter your Phoenix Cloud API Key: ")
# Get your Phoenix API key
PHOENIX_API_KEY = getpass("🔑 Enter your Phoenix API key: ")
# Get API keys for services
OPENAI_API_KEY = getpass("🔑 Enter your OpenAI API key: ")
@@ -44,7 +44,7 @@ SERPER_API_KEY = getpass("🔑 Enter your Serper API key: ")
os.environ["PHOENIX_COLLECTOR_ENDPOINT"] = "https://app.phoenix.arize.com" # Phoenix Cloud, change this to your own endpoint if you are using a self-hosted instance
os.environ["PHOENIX_COLLECTOR_ENDPOINT"] = "https://app.phoenix.arize.com" # Change this to your own endpoint if you are using a self-hosted instance
os.environ["OPENAI_API_KEY"] = OPENAI_API_KEY
os.environ["SERPER_API_KEY"] = SERPER_API_KEY
```
@@ -133,7 +133,7 @@ print(result)
After running the agent, you can view the traces generated by your CrewAI application in Phoenix. You should see detailed steps of the agent interactions and LLM calls, which can help you debug and optimize your AI agents.
Log into your Phoenix Cloud account and navigate to the project you specified in the `project_name` parameter. You'll see a timeline view of your trace with all the agent interactions, tool usages, and LLM calls.
Open your Phoenix project and navigate to the project you specified in the `project_name` parameter. You'll see a timeline view of your trace with all the agent interactions, tool usages, and LLM calls.

@@ -147,6 +147,9 @@ Log into your Phoenix Cloud account and navigate to the project you specified in
### References
- [Phoenix Documentation](https://docs.arize.com/phoenix/) - Overview of the Phoenix platform.
- [Arize AX](https://arize.com/products/ax/) - Managed cloud and enterprise self-hosted observability and evaluation.
- [Arize agent evaluation guide](https://arize.com/guides/ai-agent-handbook/agent-evaluation/) - Production workflow for evaluating agent behavior from traces.
- [Arize LLM evaluation guide](https://arize.com/resources/llm-evaluation/) - Methods and metrics for evaluating LLM applications.
- [CrewAI Documentation](https://docs.crewai.com/) - Overview of the CrewAI framework.
CrewAI provides built-in tracing capabilities that allow you to monitor and debug your Crews and Flows in real-time. This guide demonstrates how to enable tracing for both **Crews** and **Flows** using CrewAI's integrated observability platform.
> **What is CrewAI Tracing?** CrewAI's built-in tracing provides comprehensive observability for your AI agents, including agent decisions, task execution timelines, tool usage, and LLM calls - all accessible through the [CrewAI AMP platform](https://app.crewai.com).
> **What is CrewAI Tracing?** CrewAI's built-in tracing provides comprehensive observability for your AI agents, including agent decisions, task execution timelines, tool usage, and LLM calls - all accessible through the [CrewAI AMP platform](https://app.crewai.com). Tracing is managed independently from [telemetry](/en/telemetry).
### Step 5: View Traces in the CrewAI AMP Dashboard
After running the crew or flow, you can view the traces generated by your CrewAI application in the CrewAI AMP dashboard. You should see detailed steps of the agent interactions, tool usages, and LLM calls.
Just click on the link below to view the traces or head over to the traces tab in the dashboard [here](https://app.crewai.com/crewai_plus/trace_batches)
Traces are uploaded only after a successful authenticated export or an explicitly approved anonymous upload. A run whose local buffer is discarded has no uploaded trace.
For traces associated with your account, open the [Traces tab in the CrewAI AMP dashboard](https://app.crewai.com/crewai_plus/trace_batches) to view agent interactions, tool usage, and LLM calls.
When this environment variable is set, all Crews and Flows will automatically have tracing enabled, even without explicitly setting `tracing=True`.
## Viewing traces after your first run
The first time you run a Crew or Flow, an interactive terminal may ask:
```text
Share this execution trace with CrewAI? [y/N]
```
Choose **yes** to upload the buffered trace to CrewAI. Traces may contain
prompts, inputs, and outputs. Declining, timing out, or running without an
interactive consent prompt discards the buffer. You can change tracing later
with `crewai traces enable` or `crewai traces disable`, or by setting `tracing`
on the Crew or Flow.
### Local buffering and authenticated export
First-run trace collection stays in process memory until you agree to share,
even if you have saved login credentials. Unauthenticated tracing uses the same
consent flow. Before consent, CrewAI requests no upload grant and sends no
execution spans.
The buffer retains up to **1,000 spans** and **8 MiB of encoded OTLP data**.
Set `CREWAI_EPHEMERAL_TRACE_MAX_SPANS` and
`CREWAI_EPHEMERAL_TRACE_MAX_BYTES` to positive integers to adjust these limits.
Overflow drops the oldest spans; a span larger than the byte limit is dropped.
The buffer is cleared after sharing or discarding it.
When tracing is enabled and credentials are available, CrewAI exchanges your
CLI login, `CREWAI_USER_PAT`, or platform integration credential with AMP for
an execution-specific grant. It then exports OpenTelemetry spans directly to
Wharf using that grant. Invalid credentials do not fall back to anonymous upload.
### Hosted execution sessions
Hosts can wrap execution with `telemetry_session` from
`crewai.telemetry.tracing`. The session uses CrewAI lifecycle events to create
and finish spans, preserving their timestamps, parent relationships, and HITL
pause/resume links. Pass an existing provider with `providers=` to retain the
host's tracer and logging integration. Pass span processors with `processors=`
and a host logging callback with `log_emitter=`. The host owns any redaction
in these integrations.
Each session owns its tracing lifecycle and leaves the application's global
OpenTelemetry provider unchanged.
## Viewing Your Traces
### Access the CrewAI AMP Dashboard
@@ -210,5 +254,5 @@ If traces aren't showing up in the dashboard:
1. Confirm `tracing=True` is set in your Crew/Flow
2. Check that `CREWAI_TRACING_ENABLED=true` if using environment variables
3. Ensure you're authenticated with `crewai login`
4. Verify your crew/flow is actually executing
3. For authenticated export, verify your CLI login, `CREWAI_USER_PAT`, or platform integration credential. For anonymous sharing, explicitly approve the consent prompt; login is not required
4. Verify your crew/flow executed and the trace export succeeded. Declining consent, timing out, or running without an interactive consent prompt discards the local buffer without uploading it
@@ -23,7 +23,8 @@ usage of tools, API calls, responses, any data processed by the agents, or secre
When the `share_crew` feature is enabled, detailed data including task descriptions, agents' backstories or goals, and other specific attributes are collected
to provide deeper insights. This expanded data collection may include personal information if users have incorporated it into their crews or tasks.
Users should carefully consider the content of their crews and tasks before enabling `share_crew`.
Users can disable telemetry by setting the environment variable `CREWAI_DISABLE_TELEMETRY` to `true` or by setting `OTEL_SDK_DISABLED` to `true` (note that the latter disables all OpenTelemetry instrumentation globally).
Users can disable CrewAI telemetry by setting `CREWAI_DISABLE_TELEMETRY` to `true`, `1`, `yes`, or `on` (any case). `OTEL_SDK_DISABLED` with the same values also disables CrewAI's exporter. The OpenTelemetry SDK itself still only honors `true` for disabling other instrumentation in the process.
AMP tracing is covered separately in [Tracing](/en/observability/tracing).
| Yes | CrewAI and Python Version | Tracks software versions. Example: CrewAI v1.2.3, Python 3.8.10. No personal data. |
| Yes | Crew Metadata | Includes: randomly generated key and ID, process type (e.g., 'sequential', 'parallel'), boolean flag for memory usage (true/false), count of tasks, count of agents. All non-personal. |
| Yes | Crew Metadata | Includes: randomly generated key and ID, process type (e.g., 'sequential', 'parallel'), boolean flag for memory usage (true/false), a boolean flag for whether any inputs were passed to the run (true/false — never the input keys or values, which are only collected when `share_crew` is enabled), count of tasks, count of agents. All non-personal. |
| Yes | Agent Data | Includes: randomly generated key and ID, role name (should not include personal info), boolean settings (verbose, delegation enabled, code execution allowed), max iterations, max RPM, max retry limit, LLM info (see LLM Attributes), list of tool names (should not include personal info). No personal data. |
| Yes | Task Metadata | Includes: randomly generated key and ID, boolean execution settings (async_execution, human_input), associated agent's role and key, list of tool names. All non-personal. |
| Yes | Tool Usage Statistics | Includes: tool name (should not include personal info), number of usage attempts (integer), LLM attributes used. No personal data. |
| Yes | Test Execution Data | Includes: crew's randomly generated key and ID, number of iterations, model name used, quality score (float), execution time (in seconds). All non-personal. |
| Yes | Task Lifecycle Data | Includes: creation and execution start/end times, crew and task identifiers. Stored as spans with timestamps. No personal data. |
| Yes | Task Lifecycle Data | Includes: creation and execution start/end times, crew and task identifiers, and whether the task succeeded or failed. When a task fails, the **class name** of the exception is recorded (for example `TimeoutError`) so failures can be counted and diagnosed — never the error message, which can contain prompts, model output, file paths or credentials. Stored as spans with timestamps. No personal data. |
| Yes | LLM Attributes | Includes: name, model_name, model, top_k, temperature, and class name of the LLM. All technical, non-personal data. |
| Yes | Crew Deployment attempt using crewAI CLI | Includes: The fact a deploy is being made and crew id, whether it's trying to pull logs, and whether the deploy was started from a CLI command or from the run TUI. No project or crew contents. No personal data. |
| Yes | Execution Environment | Includes: which AI coding assistant is running the process, if any (one of a fixed list such as `claude_code`, `codex`, `cursor`, or `unknown`), where the process runs (one of a fixed list such as `ci`, `container`, `serverless`, `interactive`), and the `project_id` from your `pyproject.toml` when one is configured. Detection reads only whether known environment variables are set, never their values. No personal data. |
| Yes | Project Creation using crewAI CLI | Includes: that a new project was scaffolded by `crewai create`, which kind it was (`crew`, `json_crew` or `flow`), and the project ID minted for that new project and written into its own `pyproject.toml`. That is the new project's own ID, recorded separately from the `project_id` of the directory the command was run from — the two can differ. No project name, no file contents, no code. No personal data. |
| Yes | Crew Deployment attempt using crewAI CLI | Includes: The fact a deploy is being made and crew id, whether it's trying to pull logs, and whether the deploy was started from a CLI command or from the run TUI. If creating a deployment fails, the failure category (one of a fixed list such as `api_4xx`, `network_error` or `user_declined`) and the HTTP status code of the API response, when there was one, are recorded — never the error message. No project or crew contents. No personal data. |
| Yes | Execution Environment | Includes: which AI coding assistant is running the process, if any (one of a fixed list such as `claude_code`, `codex`, `cursor`, or `unknown`), where the process runs (one of a fixed list such as `ci`, `container`, `serverless`, `interactive`), the `project_id` from your `pyproject.toml` when one is configured, and a coarse size band for the machine (one of `1-2`, `3-4`, `5-8`, `9-16`, `17-32`, `33+`, or `unknown`). The band is a range, never the exact core count — the exact count is opt-in only, under Environment Information below. The size band comes from the host CPU count; assistant and location detection reads only whether known environment variables are set, never their values. No personal data. |
| Yes | Flow Lifecycle Signals | Includes: that a flow started, whether it completed or failed, whether one of its methods failed, whether it paused for human input or feedback, whether the start was a resumed run, whether a conversation turn failed, how long the flow ran, and whether the flow is one CrewAI runs internally or one you wrote. The flow name is recorded, as it already is for flow creation and execution. When a flow or one of its methods fails, the **class name** of the exception is recorded (for example `TimeoutError`) so that failures can be diagnosed — never the error message, which can contain prompts, model output, file paths or credentials. Method names and flow state are never recorded. No personal data. |
| Yes | Trace Sharing Signal | Includes: that a batch of traces was successfully shared with CrewAI AMP, and whether it was shared anonymously (before you have an account) or linked to your account. Like every span, it also carries the Execution Environment attributes described above (`project_id` when configured, the coding assistant, and the runtime). This row describes sharing telemetry only — not the trace contents or access granted by shared trace links. Trace contents, inputs, and outputs are never recorded on this signal. Before sharing traces, review secrets, personal data, and AMP redaction and retention settings. |
| No | Agent's Expanded Data | Includes: goal description, backstory text, i18n prompt file identifier. Users should ensure no personal info is included in text fields. |
This tool is used to extract text from images. When passed to the agent it will extract the text from the image and then use it to generate a response, report or any other output.
The URL or the PATH of the image should be passed to the Agent.
You can also ask a custom `query` about the image and pick a `complexity_level` that automatically selects the model best suited for the request:
| Complexity level | Model |
| :--------------- | :------------ |
| `easy` | `gpt-5.6-luna` |
| `medium` (default) | `gpt-5.6-terra` |
| `hard` | `gpt-5.6-sol` |
When an explicit `llm` or `model` is provided to the tool, it takes precedence over the complexity-based model selection.
| **image_path_url** | `string` | **Mandatory**. The path to the image file (or URL) from which text needs to be extracted. |
| **query** | `string` | **Optional**. The question or instruction to ask the model about the image. Defaults to `"What's in this image?"`. |
| **complexity_level** | `string` | **Optional**. The complexity of the request, which selects the model: `easy`, `medium`, or `hard`. Defaults to `medium`. |
@@ -77,4 +77,4 @@ To let an agent read a directory tree outside the working directory, point `base
file_read_tool = FileReadTool(base_dir='/data')
```
As a last resort, setting `CREWAI_TOOLS_ALLOW_UNSAFE_PATHS=true` disables path validation. This applies process-wide to every crewai-tools tool, including the SSRF protections on URL-fetching tools, so prefer `base_dir`.
As a last resort, setting `CREWAI_TOOLS_ALLOW_UNSAFE_PATHS=true` disables path validation. This applies process-wide to every crewai-tools tool, including the SSRF protections on URL-fetching tools, so prefer `base_dir`. Managed workers should set `CREWAI_TOOLS_FORCE_SAFE_PATHS=true` so a tenant cannot disable those checks by exporting the escape hatch.
The `ScrapeElementFromWebsiteTool` is designed to extract specific elements from websites using CSS selectors. This tool allows CrewAI agents to scrape targeted content from web pages, making it useful for data extraction tasks where only specific parts of a webpage are needed.
The `ScrapeElementFromWebsiteTool` is designed to extract specific elements from websites using CSS selectors. This tool allows CrewAI agents to scrape targeted content from web pages, making it useful for data extraction tasks where only specific parts of a webpage are needed. Fetches go through CrewAI's SSRF-safe HTTP helper: the requested URL and every redirect hop are checked against private and reserved ranges (including cloud metadata), and the TCP connection is pinned to an IP that passed that check.
A tool designed to extract and read the content of a specified website. It is capable of handling various types of web pages by making HTTP requests and parsing the received HTML content.
This tool can be particularly useful for web scraping tasks, data collection, or extracting specific information from websites.
Fetches go through CrewAI's SSRF-safe HTTP helper: the requested URL and every redirect hop are checked against private and reserved ranges (including cloud metadata), and the TCP connection is pinned to an IP that passed that check.
크루 프로젝트 내부에서는 스킬이 `./skills/{name}/`에 설치되고, 프로젝트 외부에서는 공유 캐시인 `~/.crewai/skills/{org}/{name}/`에 저장됩니다.
<Note>
조직 이름이 아니라 조직 **UUID**를 사용하세요 — 조직 이름은 고유하지 않아서 잘못된 조직으로 해석될 수 있고, 그러면 설치가 "찾을 수 없음" 오류로 실패합니다. `crewai org list`를 실행하면 소속된 각 조직의 UUID(`ID` 열)를 확인할 수 있습니다.
</Note>
크루 프로젝트 내부에서는 스킬이 `./skills/{name}/`에 설치되고, 프로젝트 외부에서는 공유 캐시인 `~/.crewai/skills/{org-uuid}/{name}/`에 저장됩니다.
에이전트는 레지스트리 스킬을 직접 참조할 수도 있습니다 — 런타임에 로컬 캐시(또는 프로젝트 `skills/` 디렉터리)에서 해석됩니다:
@@ -217,7 +221,7 @@ agent = Agent(
role="Senior Code Reviewer",
goal="Review pull requests for quality and security issues",
backstory="Staff engineer with expertise in secure coding practices.",
@@ -26,7 +26,7 @@ CrewAI의 기본 프롬프트는 많은 시나리오에서 잘 작동하지만,
- **오류 처리** – agent가 실패, 예외, 또는 타임아웃에 어떻게 반응할지 지정합니다.
- **도구별 prompt** – 도구가 호출되거나 사용되는 방법에 대한 상세 지침을 정의합니다.
이 요소들이 어떻게 구성되어 있는지 보려면 [CrewAI 저장소의 원본 prompt 템플릿](https://github.com/crewAIInc/crewAI/blob/main/src/crewai/translations/en.json)을 확인하세요. 여기서 필요에 따라 오버라이드하거나 수정하여 고급 동작을 구현할 수 있습니다.
이 요소들이 어떻게 구성되어 있는지 보려면 [CrewAI 저장소의 원본 prompt 템플릿](https://github.com/crewAIInc/crewAI/blob/main/lib/crewai/src/crewai/translations/en.json)을 확인하세요. 여기서 필요에 따라 오버라이드하거나 수정하여 고급 동작을 구현할 수 있습니다.
CrewAI CLI를 사용하여 프로젝트를 스캐폴딩하면, `AGENTS.md`가 루트에 자동으로 추가됩니다.
CrewAI CLI를 사용하여 프로젝트를 스캐폴딩하세요. `AGENTS.md`가 루트에 추가되며, 이를 임포트하는 `CLAUDE.md`와 `GEMINI.md`도 함께 추가되므로 Claude Code와 Gemini CLI가 다른 모든 어시스턴트와 동일한 안내를 읽습니다.
```bash
# Crew
@@ -32,24 +32,28 @@ Codex는 저장소에 배치된 `AGENTS.md` 파일로 안내할 수 있습니다
### Claude Code
Claude Code는 프로젝트 메모리를 `CLAUDE.md`에 저장합니다. `/init`으로 부트스트랩하고 `/memory`로 편집할 수 있습니다. Claude Code는 `CLAUDE.md` 내에서 임포트도 지원하므로, `@AGENTS.md`와 같은 한 줄을 추가하여 공유 지침을 중복 없이 가져올 수 있습니다.
Claude Code는 `CLAUDE.md`를 읽고 `AGENTS.md`는 무시합니다. 스캐폴딩된 프로젝트에는 임포트 줄 `@AGENTS.md` 하나만 담긴 `CLAUDE.md`가 포함되어 있어, 공유 안내가 중복 없이 로드됩니다. Claude 전용 메모는 그 줄 아래에 추가하고, 공유 컨벤션은 `AGENTS.md`에 유지하세요.
간단하게 다음과 같이 사용할 수 있습니다:
`CLAUDE.md`가 스캐폴딩되기 전에 생성된 프로젝트라면 임포트를 직접 추가하세요:
```bash
mv AGENTS.md CLAUDE.md
printf '@AGENTS.md\n' > CLAUDE.md
```
`AGENTS.md`를 `CLAUDE.md`로 이름을 바꾸지 마세요. Codex와 Cursor는 `AGENTS.md`를 읽으며, 이름을 바꾸면 이들에게 보이지 않게 됩니다.
### Gemini CLI와 Google Antigravity
Gemini CLI와 Antigravity는 저장소 루트 및 상위 디렉토리에서 프로젝트 컨텍스트 파일(기본값: `GEMINI.md`)을 로드합니다. Gemini CLI 설정에서 `context.fileName`을 설정하여 `AGENTS.md`를 대신(또는 추가로) 읽도록 구성할 수 있습니다. 예를 들어, `AGENTS.md`만 설정하거나 각 도구의 형식을 유지하고 싶다면 `AGENTS.md`와 `GEMINI.md`를 모두 포함할 수 있습니다.
Gemini CLI와 Antigravity는 저장소 루트 및 상위 디렉토리에서 프로젝트 컨텍스트 파일(기본값: `GEMINI.md`)을 로드합니다. 스캐폴딩된 프로젝트에는 임포트 줄 `@./AGENTS.md` 하나만 담긴 `GEMINI.md`가 포함되어 있어, 공유 안내가 중복 없이 로드됩니다. Gemini 전용 메모는 그 줄 아래에 추가하고, 공유 컨벤션은 `AGENTS.md`에 유지하세요.
간단하게 다음과 같이 사용할 수 있습니다:
`GEMINI.md`가 스캐폴딩되기 전에 생성된 프로젝트라면 임포트를 직접 추가하세요:
```bash
mv AGENTS.md GEMINI.md
printf '@./AGENTS.md\n' > GEMINI.md
```
또는 Gemini CLI 설정의 `context.fileName`에 `AGENTS.md`를 포함시키면 Gemini가 이를 직접 읽습니다. `AGENTS.md`를 `GEMINI.md`로 이름을 바꾸지 마세요. Codex와 Cursor는 `AGENTS.md`를 읽으며, 이름을 바꾸면 이들에게 보이지 않게 됩니다.
### Cursor
Cursor는 `AGENTS.md`를 프로젝트 지침 파일로 지원합니다. 프로젝트 루트에 배치하여 Cursor의 코딩 어시스턴트에 안내를 제공하세요.
| 사용자 입력 | `handle_turn(message)`가 그래프 실행 전 `state.messages`에 추가 |
| 턴 완료 | `FlowFinished`는 **이번 실행**만 의미; 다음 `handle_turn`로 대화 계속 |
| 턴 완료 | `conversation_turn_completed`; 기본 trace 지연을 사용하면 `FlowFinished`는 `finalize_session_traces()`까지 대기 |
| 세션 전체 트레이스 | `ConversationConfig(defer_trace_finalization=True)` + `finalize_session_traces()` |
## 턴 API
REST, WebSocket, 테스트, 커스텀 UI에서 오는 모든 사용자 메시지에는 **`flow.handle_turn(message, session_id=...)`**를 사용하세요. 대화형 `Flow`를 로컬 터미널 채팅 루프로 실행하고 싶을 때는 **`flow.chat()`**을 사용하세요.
`Flow.kickoff()`는 `user_message=` 또는 `session_id=` 키워드 인자를 받지 않습니다. 대화형 flow에서는 `handle_turn()`이 보류 중인 메시지를 저장하고 내부적으로 `kickoff(inputs={"id": session_id})`를 호출합니다.
`Flow.kickoff()`는 `user_message=` 또는 `session_id=` 키워드 인자를 받지 않습니다. 대화형 flow에서는 `handle_turn()`이 보류 중인 메시지를 저장하고 턴별 실행 상태를 초기화한 뒤 내부적으로 `kickoff(inputs={"id": session_id})`를 호출합니다.
| API | 용도 |
|-----|------|
| `handle_turn(message, session_id=...)` | 대화형 `Flow`용 한 턴 편의 래퍼 |
| `ChatSession.handle_turn(...)` | `handle_turn` 위의 전송 계층 (SSE / WebSocket) |
대화형 모드가 활성화되지 않으면 `handle_turn()`, `stream_turn()`, `chat()`은 `ValueError`를 발생시킵니다. `@ConversationConfig(...)`를 적용하면 자동으로 활성화되며, 그렇지 않으면 `conversational = True`로 설정하세요.
## 빠른 시작
@@ -38,7 +40,7 @@ from uuid import uuid4
from crewai import Flow
from crewai.flow import listen
from crewai.experimental.conversational import (
from crewai.flow import (
ConversationConfig,
ConversationState,
)
@@ -46,8 +48,6 @@ from crewai.experimental.conversational import (
flow.finalize_session_traces() # 전체 대화에 대한 단일 trace 링크
```
## 턴 스트리밍
UI나 런타임에서 한 채팅 턴의 구조화된 이벤트가 필요하면 `stream_turn()`을 사용하세요. Flow 라우팅, LLM chunk, tool 활동, 대화 메시지를 순서가 보장된 frame으로 제공하는 stream session을 반환합니다.
```python
stream = flow.stream_turn("Where is my order?", session_id=session_id)
with stream:
for frame in stream.events:
if frame.channel == "llm" and frame.type == "llm_stream_chunk":
print(frame.content, end="", flush=True)
result = stream.result
```
전체 frame 계약과 channel 목록은 [스트리밍 런타임 계약](/edge/ko/learn/streaming-runtime-contract)을 참고하세요.
## 턴 생명주기
각 `handle_turn`은 다음 파이프라인을 실행합니다:
1. **`_configure_conversational_kickoff`** — `session_id` / `user_message`를 `inputs`에 병합, `ConversationalConfig` 적용, 설정 시 지연 트레이싱 활성화.
1. **턴 설정** — 보류 중인 사용자 메시지를 저장하고 세션 id를 결정하며 턴별 실행 추적을 초기화한 뒤 `kickoff(inputs={"id": session_id})`를 호출.
2. **상태 복원** — `inputs["id"]`가 있고 `@persist`가 설정되면 최신 스냅샷 로드.
3. **`FlowStarted`** — 지연 세션의 첫 턴에서만 발생.
4. **`prepare_conversational_turn`** — 사용자 메시지를 `state.messages`에 추가, `last_user_message` 설정, `last_intent` 초기화, `intents` / `default_intents` + `intent_llm` 설정 시 분류.
4. **보류 중인 턴 수화** — 사용자 메시지를 `state.messages`에 추가하고 `current_user_message` / `last_user_message`를 설정하며, `intents` / `default_intents` + `intent_llm` 설정 시 선택적으로 분류.
5. **그래프 실행** — 사용자 정의 `@start` 메서드(있는 경우) → `route_conversation`(내장 start/router) → 선택된 `@listen` 핸들러. `route_conversation`은 재정의 가능한 `conversation_start()` 헬퍼도 호출합니다.
6. **실행 종료** — 지연 활성화 시 턴별 `flow_finished` 및 trace 종료 **건너뜀**; 중첩 `Agent.kickoff()` / crew도 부모 batch를 닫지 않음.
핸들러는 **`append_assistant_message(reply)`**를 호출해 다음 턴의 `conversation_messages`에 어시스턴트 응답이 포함되게 하세요. 사용자 입력은 `handle_turn`이 이미 저장합니다 — 핸들러에서 다시 추가하지 마세요.
핸들러는 보이는 응답이 반환값과 다를 때, 또는 히스토리를 자를 때 **`append_assistant_message(reply)`**를 호출하세요. public 문자열 반환값도 assistant로 기록되며 `@persist` 스냅샷에 포함되므로, 새 Flow 인스턴스에서도 복원됩니다. 사용자 입력은 `handle_turn`이 이미 저장합니다 — 핸들러에서 다시 추가하지 마세요.
`Flow` 서브클래스에 `ConversationConfig`를 데코레이터로 적용하면 채팅 기본값이 부착되고 대화형 모드도 활성화됩니다. 아래의 [전체 필드 레퍼런스](#conversationconfig)를 참고하세요. 턴마다 `handle_turn(..., intents=..., intent_llm=...)`로 사전 분류 설정을 재정의할 수 있습니다.
| 필드 | 기본값 | 목적 |
|------|--------|------|
| `default_intents` | `None` | kickoff 전 자동 분류용 outcome 라벨 |
| `intent_llm` | `None` | 분류용 모델 (intent 사용 시 필수) |
| `interactive_timeout` | `None` | 대화형 모드 줄 단위 타임아웃 |
| `exit_commands` | `exit`, `quit` | 대화형 모드 종료 단어 |
| `defer_trace_finalization` | `True` | 턴 간 하나의 trace batch 유지 |
## 하위 수준 `ChatState` 헬퍼
`intents=` 및 `intent_llm=` 키워드로 kickoff마다 재정의할 수 있습니다.
## `ChatState` (권장 persist 형태)
`ChatState`, 레거시 `ConversationalConfig`, `crewai.flow.conversation` 헬퍼는 고급 오케스트레이션, 테스트, 커스텀 래퍼에서 계속 import할 수 있습니다. 이들은 `ConversationState` / `ConversationConfig` API와 별개이며 `Flow.kickoff()`에 `user_message=` 또는 `session_id=` 키워드 인자를 추가하지 않습니다.
`ConversationState`는 `messages`를 `ConversationMessage` 객체로 저장하며 `current_user_message`, `ended`, `events`, `agent_threads`도 제공합니다. 정식 기록을 LLM에 전달할 때는 `conversation_messages`를 사용하세요.
## `Flow` 대화 API
### `kickoff` / `kickoff_async` 파라미터
### `handle_turn` 파라미터
| 파라미터 | 목적 |
|----------|------|
| `user_message` | 이번 턴 텍스트 (또는 `{"role": "user", "content": "..."}`) |
| `message` | 이번 턴의 텍스트 |
| `session_id` | 대화 UUID → `inputs["id"]` / `state.id` |
| `intents` | kickoff 전 `classify_intent`용 outcome 라벨 |
| `intents` | kickoff 전 `classify_intent`용 결과 라벨 |
| `intent_llm` | 분류 LLM (`intents`와 함께 필수) |
| `interactive` | `ask()` CLI 루프 (로컬 데모 전용) |
| `interactive_prompt` | 대화형 모드 프롬프트 |
| `interactive_timeout` | 줄 단위 `ask()` 타임아웃 |
| `exit_commands` | 대화형 모드 종료 단어 |
| `inputs` | 추가 상태 필드 |
| `restore_from_state_id` | 다른 persist flow에서 fork 복원 |
| `**kickoff_kwargs` | `input_files`, `from_checkpoint`, `restore_from_state_id` 같은 옵션을 `kickoff()`로 전달 |
### `kickoff` 파라미터
`Flow.kickoff()`는 `inputs`, `input_files`, `from_checkpoint`, `restore_from_state_id`를 받습니다. 원시 flow 실행이 필요하면 `inputs={"id": session_id}`를 전달할 수 있지만, 채팅 메시지를 나타내는 호출에는 `handle_turn()`을 사용하세요.
### 인스턴스 속성
| 속성 | 목적 |
|------|------|
| `conversational_config` | 클래스 수준 `ConversationalConfig` |
| `defer_trace_finalization` | 인스턴스 플래그; kickoff 시 config에서 자동 설정 |
| `receive_user_message(text, *, outcomes=None, llm=None)` | 사용자 메시지 추가; 선택적 `last_intent` |
| `finalize_session_traces()` | 지연 `flow_finished` 발생 및 세션 trace batch 종료 |
| `_should_defer_trace_finalization()` | 턴별 trace 종료 지연 여부 |
| `_should_defer_trace_finalization()` | 턴별 trace 종료 지연 여부를 결정하는 고급/내부 hook |
| `input_history` | `ask()` 프롬프트/응답 감사 기록 |
### 모듈 헬퍼 (`crewai.flow.conversation`)
테스트 또는 커스텀 오케스트레이션용:
테스트 또는 커스텀 오케스트레이션을 위해 `crewai.flow.conversation`에서 import할 수 있습니다. 이 헬퍼들은 레거시 `ConversationalConfig` 형태를 사용합니다. 또한 `prepare_conversational_turn()`은 `last_intent`를 지우지만, `handle_turn()`은 router 컨텍스트로 보존합니다.
| 함수 | 설명 |
|------|------|
| `normalize_kickoff_inputs(...)` | 대화 kwargs를 `inputs`에 병합 |
| `normalize_kickoff_inputs(inputs, user_message=..., session_id=...)` | 대화 kwargs를 `inputs`에 병합 |
| `get_conversation_messages(flow)` | 상태 또는 내부 버퍼에서 메시지 읽기 |
| `receive_user_message(flow, ...)` | 인스턴스 메서드와 동일 |
| `append_message(flow, role, content, **extra)` | 인스턴스 메서드와 동일 |
| `prepare_conversational_turn(flow, user_message=..., intents=..., intent_llm=..., config=...)` | 커스텀 래퍼용 하위 수준 턴 수화 |
| `receive_user_message(flow, text, ...)` | 인스턴스 메서드와 동일 |
| `set_state_field(flow, name, value)` | dict 또는 Pydantic 상태 필드 설정 |
| `get_conversational_config(flow)` | 클래스 `conversational_config` 읽기 |
| `input_history_to_messages(entries)` | `input_history`를 LLM 메시지 형식으로 |
## 의도 라우팅 패턴
### A. `ConversationalConfig`로 사전 분류 (가장 단순)
### A. `ConversationConfig`로 사전 분류 (가장 단순)
`default_intents`와 `intent_llm` 설정. 각 kickoff가 `@router` 전에 분류; `route()`에서 `self.state.last_intent` 읽기.
`default_intents`와 `intent_llm`을 설정하세요. 각 `handle_turn()`이 현재 메시지를 사전 분류합니다. 커스텀 `route_turn()`이 반환한 비어 있지 않은 결과가 우선하며, 그렇지 않으면 `route_conversation`이 현재 턴의 분류된 intent를 사용합니다.
llm=self.conversational_config.intent_llm or "gpt-4o-mini",
llm="gpt-4o-mini",
)
self.state.last_intent = intent
return intent
@@ -214,69 +223,59 @@ def route(self):
## flow가 끝났지만 사용자는 계속 대화할 때
`FlowFinished`는 **이번 그래프 실행**이 완료됨을 의미합니다. 같은 `session_id`로 또 다른 `kickoff`로 대화가 이어집니다. `@persist`가 `messages`, 플래그, 컨텍스트를 복원합니다.
각 `handle_turn()`은 하나의 그래프 실행을 완료하며, 같은 `session_id`로 다음 `handle_turn()`을 호출해 대화를 이어갑니다. 기본 지연 trace 수명 주기에서는 해당 실행이 `conversation_turn_completed`를 발생시키고, `finalize_session_traces()`가 세션을 닫을 때 `FlowFinished`가 한 번 발생합니다. `@persist`는 `messages`, 플래그, 컨텍스트를 복원합니다.
**Persist 패턴:** 전체 `Flow` 클래스보다 **단일 종료 스텝**(예: `finalize`)에 `@persist`를 두는 것이 좋습니다. 클래스 수준 persist는 매 메서드 후 저장하며, `load_state`는 최신 행을 사용해 같은 턴의 핸들러 업데이트를 놓칠 수 있습니다.
후속 채팅 줄에 `@human_feedback`를 쓰지 마세요. 특정 스텝 출력을 사람이 승인해야 할 때만 사용하세요.
## 대화형 `Flow` (실험적)
## 대화형 `Flow`
<Warning>
**실험적 기능입니다.** 대화형 `Flow`의 API 표면(`conversational = True`,
`Flow` 서브클래스에 `conversational = True`를 지정하면 대화형 챗 그래프가 활성화됩니다. 베이스 `Flow`가 `@start` / `@router` / `converse_turn` / `end_conversation` 그래프를 노출하고, `state.messages`를 관리하며, router LLM을 구동하고, 턴 간 trace 배치를 열린 상태로 유지합니다. 여러분은 **커스텀 라우트**만 작성하면 되고, 나머지는 프레임워크가 담당합니다.
`Flow` 서브클래스에 `conversational = True`를 지정하거나 `@ConversationConfig(...)`를 적용하면 대화형 채팅 그래프가 활성화됩니다. 베이스 `Flow`는 내장 start/router인 `route_conversation`과 `converse_turn`, `end_conversation` 리스너를 제공합니다. 사용 중단된 `answer_from_history_turn` 리스너는 호환성을 위해 계속 제공됩니다. 또한 `state.messages`를 관리하고 router LLM을 구동할 수 있으며 턴 간 trace batch를 열린 상태로 유지합니다. 여러분은 **커스텀 라우트**를 작성하고 나머지는 프레임워크에 맡기면 됩니다.
LLM 기반 라우터와 라우트별 핸들러로 멀티턴 챗을 만들고 싶지만 라이프사이클을 직접 배선하고 싶지 않을 때 사용하세요. 완전한 제어가 필요하면 위의 `Flow[ChatState]`로 내려가세요.
### 빠른 예제
```python
from crewai import LLM, Flow
from crewai import Flow
from crewai.flow import listen
from crewai.experimental.conversational import (
from crewai.flow import (
ConversationConfig,
ConversationState,
RouterConfig,
)
ROUTER_LLM = LLM(model="gpt-4o-mini")
@ConversationConfig(
system_prompt="A multi-agent assistant for ordinary chat and tool-backed tasks.",
llm=ROUTER_LLM,
router=RouterConfig(), # 라우트 + 설명은 @listen 핸들러에서 자동 발견
커스텀 라우트가 없으면 턴은 `converse`로 이어집니다. 커스텀 라우트와 대화/router LLM이 있으면 프레임워크가 기본 `RouterConfig`를 합성합니다. prompt, 라우트 목록, 설명, fallback 동작을 바꿔야 할 때만 명시적으로 제공하세요. `default_intents`를 설정하면 레거시 사전 분류 경로를 사용합니다.
대화 LLM을 설정하지 않으면 내장 `converse_turn`은 답변을 생성하는 대신 설정 안내 placeholder를 반환합니다.
`@listen("…")`의 문자열은 Python 메서드 이름이 아니라 **router 라우트 레이블**(이벤트 이름)입니다. 라우트 레이블과 메서드 완료 이벤트는 하나의 트리거 namespace를 공유하므로, 핸들러 이름을 라우트와 같게 지정하면 핸들러가 자기 자신을 반복해서 다시 실행합니다.
서로 다른 메서드 이름을 사용하세요. 문서 예제에서는 `handle_*` 접두사를 사용합니다:
```python
@listen("create_video")
def handle_create_video(self) -> str:
"""User wants a new video."""
...
```
메서드 이름을 라우트 레이블과 같게 만들지 마세요:
```python
@listen("create_video")
def create_video(self) -> str: # rejected at flow instantiation
...
```
…그러면 router LLM은 다음을 봅니다:
```
@@ -357,7 +404,7 @@ Routes:
|--------|--------|------|
| `converse` | `converse_turn` | 기본 챗 핸들러. system prompt + 정식 메시지 히스토리와 함께 `ConversationConfig.llm`을 호출합니다. |
| `answer_from_history` | `answer_from_history_turn` | 선택적. `ConversationConfig.answer_from_history_llm`이 설정되어 있고 메시지를 히스토리만으로 답할 수 있을 때 라우팅됩니다. |
| `answer_from_history` | `answer_from_history_turn` | **사용 중단된 호환 라우트.** 이미 정식 기록을 전달받는 `converse`를 사용하세요. |
서브클래스에 같은 이름의 핸들러를 정의하면 어떤 것이든 오버라이드할 수 있습니다.
@@ -367,9 +414,9 @@ Routes:
1. 그래프가 다시 실행되도록 턴 단위 실행 추적(`_completed_methods`, `_method_outputs`)을 초기화합니다 — 이게 없으면 동일 인스턴스에서 반복 `kickoff` 호출 시 `Flow.kickoff_async`가 `inputs={"id": ...}`를 체크포인트 복원으로 간주해 2번째 턴부터 단락 회로가 발생합니다.
2. 사용자 메시지를 `state.messages`에 추가하고 `current_user_message` / `last_user_message`를 설정합니다. `last_intent`는 **이전 턴 값이 유지**되어 router LLM이 신호로 활용할 수 있습니다.
3. `conversation_start` → `route_conversation` → 선택된 `@listen` 핸들러 순으로 실행됩니다.
3. 사용자 정의 `@start` 메서드(있는 경우)를 실행한 다음 내장 start/router인 `route_conversation`을 거쳐 선택된 `@listen` 핸들러를 실행합니다. `route_conversation`은 재정의 가능한 `conversation_start()` 헬퍼를 호출합니다.
4. router는 결정을 `state.last_intent`에 저장합니다 (다음 턴의 router 컨텍스트에서 보입니다).
5. 핸들러가 문자열을 반환했지만 `append_assistant_message`를 직접 호출하지 않았다면, `handle_turn`이 대신 추가해 줍니다.
5. 핸들러가 문자열을 반환했지만 `append_assistant_message`를 직접 호출하지 않았다면, `handle_turn`이 대신 추가한 뒤 갱신된 `state.messages`를 persist합니다. `@persist` 복원 시 assistant 턴이 포함됩니다.
채팅 메시지에는 `handle_turn()`을 호출하세요. `kickoff(inputs={"id": ...})`를 직접 호출하면 대화형 턴 래퍼 없이 flow 그래프가 실행됩니다.
@@ -390,6 +437,8 @@ flow.chat()
4. 어시스턴트 결과를 출력합니다.
5. `finally` 블록에서 지연된 세션 trace를 finalize합니다.
`chat(defer_trace_finalization=True)`는 REPL 동안 인스턴스의 지연 플래그를 임시로 활성화하고 종료할 때 이전 값으로 복원합니다.
주입 가능한 I/O로 터미널 동작을 커스터마이즈할 수 있습니다:
```python
@@ -408,6 +457,12 @@ flow.chat(
매 라우팅 결정마다 사이드 이펙트(이벤트 버스 셋업, 텔레메트리)를 실행하려면 `route_turn`을 오버라이드하세요:
```python
from typing import Any
from crewai import Flow
from crewai.flow import ConversationState
class SupportFlow(Flow[ConversationState]):
conversational = True
@@ -416,7 +471,7 @@ class SupportFlow(Flow[ConversationState]):
LLM router를 완전히 우회하고 프로그램 방식으로 라우트를 선택하려면 `route_turn`에서 비어 있지 않은 문자열을 반환하세요. falsy 값을 반환해도 오버라이드에서 `_route_with_config()`가 호출되지는 않습니다. 대신 현재 턴의 사전 분류된 intent, 설정된 경우 사용 중단된 `answer_from_history` 호환 경로, 마지막으로 `converse` 순으로 fallback합니다. 이전 턴의 `last_intent`는 router 컨텍스트에서 사용할 수 있지만 fallback으로 다시 실행되지는 않습니다.
`ConversationConfig.visible_agent_outputs`로 특정 에이전트의 private 결과를 전역적으로 public으로 승격할 수 있습니다 (`"all"` 또는 이름 리스트).
## JSON/YAML로 대화형 플로우 선언하기
[선언적 Flow](/edge/ko/concepts/cli)도 대화형으로 만들 수 있습니다. 최상위 `conversational` 블록을 추가하고 라우트 레이블을 `listen`하는 메서드로 자체 라우트를 선언하세요:
```yaml
schema: crewai.flow/v1
name: SupportFlow
conversational:
system_prompt: You are a terse support assistant.
llm: gpt-4o-mini
router:
llm: gpt-4o-mini
methods:
handle_order:
description: Order status, shipping and delivery questions.
listen: order
do:
call: agent
with:
role: Support specialist
goal: Answer order questions accurately
backstory: Knows the fulfilment pipeline.
input: "${state.current_user_message}"
```
블록 선언 자체가 opt-in이며 `enabled`의 기본값은 `true`입니다. 설정은 유지하면서 채팅을 끄려면 `enabled: false`로 지정하세요. 이 경우 내장 메서드 합성도 비활성화되므로 선언에 일반 비대화형 그래프를 제공해야 합니다.
세 가지가 자동으로 제공됩니다:
| 제공 항목 | 설명 |
|----------|--------|
| 내장 그래프 | `route_conversation`, `converse_turn`, `end_conversation`이 자동으로 추가됩니다. 사용 중단된 `answer_from_history_turn`은 호환성을 위해 유지됩니다. 같은 이름 중 하나로 메서드를 선언하면 재정의됩니다. |
| 대화 상태 | `state` 블록이 없으면 `ConversationState`가 사용됩니다. Pydantic `ref` 또는 `json_schema` state는 대화형 필드와 자동으로 합성되며 `ConversationState`를 상속할 필요가 없습니다. |
| 라우트 카탈로그 | 내부 라우트를 제외하고 `listen` 레이블이 있는 비-router 메서드에서 추론됩니다. 설명에는 위 우선순위가 적용되며 명시적인 `router.routes`로 선택지를 제한할 수 있습니다. |
선언적 `llm`, `router.llm`, `intent_llm` 필드는 모델 id 또는 `{model: openai/gpt-4o-mini, max_tokens: 512}` 같은 설정 mapping을 받습니다. `conversational` 블록은 `default_intents`, `visible_agent_outputs`, `defer_trace_finalization`과 위에 나온 `RouterConfig` 필드도 지원합니다. 사용 중단된 `answer_from_history_prompt` / `answer_from_history_llm` 선언은 호환성을 위해 계속 허용됩니다.
클래스 기반 대화형 플로우와 동일한 턴 API로 Python에서 실행합니다:
```python
from crewai.flow import Flow
flow = Flow.from_declaration(path="flow.yaml")
try:
flow.handle_turn("Where is my order?", session_id="session-1")
finally:
flow.finalize_session_traces()
```
### 라우트 이름 짓기
라우트 레이블과 메서드 이름은 하나의 트리거 네임스페이스를 공유하므로, 핸들러 이름이 자신이 listen하는 라우트와 같으면 안 됩니다 — `create_video`가 `create_video`를 listen하면 플로우 생성 시 거부됩니다. `handle_*` 접두사를 사용하세요.
### 선언으로 표현할 수 없는 것
| 표현 불가 | 대신 사용 |
|-----------------|-------------|
| 살아 있는 `LLM` 인스턴스나 커스텀 `BaseLLM` | 모델 id 문자열 또는 정적 설정 mapping |
| 살아 있는 모델 클래스로서의 `router.response_format` | python ref로 클래스를 지정하세요: `response_format: {python: my_project.schemas.ConversationRoute}`. 생략하면 프레임워크가 생성합니다 |
`crewai run`은 선언적 대화형 Flow에 대해 Python 대화형 Flow와 같은 채팅 TUI를 엽니다. 채팅 루프에는 터미널이 필요하므로 headless 실행은 단일 턴을 실행하는 대신 안내와 함께 0이 아닌 코드로 종료됩니다. 이런 환경에서는 Python의 `handle_turn()` 또는 `stream_turn()`으로 실행하세요. `human_feedback:` 블록이 있는 선언적 메서드(Python: `@human_feedback`)는 터미널 REPL에서 실행됩니다. 런타임이 TUI가 처리할 수 없는 블로킹 prompt로 feedback을 수집하기 때문입니다. 대화형 Flow에서는 `--inputs`를 받지 않습니다. 각 턴의 입력은 사용자가 입력하는 메시지이며 id로 세션을 재개하는 기능은 아직 CLI에 연결되지 않았습니다. 필요하면 Python에서 `flow.handle_turn(message, session_id=...)`을 사용하세요.
`flow.chat()`이 `finalize_session_traces()`를 대신 호출합니다. `handle_turn()`이나 `kickoff(...)`로 직접 루프를 소유하는 경우, 세션이 끝날 때 `finalize_session_traces()`를 호출하세요.
`flow.chat()`이 `finalize_session_traces()`를 대신 호출합니다. `handle_turn()`으로 직접 루프를 소유하는 경우 세션이 끝날 때 `finalize_session_traces()`를 호출하세요.
`suppress_flow_events=True`는 Rich 콘솔 패널만 숨깁니다. trace 및 method 이벤트는 계속 발생합니다.
`suppress_flow_events=True`는 Rich 콘솔 패널을 숨기고 메서드 실행 이벤트를 억제합니다. Flow start/finish 이벤트는 계속 발생하므로 바깥쪽 Flow 수명 주기는 추적할 수 있지만 개별 메서드 span은 생략됩니다.
### 대화형 `Flow` trace 수명 주기
실험적 [대화형 `Flow`](#대화형-flow-실험적)는 동일한 tracing 수명 주기를 따릅니다. `defer_trace_finalization` 기본값이 `True`이므로 각 `handle_turn()`이 세션 trace를 열어 둡니다. 세션 끝에서 항상 finalize하세요 — REPL/루프를 `try/finally`로 감싸고 종료 시 `flow.finalize_session_traces()`를 호출하세요. 호출하지 않으면 batch가 열린 채 남아 마지막 대화가 export되지 않을 수 있습니다.
[대화형 `Flow`](#대화형-flow)는 동일한 tracing 수명 주기를 따릅니다. `defer_trace_finalization` 기본값이 `True`이므로 각 `handle_turn()`은 세션 trace를 열린 상태로 유지합니다. 지연된 턴은 턴별 `flow_failed`도 억제합니다. 턴 오류나 세션 중단이 발생하면 세션을 명시적으로 finalize하세요. 그러면 턴별 `FlowFailed` 이벤트 대신 세션 수준 `FlowFinished` 이벤트로 batch가 닫힙니다. REPL/루프는 항상 `try/finally`로 감싸고 종료 시 `flow.finalize_session_traces()`를 호출하세요. 호출하지 않으면 trace batch가 열린 채 남아 최종 대화가 export되지 않을 수 있습니다.
## 스트리밍
`Flow` 클래스에 `stream = True`. `kickoff(...)`가 표준 이벤트 버스를 통해 `assistant_delta` 등 이벤트를 발생시킵니다.
대화형 UI에서는 `stream_turn()`을 사용하고 순서가 보장된 `StreamFrame` 객체를 순회하세요:
```python
stream = flow.stream_turn("Where is my order?", session_id=session_id)
with stream:
for frame in stream.events:
if frame.channel == "llm" and frame.type == "llm_stream_chunk":
print(frame.content, end="", flush=True)
reply = stream.result
```
비대화형 Flow에서는 `stream = True`로 설정하면 `kickoff()`가 `StreamSession`을 반환합니다. `handle_turn()`을 사용할 때 `flow.stream = True`로 설정하지 마세요. 대화형 스트리밍 수명 주기는 `stream_turn()`이 관리합니다.
## import
@@ -465,10 +600,15 @@ from crewai.flow import (
router,
start,
)
from crewai.flow.conversation import prepare_conversational_turn
from crewai.flow import (
ConversationConfig,
ConversationState,
RouterConfig,
)
```
## 참고
- [Flow 상태 관리 마스터하기](/ko/guides/flows/mastering-flow-state)
description: CopilotKit Channels SDK와 관리형 Intelligence 플랫폼으로 동일한 CrewAI 에이전트를 Slack 또는 Teams 봇으로 실행하세요.
icon: messages
mode: "wide"
---
## 사용자가 이미 있는 곳에서 만나세요
[Overview](/edge/ko/guides/frontend/overview)에서 만든 CrewAI 에이전트는 반드시 웹 앱 뒤에서만 동작할 필요가 없습니다. 동일한 Crew 또는 Flow를 메시징 플랫폼 안에서 봇으로 실행할 수 있습니다. 다시 빌드할 필요도, 에이전트 로직을 두 번 복사할 필요도 없습니다. 에이전트는 [AG-UI 프로토콜](https://docs.ag-ui.com)을 통해 그대로 노출되고, **channel**이 Slack 또는 Microsoft Teams에서 이를 구동합니다.
CopilotKit의 [Channels SDK](https://docs.copilotkit.ai/slack)가 그 channel을 제공합니다. 작은 런타임에 `createChannel`을 선언하고 이를 CrewAI 에이전트에 연결하면, CopilotKit의 관리형 **Intelligence** 플랫폼이 메시징 제공자와의 연결을 중개합니다.
<Note>
이 섹션의 나머지 내용과 달리 Channels는 **셀프 호스팅되지 않습니다**. Channels는 **CopilotKit Intelligence**를 통해 실행되며, 이는 설계상 Channels에 필수적인 서비스입니다(무료 티어 제공). Intelligence는 플랫폼 연결과 자격 증명을 보관하고, 각 플랫폼 이벤트를 수신하며, 해당 턴을 여러분의 channel 프로세스로 전달합니다. 여러분의 프로세스는 에이전트를 실행하고 응답을 다시 스트리밍합니다. Slack은 Intelligence 대시보드에서 한 번만 구성하면 되며, 플랫폼 자격 증명은 결코 여러분의 프로세스로 들어오지 않습니다. 에이전트, 도구, 상태는 온전히 여러분의 것으로 유지됩니다.
</Note>
## 어떻게 맞물리는가
CrewAI 에이전트 서버에 관한 것은 아무것도 바뀌지 않습니다. Overview에서와 똑같이 AG-UI를 통해 Crew 또는 Flow를 계속 제공합니다. 여러분이 추가하는 것은 `@copilotkit/channels`로 빌드된 별도의 장시간 실행 Node 프로세스입니다. 이 프로세스는 `CopilotRuntime`에 channel을 등록하고, Intelligence에 연결하며, 메시지가 도착할 때마다 에이전트를 실행합니다.
```
Slack / Teams ──► CopilotKit Intelligence ──► channel process (Node) ──► CrewAI server (AG-UI) ──► Crew / Flow
```
channel 프로세스는 Intelligence 게이트웨이에 대한 지속적인 연결을 유지하므로, 장시간 실행되는 호스트가 필요합니다. 서버리스 요청 핸들러는 그 연결을 소유할 수 없습니다. CrewAI 서버는 동시에 Overview의 웹 프론트엔드를 계속 제공할 수 있습니다. 웹 앱과 channel은 하나의 AG-UI 엔드포인트에 연결된 두 개의 클라이언트일 뿐입니다.
## 통합 가이드
<Steps>
<Step title="Channels 패키지 설치">
Channels SDK는 모든 것이 포함되어 있습니다. 모든 플랫폼이 하나의 패키지로 제공되며, 플랫폼별로 설치할 어댑터가 없습니다. channel을 호스팅하는 런타임 및 CrewAI AG-UI 클라이언트와 함께 다음을 추가하세요:
[CopilotKit 대시보드](https://docs.copilotkit.ai/slack)에서 Channel을 생성하고 Slack을 연결하세요. Intelligence가 Slack 앱 생성 과정을 안내하고 그 자격 증명을 보관합니다. 그러면 여러분의 프로세스를 위한 두 개의 환경 변수가 남으며, 둘 다 대시보드에서 얻습니다:
```bash
export INTELLIGENCE_API_KEY=... # authenticates the runtime with Intelligence (free tier available)
export INTELLIGENCE_CHANNEL_ID=... # the Channel ID, matched by createChannel({ name })
```
</Step>
<Step title="channel 정의">
`createChannel`은 channel을 선언하고 에이전트를 연결합니다. 각 대화가 자신만의 세션을 갖도록 에이전트를 스레드별 팩토리로 빌드하되, Overview가 웹 런타임에서 사용하는 것과 동일한 `CrewAIAgent`를 여러분의 AG-UI 엔드포인트를 가리키도록 설정하세요. `identifyUser: "platform"`은 Intelligence가 각 플랫폼 사용자를 안정적인 신원에 매핑하도록 합니다.
```ts
// channel.ts
import { createChannel } from "@copilotkit/channels";
import { CrewAIAgent } from "@ag-ui/crewai";
const channel = createChannel({
name: process.env.INTELLIGENCE_CHANNEL_ID!, // must match the Channel ID in Intelligence
identifyUser: "platform",
// A fresh agent per conversation, pointed at your CrewAI AG-UI endpoint.
agent: (threadId) => {
const agent = new CrewAIAgent({ url: "http://localhost:8000/recipe" });
agent.threadId = threadId;
return agent;
},
});
// A mention subscribes the thread and runs the agent; afterwards every message
// in a subscribed thread runs it without needing another mention.
channel.onMention(async ({ thread }) => {
await thread.subscribe();
await thread.runAgent();
});
channel.onMessage(async ({ thread }) => {
if (await thread.isSubscribed()) await thread.runAgent();
});
export { channel };
```
</Step>
<Step title="런타임에 channel 등록">
Intelligence 게이트웨이와 여러분의 channel로 `CopilotRuntime`을 생성한 다음, `createCopilotNodeListener`로 이를 제공하세요. `agents` 맵은 비어 있는 상태로 둡니다. channel이 자신의 에이전트를 제공하기 때문입니다. 잘못된 구성이 시작 시 명확하게 실패하도록 channel이 준비될 때까지 기다리세요.
```ts
// server.ts
import { createServer } from "node:http";
import { CopilotRuntime, CopilotKitIntelligence } from "@copilotkit/runtime/v2";
import { createCopilotNodeListener } from "@copilotkit/runtime/v2/node";
import { channel } from "./channel";
const runtime = new CopilotRuntime({
agents: {}, // the channel supplies its own agent; no web-facing agents needed
intelligence: new CopilotKitIntelligence({
apiKey: process.env.INTELLIGENCE_API_KEY!, // free tier available
Slack 또는 Teams에서 봇을 멘션하면 Crew 또는 Flow를 실행하고 응답을 스레드로 다시 스트리밍합니다. 스레드는 구독된 상태로 유지되므로 후속 메시지는 또다시 멘션할 필요 없이 실행됩니다.
</Step>
</Steps>
## 이벤트 모델
channel은 핸들러로 플랫폼 이벤트에 반응하며, 각 핸들러는 몇 가지 메서드로 구동하는 `thread`를 받습니다:
- **`channel.onMention`**은 사용자가 봇을 @-멘션할 때 발생합니다. `thread.subscribe()`를 호출해 스레드에 참여한 다음, `thread.runAgent()`로 멘션에 대해 CrewAI 에이전트를 실행하세요.
- **`channel.onMessage`**는 봇이 볼 수 있는 스레드의 모든 메시지에서 발생합니다. `thread.isSubscribed()`로 게이트를 걸어 에이전트가 참여한 곳에서만 응답하도록 한 다음, `thread.runAgent()`를 호출하세요.
- **`thread.runAgent()`**는 현재 턴에 대해 연결된 CrewAI 에이전트를 실행하고 그 출력을 channel로 다시 스트리밍합니다. 에이전트가 실행할 텍스트를 재정의하려면 `{ prompt }`를 전달하세요.
여러분의 에이전트는 일반적인 AG-UI `RunAgentInput`을 받고 일반적인 AG-UI 이벤트를 방출합니다. 플랫폼 메커니즘은 channel 뒤에 머무르므로, 동일한 Crew 또는 Flow가 모든 플랫폼에서 변경 없이 실행됩니다. channel은 환영 인사, 인터럽트, 명령, 반응, 모달을 위한 핸들러도 노출합니다. 전체 표면은 [`Channel` 레퍼런스](https://docs.copilotkit.ai/reference/channels/classes/Channel)를 참조하세요.
## 플랫폼 지원
관리형 Intelligence 경로는 현재 **Slack**과 **Microsoft Teams**를 지원합니다. 동일한 channel 코드가 양쪽에서 실행되며, `message.platform` / `thread.platform`이 원래의 출처를 보고합니다. 다른 플랫폼(Discord, Telegram, WhatsApp)은 관리형 경로가 아니라 개발자가 운영하는 **direct adapters**를 통해 연결됩니다. 여러분 자신의 프로세스가 플랫폼 자격 증명과 전송을 보유합니다. 현재 지원 플랫폼 목록과 플랫폼별 설정은 [CopilotKit Channels 문서](https://docs.copilotkit.ai/slack)를 확인하세요.
description: CopilotKit과 AG-UI 프로토콜로 CrewAI 에이전트를 위한 인터랙티브 사용자 인터페이스를 구축하세요.
icon: browser
mode: "wide"
---
## 에이전트에 사용자 인터페이스를 부여하세요
CrewAI는 여러분의 에이전트를 실행합니다. [CopilotKit](https://copilotkit.ai)은 그 에이전트에 프론트엔드를 제공합니다. 이 둘을 함께 사용하면 사용자가 Crew 또는 Flow와 대화하고, 실시간으로 작동하는 모습을 지켜보고, 그 결정을 승인하며, 출력을 장황한 텍스트 대신 살아 있는 UI로 렌더링하여 볼 수 있는 애플리케이션을 구축할 수 있습니다.
이 둘은 [AG-UI 프로토콜](https://docs.ag-ui.com)을 통해 연결됩니다. `ag-ui-crewai` 패키지는 어떤 Crew나 Flow든 AG-UI 엔드포인트로 노출합니다. CopilotKit의 React 훅과 컴포넌트가 그 엔드포인트를 소비합니다. 이를 통해 채팅 상자를 훨씬 뛰어넘는 경험이 열립니다:
이 가이드는 **셀프 호스팅** 경로를 다룹니다. `ag-ui-crewai`로 CrewAI 에이전트 서버를 직접 실행하며, 관리형 서비스 없이 로컬에서 동작합니다. CopilotKit은 호스팅된 스레드와 인스펙터를 갖춘 **관리형** 경로(CopilotKit Cloud / Enterprise Intelligence)도 제공합니다. 그 방식을 원한다면 [CopilotKit CrewAI 퀵스타트](https://docs.copilotkit.ai/crewai-crews/quickstart)를 참조하세요. 이 섹션의 프론트엔드 코드는 어느 쪽이든 동일합니다. 에이전트를 호스팅하고 등록하는 방식만 다릅니다.
</Note>
<Note>
CrewAI는 AG-UI 뒤에서 세 가지 형태로 실행됩니다: 일반 **Flows**(이 가이드 전반에서 사용), **[Conversational Flows](/edge/en/guides/frontend/conversational-flows)**(네이티브, 세션 인식, 턴 기반, 완전한 기능 동등성), 그리고 **Crews**(기본 채팅). 이 섹션의 프론트엔드는 이들 전반에서 동일합니다. 백엔드 작성과 등록만 다릅니다.
</Note>
## 통합 가이드
<Steps>
<Step title="AG-UI를 통해 에이전트 제공">
통합 패키지를 CrewAI 프로젝트에 설치하세요:
```bash
pip install ag-ui-crewai
```
FastAPI 앱에서 에이전트를 노출하세요. Flows는 `add_crewai_flow_fastapi_endpoint`를, Crews는 `add_crewai_crew_fastapi_endpoint`를 사용합니다. 원하는 만큼 등록할 수 있으며, 각각 자신의 경로에 배치됩니다.
<CodeGroup>
```python Flow
# server.py
from fastapi import FastAPI
from ag_ui_crewai.endpoint import add_crewai_flow_fastapi_endpoint
from my_agents.recipe_flow import RecipeFlow
app = FastAPI(title="CrewAI Agent Server")
add_crewai_flow_fastapi_endpoint(
app=app,
flow=RecipeFlow(),
path="/recipe",
)
```
```python Crew
# server.py
from fastapi import FastAPI
from ag_ui_crewai.endpoint import add_crewai_crew_fastapi_endpoint
from my_agents.research_crew import ResearchCrew
app = FastAPI(title="CrewAI Agent Server")
add_crewai_crew_fastapi_endpoint(
app=app,
crew=ResearchCrew().crew(),
path="/research",
)
```
</CodeGroup>
실행하세요:
```bash
uvicorn server:app --port 8000
```
<Note>
서버를 시작하기 전에 LLM 제공자를 위한 환경 변수(예: `OPENAI_API_KEY`)를 설정하세요.
이 가이드는 [OpenInference](https://github.com/openinference/openinference) SDK를 통해 OpenTelemetry를 사용하여 **Arize Phoenix**를 **CrewAI**와 통합하는 방법을 보여줍니다. 이 가이드를 완료하면 CrewAI agent를 추적하고 agent를 쉽게 디버그할 수 있습니다.
이 가이드는 [OpenInference](https://github.com/openinference/openinference) SDK를 통해 OpenTelemetry를 사용하여 **Arize Phoenix**를 **CrewAI**와 통합하는 방법을 보여줍니다. 이 가이드를 완료하면 CrewAI agent를 추적하고 agent 동작을 디버그할 수 있습니다.
> **Arize Phoenix란?** [Arize Phoenix](https://phoenix.arize.com)는 AI 애플리케이션을 위한 추적 및 평가 기능을 제공하는 LLM 가시성(observability) 플랫폼입니다.
> **Arize Phoenix란?** [Arize Phoenix](https://arize.com/phoenix/)는 [Arize AI](https://arize.com/?utm_source=crewai-docs&utm_medium=partner&utm_campaign=partner-docs&utm_content=observability-arize-phoenix)의 오픈소스 observability 및 evaluation 옵션입니다. 로컬에서 실행하거나 self-host하려는 경우 Phoenix를 사용하세요. 프로덕션 AI 시스템을 위한 managed cloud 또는 enterprise self-hosted 플랫폼이 필요하면 [Arize AX](https://arize.com/products/ax/)를 사용하세요.
[](https://www.youtube.com/watch?v=Yc5q3l6F7Ww)
os.environ["PHOENIX_COLLECTOR_ENDPOINT"] = "https://app.phoenix.arize.com" # Phoenix Cloud, change this to your own endpoint if you are using a self-hosted instance
os.environ["PHOENIX_COLLECTOR_ENDPOINT"] = "https://app.phoenix.arize.com" # Change this to your own endpoint if you are using a self-hosted instance
os.environ["OPENAI_API_KEY"] = OPENAI_API_KEY
os.environ["SERPER_API_KEY"] = SERPER_API_KEY
```
@@ -133,7 +133,7 @@ print(result)
에이전트를 실행한 후, Phoenix에서 CrewAI 애플리케이션에 의해 생성된 트레이스를 볼 수 있습니다. 에이전트 상호작용과 LLM 호출의 상세한 단계가 표시되어 AI 에이전트를 디버깅하고 최적화하는 데 도움이 됩니다.
Phoenix Cloud 계정에 로그인한 다음 `project_name` 파라미터에서 지정한 프로젝트로 이동하세요. 모든 에이전트 상호작용, 도구 사용 및 LLM 호출이 포함된 트레이스의 타임라인 보기를 확인할 수 있습니다.
Phoenix 프로젝트를 열고 `project_name` 파라미터에서 지정한 프로젝트로 이동하세요. 모든 에이전트 상호작용, 도구 사용 및 LLM 호출이 포함된 트레이스의 타임라인 보기를 확인할 수 있습니다.

CrewAI는 Crews와 Flows를 실시간으로 모니터링하고 디버깅할 수 있는 내장 추적 기능을 제공합니다. 이 가이드는 CrewAI의 통합 관측 가능성 플랫폼을 사용하여 **Crews**와 **Flows** 모두에 대한 추적을 활성화하는 방법을 보여줍니다.
> **CrewAI Tracing이란?** CrewAI의 내장 추적은 agent 결정, 작업 실행 타임라인, 도구 사용, LLM 호출을 포함한 AI agent에 대한 포괄적인 관측 가능성을 제공하며, 모두 [CrewAI AMP 플랫폼](https://app.crewai.com)을 통해 액세스할 수 있습니다.
> **CrewAI Tracing이란?** CrewAI의 내장 추적은 agent 결정, 작업 실행 타임라인, 도구 사용, LLM 호출을 포함한 AI agent에 대한 포괄적인 관측 가능성을 제공하며, 모두 [CrewAI AMP 플랫폼](https://app.crewai.com)을 통해 액세스할 수 있습니다. 추적은 [텔레메트리](/ko/telemetry)와 별도로 관리됩니다.
@@ -22,7 +22,8 @@ CrewAI는 익명 텔레메트리를 활용하여 사용 통계를 수집하며,
`share_crew` 기능이 활성화되면, 보다 심층적인 통찰을 제공하기 위해 작업 설명, 에이전트의 배경 이야기나 목표, 기타 특정 속성 등 상세한 데이터가 수집됩니다.
이 확대된 데이터 수집에는 사용자가 crew나 작업에 개인정보를 포함한 경우, 개인정보가 포함될 수 있습니다.
사용자는 `share_crew`를 활성화하기 전에 crew와 작업의 내용을 신중하게 검토해야 합니다.
사용자는 환경 변수 `CREWAI_DISABLE_TELEMETRY`를 `true`로 설정하거나, `OTEL_SDK_DISABLED`를 `true`로 설정하여 텔레메트리를 비활성화할 수 있습니다(후자의 경우 전체 OpenTelemetry 계측이 전역에서 비활성화된다는 점에 유의하십시오).
사용자는 `CREWAI_DISABLE_TELEMETRY`를 `true`, `1`, `yes`, `on` 중 하나로 설정하여 CrewAI 텔레메트리를 비활성화할 수 있습니다(대소문자 무관). 같은 값의 `OTEL_SDK_DISABLED`도 CrewAI exporter를 끕니다. 프로세스 내 다른 OpenTelemetry 계측을 끄려면 OpenTelemetry SDK는 여전히 `true`만 인식합니다.
AMP 추적은 [Tracing](/ko/observability/tracing)에서 별도로 다룹니다.
| 예 | CrewAI 및 Python 버전 | 소프트웨어 버전을 추적합니다. 예: CrewAI v1.2.3, Python 3.8.10. 개인 정보 없음. |
| 예 | Crew 메타데이터 | 랜덤으로 생성된 키 및 ID, 프로세스 유형(예: 'sequential', 'parallel'), 메모리 사용 플래그(boolean, true/false), 작업 수, 에이전트 수가 포함됩니다. 모두 비개인 정보입니다. |
| 예 | Crew 메타데이터 | 랜덤으로 생성된 키 및 ID, 프로세스 유형(예: 'sequential', 'parallel'), 메모리 사용 플래그(boolean, true/false), 실행에 입력이 전달되었는지를 나타내는 플래그(boolean, true/false — 입력 키나 값 자체는 포함되지 않으며, 이는 `share_crew`가 활성화된 경우에만 수집됩니다), 작업 수, 에이전트 수가 포함됩니다. 모두 비개인 정보입니다. |
| 예 | 에이전트 데이터 | 랜덤으로 생성된 키 및 ID, 역할 이름(개인 정보 포함 불가), boolean 설정(상세 출력, 위임 가능, 코드 실행 허용), 최대 반복 횟수, 최대 RPM, 최대 재시도 제한, LLM 정보(LLM 속성 참조), 도구 이름 목록(개인 정보 포함 불가) 포함. 개인 정보 없음. |
| 예 | 작업 메타데이터 | 랜덤으로 생성된 키 및 ID, boolean 실행 설정(async_execution, human_input), 관련 에이전트 역할 및 키, 도구 이름 목록이 포함됩니다. 모두 비개인 정보입니다. |
| 예 | 도구 사용 통계 | 도구 이름(개인 정보 포함 불가), 사용 시도 횟수(정수), 사용된 LLM 속성이 포함됩니다. 개인 정보 없음. |
| 예 | 테스트 실행 데이터 | crew의 랜덤 생성 키와 ID, 반복 횟수, 사용된 모델명, 품질 점수(실수), 실행 시간(초 단위)이 포함됩니다. 모두 비개인 정보입니다. |
| 예 | 작업 라이프사이클 데이터 | 생성 및 실행 시작/종료 시각, crew 및 작업 식별자가 포함됩니다. 타임스탬프를 포함한 span으로 저장됩니다. 개인 정보 없음. |
| 예 | 작업 라이프사이클 데이터 | 생성 및 실행 시작/종료 시각, crew 및 작업 식별자, 그리고 작업의 성공 또는 실패 여부가 포함됩니다. 작업이 실패하면 실패를 집계하고 진단할 수 있도록 예외의 **클래스 이름**(예: `TimeoutError`)이 기록되며, 프롬프트·모델 출력·파일 경로·자격 증명이 포함될 수 있는 오류 메시지는 결코 기록되지 않습니다. 타임스탬프를 포함한 span으로 저장됩니다. 개인 정보 없음. |
| 예 | LLM 속성 | LLM의 이름, model_name, 모델, top_k, temperature 및 클래스명이 포함됩니다. 모두 기술적이고 비개인 정보입니다. |
| 예 | crewAI CLI를 통한 Crew 배포 시도 | 포함 항목: 배포가 시도되고 있다는 사실과 crew id, 로그를 가져오려고 하는지 여부, 그리고 배포가 CLI 명령에서 시작되었는지 실행 TUI에서 시작되었는지 여부. 프로젝트나 crew의 내용은 기록되지 않습니다. 개인 정보 없음. |
| 예 | 실행 환경 | 포함: 프로세스를 실행 중인 AI 코딩 어시스턴트(있는 경우, `claude_code`, `codex`, `cursor`, `unknown` 등 고정 목록 중 하나), 프로세스가 실행되는 위치(`ci`, `container`, `serverless`, `interactive` 등 고정 목록 중 하나), 그리고 `pyproject.toml`에 설정된 경우 `project_id`. 감지는 알려진 환경 변수의 설정 여부만 확인하며 값은 읽지 않음. 개인 데이터 없음. |
| 예 | crewAI CLI를 통한 프로젝트 생성 | 포함 항목: `crewai create`로 새 프로젝트가 생성되었다는 사실, 그 종류(`crew`, `json_crew` 또는 `flow`), 그리고 그 새 프로젝트에 발급되어 해당 프로젝트의 `pyproject.toml`에 기록된 프로젝트 ID. 이는 새 프로젝트 자체의 ID이며, 명령을 실행한 디렉터리의 `project_id`와는 별개로 기록됩니다 — 두 값은 다를 수 있습니다. 프로젝트 이름, 파일 내용, 코드는 기록되지 않습니다. 개인 정보 없음. |
| 예 | crewAI CLI를 통한 Crew 배포 시도 | 포함 항목: 배포가 시도되고 있다는 사실과 crew id, 로그를 가져오려고 하는지 여부, 그리고 배포가 CLI 명령에서 시작되었는지 실행 TUI에서 시작되었는지 여부. 배포 생성이 실패하면 실패 범주(`api_4xx`, `network_error`, `user_declined` 등 고정된 목록 중 하나)와 API 응답의 HTTP 상태 코드(있는 경우)가 기록되며, 오류 메시지는 절대 기록되지 않습니다. 프로젝트나 crew의 내용은 기록되지 않습니다. 개인 정보 없음. |
| 예 | 실행 환경 | 포함: 프로세스를 실행 중인 AI 코딩 어시스턴트(있는 경우, `claude_code`, `codex`, `cursor`, `unknown` 등 고정 목록 중 하나), 프로세스가 실행되는 위치(`ci`, `container`, `serverless`, `interactive` 등 고정 목록 중 하나), `pyproject.toml`에 설정된 경우 `project_id`, 그리고 머신 크기의 대략적인 구간(`1-2`, `3-4`, `5-8`, `9-16`, `17-32`, `33+`, `unknown` 중 하나). 구간은 범위이며 정확한 코어 수는 절대 포함하지 않습니다 — 정확한 코어 수는 아래 환경 정보에서 옵트인한 경우에만 수집됩니다. 크기 구간은 호스트 CPU 수에서 가져오며, 어시스턴트와 실행 위치 감지는 알려진 환경 변수의 설정 여부만 확인하고 값은 읽지 않음. 개인 데이터 없음. |
| 예 | Flow 라이프사이클 신호 | 포함 항목: flow의 시작, 완료 또는 실패 여부, 해당 메서드의 실패 여부, 사람의 입력이나 피드백을 위해 일시 중지되었는지 여부, 해당 시작이 재개된 실행이었는지 여부, 대화 턴의 실패 여부, flow 실행 시간, 그리고 해당 flow가 CrewAI가 내부적으로 실행하는 것인지 사용자가 작성한 것인지 여부. flow 이름은 flow 생성 및 실행에서와 마찬가지로 기록됩니다. flow 또는 해당 메서드가 실패하면 장애 진단을 위해 예외의 **클래스 이름**(예: `TimeoutError`)이 기록되며, 프롬프트·모델 출력·파일 경로·자격 증명이 포함될 수 있는 오류 메시지는 절대 기록되지 않습니다. 메서드 이름과 flow 상태는 절대 기록되지 않습니다. 개인 정보 없음. |
| 예 | 트레이스 공유 신호 | 포함 항목: 트레이스 배치가 CrewAI AMP에 성공적으로 공유되었는지 여부와, 익명으로(계정 생성 전) 공유되었는지 또는 계정에 연결되어 공유되었는지 여부. 모든 span과 마찬가지로 위에서 설명한 실행 환경 속성(구성된 경우 `project_id`, 코딩 어시스턴트, 런타임)도 함께 기록됩니다. 이 행은 공유 텔레메트리만 설명하며 — 트레이스 내용이나 공유된 트레이스 링크로 부여되는 접근 권한은 설명하지 않습니다. 트레이스 내용, 입력, 출력은 이 신호에는 기록되지 않습니다. 트레이스를 공유하기 전에 비밀 정보, 개인 데이터, AMP 편집 및 보존 설정을 검토하세요. |
| 아니오 | 에이전트 확장 데이터 | 목표 설명, 배경 이야기 텍스트, i18n 프롬프트 파일 식별자가 포함됩니다. 사용자들은 텍스트 필드에 개인 정보가 포함되지 않도록 해야 합니다. |
- **summarize**: 선택 사항. 검색된 콘텐츠를 요약할지 여부입니다. 기본값은 `False`입니다.
- **adapter**: 선택 사항. 지식 베이스에 대한 사용자 지정 어댑터입니다. 제공되지 않은 경우 EmbedchainAdapter가 사용됩니다.
- **config**: 선택 사항. 내부 EmbedChain App의 구성입니다.
- **adapter**: 선택 사항. 지식 기반을 위한 사용자 지정 어댑터입니다. 제공하지 않으면 CrewAIRagAdapter가 사용됩니다.
- **config**: 선택 사항. 내부 CrewAI RAG 시스템에 대한 구성입니다. 선택적 `embedding_model`(ProviderSpec) 및 `vectordb`(VectorDbConfig) 키를 포함하는 `RagToolConfig` TypedDict를 허용합니다. 프로그래밍 방식으로 제공된 모든 구성 값은 환경 변수보다 우선합니다.
from crewai.rag.core.base_embeddings_callable import EmbeddingFunction
from crewai.rag.embeddings.providers.custom.types import CustomProviderSpec
class MyEmbeddingFunction(EmbeddingFunction):
def __call__(self, input):
# Your custom embedding logic
return embeddings
embedding_model: CustomProviderSpec = {
"provider": "custom",
"config": {
"embedding_callable": MyEmbeddingFunction
}
}
```
**구성 옵션:**
- `embedding_callable` (type[EmbeddingFunction]): 사용자 지정 임베딩 함수 클래스
**참고:** 사용자 지정 임베딩 함수는 `crewai.rag.core.base_embeddings_callable`에 정의된 `EmbeddingFunction` 프로토콜을 구현해야 합니다. `__call__` 메서드는 입력 데이터를 받아 numpy 배열 목록(또는 정규화할 수 있는 호환 형식)으로 임베딩을 반환해야 합니다. 반환된 임베딩은 자동으로 정규화되고 검증됩니다.
</Accordion>
</AccordionGroup>
### 참고
- **필수**로 표시되지 않은 모든 구성 필드는 선택 사항입니다.
- 일반적으로 API 키는 구성 대신 환경 변수를 통해 제공할 수 있습니다.
- 해당하는 경우 기본값이 표시됩니다.
## 결론
`RagTool`은 다양한 데이터 소스에서 지식 베이스를 생성하고 질의할 수 있는 강력한 방법을 제공합니다. Retrieval-Augmented Generation을 활용하여, 에이전트가 관련 정보를 효율적으로 접근하고 검색할 수 있게 하여, 보다 정확하고 상황에 맞는 응답을 제공하는 능력을 향상시킵니다.
`ScrapeElementFromWebsiteTool`은 CSS 선택자를 사용하여 웹사이트에서 특정 요소를 추출하도록 설계되었습니다. 이 도구는 CrewAI 에이전트가 웹 페이지에서 타겟이 되는 콘텐츠를 스크래핑할 수 있게 하여, 웹페이지의 특정 부분만이 필요한 데이터 추출 작업에 유용합니다.
`ScrapeElementFromWebsiteTool`은 CSS 선택자를 사용하여 웹사이트에서 특정 요소를 추출하도록 설계되었습니다. 이 도구는 CrewAI 에이전트가 웹 페이지에서 타겟이 되는 콘텐츠를 스크래핑할 수 있게 하여, 웹페이지의 특정 부분만이 필요한 데이터 추출 작업에 유용합니다. 가져오기는 CrewAI의 SSRF 안전 HTTP 헬퍼를 거칩니다. 요청된 URL과 모든 리다이렉트 홉이 사설 및 예약 대역(클라우드 메타데이터 포함)에 대해 검사되며, TCP 연결은 그 검사를 통과한 IP에 고정됩니다.
- Inicia o processo de deployment na plataforma CrewAI AMP.
- Após a iniciação bem-sucedida, será exibida a mensagem Deployment created successfully! juntamente com o Nome do Deployment e um Deployment ID (UUID) único.
- O push mantém a origem usada na criação. Adicionar um `origin` git depois não troca um deployment ZIP por git.
- **Status do Deployment**: Você pode verificar o status do seu deployment com:
@@ -919,6 +919,38 @@ Saiba como obter o máximo da configuração do seu LLM:
llm = LLM(model="gpt-4")
```
</Tab>
<Tab title="Erros de Gateway">
<Tip>
Gateways como o OpenRouter retornam `200 OK` assim que o provedor upstream aceita a requisição, então um timeout do provedor chega no corpo da resposta em vez do código de status.
</Tip>
O CrewAI lança a mesma exceção que o código upstream produziria como um status HTTP real, portanto uma falha mascarada é capturada pelo tratamento de retry que você já possui:
result = llm.call("Summarize the incident", response_model=Report)
except openai.InternalServerError as e:
# "z-ai/glm-5.3 via openrouter.ai returned HTTP 200 with an upstream error
# and no choices: The operation was aborted (upstream code 504)"
print(f"Upstream provider failed, safe to retry: {e}")
```
<Warning>
Um `response_model` grande ou profundamente aninhado aumenta a chance de timeouts upstream. Trate esses casos como falhas transitórias do provedor, e não como o modelo produzindo saída estruturada malformada.
</Warning>
</Tab>
<Tab title="Comprimento do Contexto">
<Tip>
Use modelos de contexto expandido para tarefas extensas
@@ -202,13 +202,17 @@ A publicação lê `name`, `description` e `metadata.version` do frontmatter do
### Instalar
Instale uma skill publicada pela sua referência `@org/name`:
Instale uma skill publicada pela sua referência `@org-uuid/name`:
```shell Terminal
crewai skill install @acme/code-review
crewai skill install @your-org-uuid/code-review
```
Dentro de um projeto de crew, a skill é colocada em `./skills/{name}/`; fora de um projeto, vai para o cache compartilhado em `~/.crewai/skills/{org}/{name}/`.
<Note>
Use o **UUID** da sua organização, não o nome — nomes de organização não são únicos, então um nome pode resolver para a organização errada e a instalação falha com um erro de "não encontrado". Execute `crewai org list` para ver o UUID (a coluna `ID`) de cada organização à qual você pertence.
</Note>
Dentro de um projeto de crew, a skill é colocada em `./skills/{name}/`; fora de um projeto, vai para o cache compartilhado em `~/.crewai/skills/{org-uuid}/{name}/`.
Agentes também podem referenciar skills do registro diretamente — elas são resolvidas a partir do cache local (ou do diretório `skills/` do projeto) em tempo de execução:
@@ -217,7 +221,7 @@ agent = Agent(
role="Senior Code Reviewer",
goal="Review pull requests for quality and security issues",
backstory="Staff engineer with expertise in secure coding practices.",
Some files were not shown because too many files have changed in this diff
Show More
Reference in New Issue
Block a user
Blocking a user prevents them from interacting with repositories, such as opening or commenting on pull requests or issues. Learn more about blocking a user.